


WHEN USING AI TO GENERATE PICTURES OR VIDEOS, IF THERE'S ONLY ONE CHARACTER IN THE PICTURE, NO MATTER HOW YOU DESCRIBE IT, AI IS BASICALLY GOOD AT WHAT IT SAYS. BUT AS LONG AS THERE ARE TWO OR MORE CHARACTERS IN THE PICTURE, NO MATTER HOW PRECISE YOUR HINTS ARE, AND HOW DETAILED YOUR ACTION IS, THE CHARACTER IS STILL EXTREMELY DIFFICULT TO CONTROL。
Especially when you're satisfied with the image as a whole, and you have to modify one of them alone, the result will be very uncontrollable — to the left, to the right, to the right, to the right, and even to the perfect. The whole “tick card” process is like opening a blind box, which is extremely laborious and patient。
Today, I don't talk about complex node-linking, but I'm just going to teach you three high-level node techniques, from the point of departure to the bottom of AI. Whether you're using head video models like dream, coven, conch, or Nano Banana Pro, Midjourney, you'll be able to grasp the actions of every character with these three points
Method I: Discarding of " streaming " , splitting with "time/space sense "
BOTTOM THEORY: NOW AI IS NOT STUPID, BUT IT'S "WRONG FOCUS."
MANY PEOPLE THINK AI CAN READ COMPLEX LONG SENTENCES AND SEQUENCES LIKE PEOPLE. IN FACT, THE CURRENT HEAD MODEL (E.G., DREAM, COVEN) IS VERY SEMANTIC, ALTHOUGH IT IS HIGHLY UNDERSTOOD
The low-level characteristic pollution mistake of “dressing a woman's red dress on a man” has long been avoided。
BUT IF YOU INSERT MORE THAN ONE ROLE IN THE SAME SENTENCE, THE A.I. 'S ATTENTION MECHANISM IS "CALCULATIVE DEVIATION' OR "ACTION DILUTION."。
It does not evenly distribute calculus to everyone。
The result is that it can only preserve the movement of one of the characters and turn the other into a static “backboard” or simply ignore the order of your natural language。
Common error method: "Flowing book"
90%'S NEW HANDS MADE THE FATAL MISTAKE OF WRITING ALL THE CHARACTERS AND MOVEMENTS IN THE SAME SENTENCE。
Example of error:
“In a café, the man on the left is drinking coffee, while the woman on the right is dancing happily and then the man stands up and applauds.”
THIS IS A WAY FOR HUMANS TO LOOK SMOOTH, BUT WHEN AI GETS IT, IT OFTEN PRODUCES THE RESULT THAT WOMEN ON THE RIGHT DO DANCE, BUT THE MEN ON THE LEFT, WITH THEIR COFFEE CUPS, ARE ACTING WEIRDLY. AI SIMPLY DOES NOT UNDERSTAND THE COMPLEX TIME-SEQUENCING RHYTHM OF “AT THE SAME TIME” AND “AFTER”。
Correct formulation: Structured “space position” and “time period”
WE NEED TO CLEAR THE FOCUS AND TIMELINE OF THE PICTURE FOR AI IN EXTREMELY RIGID STRUCTURED LANGUAGE。
Video generation (e. g. respiration / conch / dream): Dismantling a lot over timeAI VideoTHE MODEL'S UNDERSTANDING OF “TIME-AXIS LABELS” IS FAR MORE ACCURATE THAN THAT OF NATURAL LANGUAGES SUCH AS “FOLLOW” AND “THEN”. WHEN THE ACTION IS BROKEN DOWN INTO DIFFERENT TIME PERIODS, AI CAN DETERMINE WHO SHOULD FOCUS ON THE CALCULATION OF EACH SECOND。
Correct demonstration:
[0-3 seconds] On the left side, a man in a black suit sits in a chair and drinks coffee with a cup; on the right side, a woman in a red dress is dancing happily。
[4-8 seconds] Dancing by women on the right remains the same; men on the left put coffee cups on the table, stand up and start applauding。
Method II: Disappear traditional masked versions and use "video editor" to target content
bottom theory: semantic replacement vs traditional redrawing
IN THE PAST, WHEN WE WANTED TO MODIFY THE MOVEMENT OF ONE OF THE PEOPLE IN THE VIDEO, THE FIRST REACTION WAS TO FRAME HIM BY PAINTING A MASK. BUT IT'S A BIG PIT IN THE CREATION OF THE AI VIDEO -- IT'S HARD TO GET A DYNAMIC VIDEO MASK THAT FITS EVERY FRAME PERFECTLY, AND IT'S VERY EASY TO GET THE EDGES CHANGED SO THAT THE PERSON IS LIKE A LOW-QUALITY PASTE。
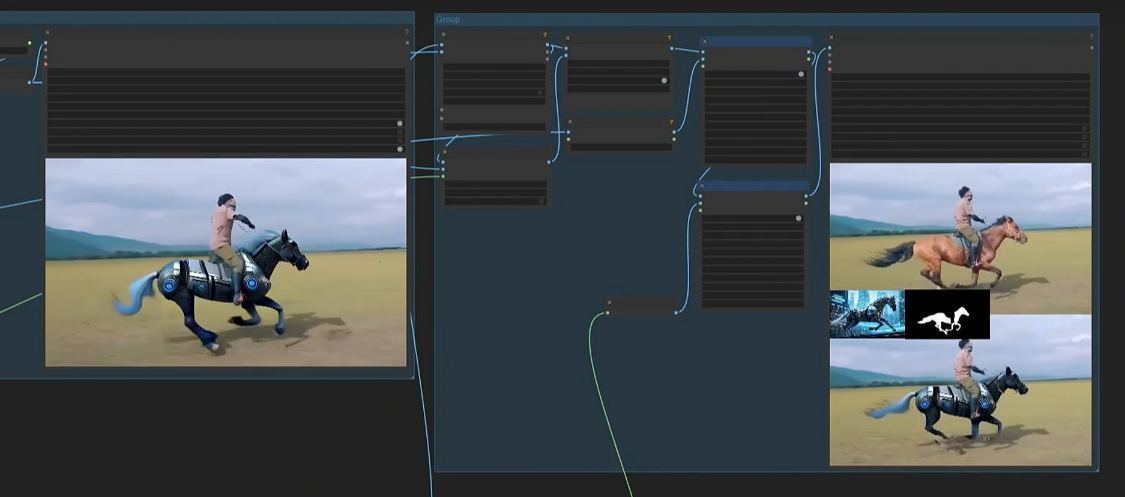
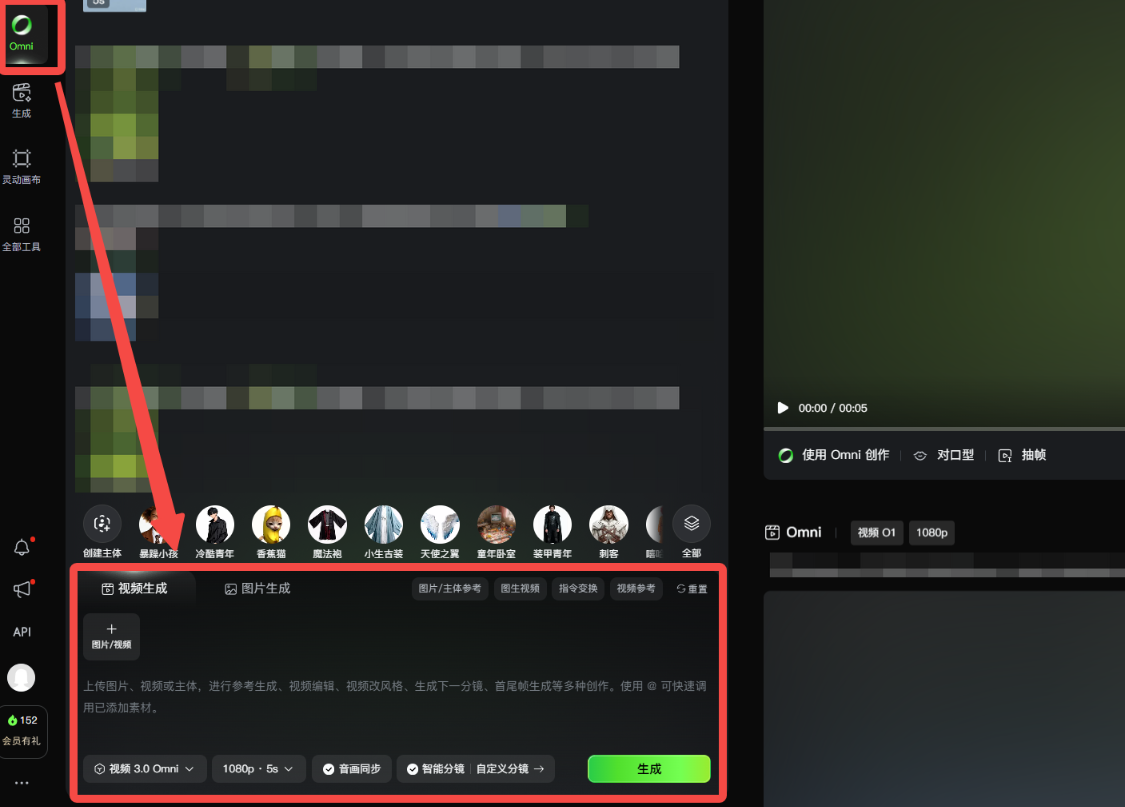
And by 2026, the bottom of the head video model (e.g. DreamSeedance 2.0, Clin Omni) had evolved to "Senith Video Editor". AI can identify "who" in the subspace directly through your natural language, and replaces the action directly with the corresponding pixel feature, without any need for you to do it manually。
Common wrongs: blind-spacing cards or stupid drawings
WHEN YOU'RE SATISFIED WITH THE CHARACTERS ON THE RIGHT SIDE OF THE PICTURE, YOU'RE NOT SATISFIED WITH THE LEFT SIDE: IF YOU JUST ADD "TO THE LEFT MAN'S MOVE" TO THE ORIGINAL HINT AND CLICK TO RECREATE IT, AI REDRAWS THE WHOLE PICTURE AND WIPES OUT ALL THE PEOPLE ON THE RIGHT SIDE THAT YOU'RE ALREADY SATISFIED WITH, AND MAKES YOU LOSE。
Correct formulation: use of original "video editing" to clarify "retention and modification"
We can do a precise “penetration/change” in one sentence, with the editorial functionality embedded in the mainstream tool。
If you are looking for a high-efficiency film (in the case of Violin Omni): Violin Omni has a strong semantic understanding. All you have to do is use [Video Edition] on the original video and enter a sentence with a double lock + change command。
Note: There is an all-powerful formula that must not step on the pit — it must be clearly stated in the reminder “which part is retained”。
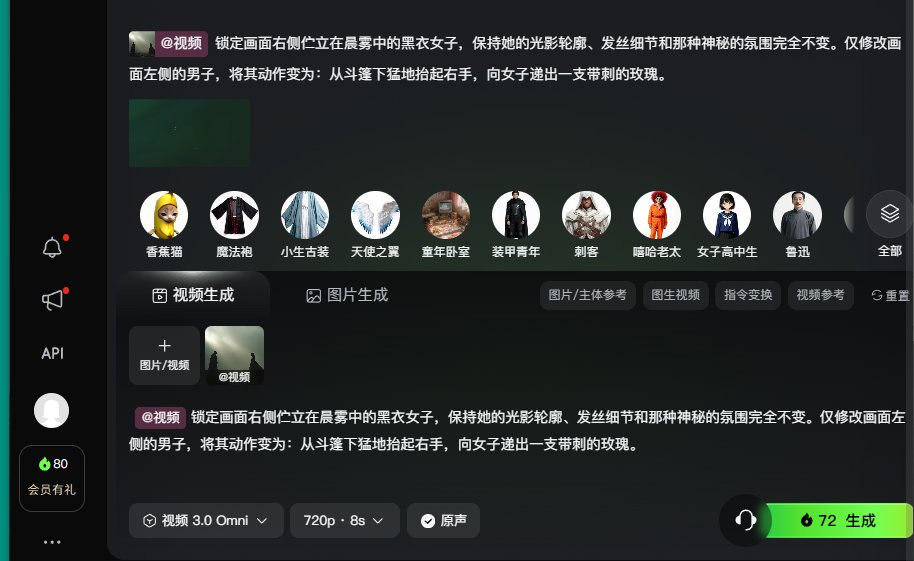
Correct demonstration (replacement of a universal formula):
The black woman, who was standing on the right side of the picture in the morning fog, was locked in her radiance, filament details and the mysterious atmosphere. Only the man on the left side of the picture was modified, and the action was changed to: the right hand was raised from under the cape, and a thorny rose was delivered to the woman。
IF YOU DON'T KEEP IT, THE A.A. WILL ACQUIESCE IN YOUR TOTAL REVERSAL. USE OF GOOD SEMANTIC EDITING NOT ONLY SAVES THE TROUBLE OF PAINTING THE MUZZLES, BUT ALSO PRESERVES THE ENVIRONMENTAL LIGHT AND QUALITY OF THE ORIGINAL VIDEO。
METHOD III: DISASSEMBLY COMPLEX ACTIONS INTO MULTIPLE STAGES
Bottom theory: "Voice of Audio-Visual" game after the power drain
A further reason why many people have failed to control the movement of many people is because the role has been assigned too complex a continuum。
You may argue:
"Seedance 2.0 in today's dream, it seems, "Man pulls out a sword, pushes forward, avoids a woman's attack, then cuts down at 360 degrees in the air."
THAT'S RIGHT, THE A.I.C. IS ALREADY A TERRIBLE THING, AND EVEN IF YOU PUT SO MANY DIFFICULT MOVES IN, THE PERSON'S LIMBS ARE STILL INTACT AND SMOOTH. BUT IF IT DOESN'T FALL, WHY DO WE SPLIT
BECAUSE IF YOU'RE USED TO PUTTING THE ACTION IN A LIST OF BRAINS INTO A LONG SHOT, OR EVEN USING THE ACTION'S "RESULTS" AS A "PROCESS," THE IMAGE LOSES ALL MICRO-EXPRESSIONS AND ACTION DETAILS. IT'S GOING TO BE LIKE A CHEAP GAME OF CG MADE BY A "MONITORED SCOUT" WITH NO TENSION, FULL OF A THICK "AI SWING."。
Common error method: using action lists as film scripts
THE ONLY THING THAT MATTERS IS THAT THE PERSON “DOES WHAT HE DOES” AND IGNORES THE CAMERA “HOW TO SHOOT”. AND YOU'RE NOT ONLY BLIND, BUT YOU'RE ALSO EXTREMELY LACKING IN REALISM. WE CAN'T ALWAYS BLAME THE AI VIDEO FOR NOT PERFECTING THE HINTS, LET ALONE LOOKING AT THE LANGUAGE OF THE LENS。
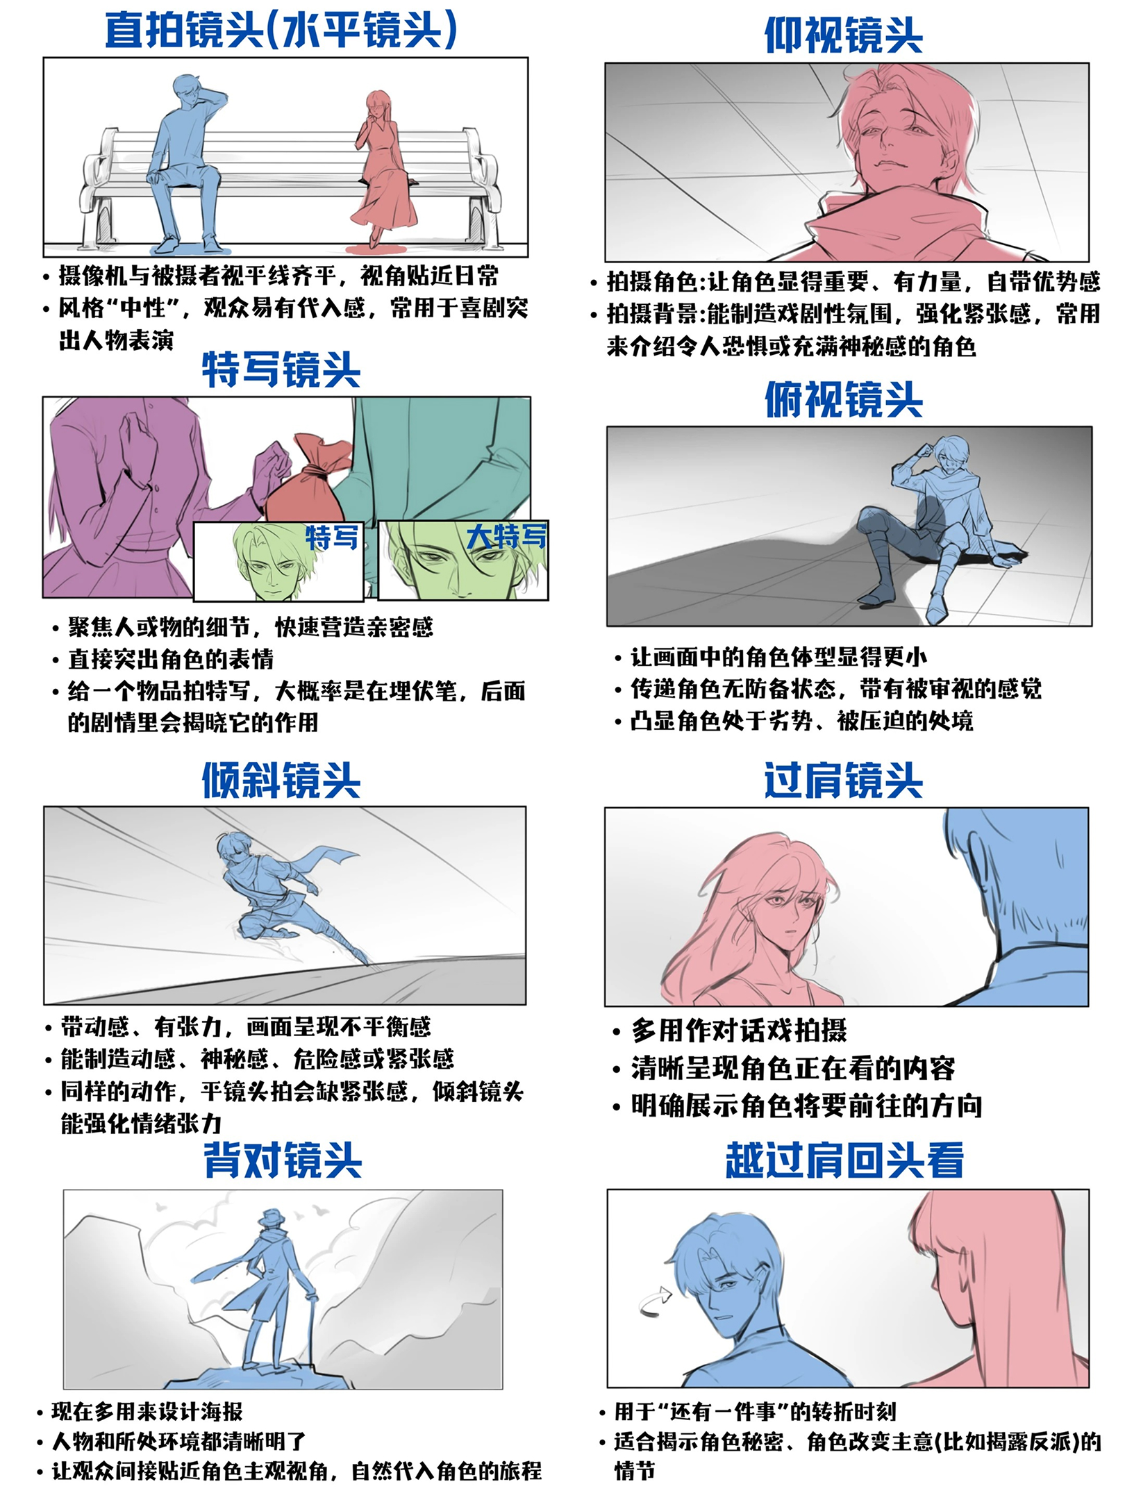
Camera reference (source from network)
Correct: Dismantling the action phase with a spectroscope and a spectroscope
A truly high-level, commercially valuable approach: having a director's mind to break complex actions into multiple lenses with a very visual impact。
A LOT OF THE SHORT, MUCH OF THE A.I. FILM, WHICH APPEARS TO BE VERY POWERFUL, IS NOT PRODUCED IN ONE INSTANCE, BUT IN MULTIPLE STAGES OF THE RELAY:
Film-class aesthetic scenario: a farewell to the summer station
Phase one (detailed – emotional mating): First, the image tools are used to generate high-level bottom maps, and only to shake before action。
Face close. The woman on the left side has a red eye, a hairy breeze, and an old ticket in her hand
Phase 2 (median scenario – action outbreak): Switch the scenery, speed up the rhythm。
Middle view, follow the shot. The hostess suddenly let go of her hand and let the tickets float and turn towards the man in the light。
Tips:
0s-2s: close-up @image_1 with the old ticket。
2s-5s: the hostess suddenly completely released her right hand and left the old ticket on the platform floor. camera tracking tickets to ground
5s-8s, she hurried, running fast towards the male master in the distant light, and her skirt was soared in the strong wind, and when the previously defunct man's clippings in the background heard voices, she turned, as @image_2。
Phase 3 (overview – climax set): Slow move up, pull up。
Panorama, raise slow. The two men were in the middle of the station, and an old train was whistling from the side, and her skirt was raised。
Tips:
0s-3s: girls come from the top right side to embrace boys
3s-6s: after hugging, the tram passed at super fast, causing the camera to shake. she's got her skirt and hair up
Core pit escape guide (most important): When we create multiple lenses at multiple stages of the relay, never be compelled to. The images and videos that are now generated, the background is usually the same, and all you need to do is make sure in the hints that “a uniform description of the environment” (e.g., always writing “the dim tavern”) is the exact same texture of each video. In the dynamic transition, the audience ' s visual focus is entirely on the person ' s actions and mirror tension, and minor background changes are automatically ignored by the brain。
Summarize
CONTROLLING MULTI-ROLE MOVEMENTS IS ESSENTIALLY A TEST OF HOW YOU MANAGE AI:
BREAKING TIME/SPACE: USE STRUCTURED LANGUAGE TO AVOID THE LOSS OF ACTION AS A RESULT OF THE MISCALCULATION OF AI。
Glossary Editor: Disappear the old version, lock and modify the satisfactory role with a single sentence。
Split complex actions: reject the long shot list and use a spectroscope to break the surveillance eye-show。
IN FACT, IT'S NOT BECAUSE TOOLS AREN'T WORKING, BUT BECAUSE WE'RE IN A HURRY. LEARN SLOWLY, AND UNDERSTAND THE LOGIC OF THESE AUDIO-VISUAL LANGUAGES AND THE BOTTOM OF MACHINES, SO THAT YOU CAN REALLY RAISE YOURSELF AND TURN AI INTO THE PRODUCTIVITY OF YOUR HANDS。