


IN THE PROCESS OF CREATING AI, WE OFTEN ENCOUNTER A PAIN:
WHY IS IT THAT THE A.I. CREATED BY OTHERS IS AS IF THEY HAD A BREATH, AS IF THEY WERE BIG PICTURES, AND THAT WE HAVE CREATED OURSELVES, ALWAYS WITH AN UNNAMED “A GLANCE”
This “false” is sometimes expressed in a gruelling sense of face like a thick, fat coat of oil, in some cases in an empty eye and in a perfect but rigid expression. This phenomenon is referred to in visual psychology as the groaning of the edges of the “weary valley effect” — it is like a human being but lacks the soul of life。
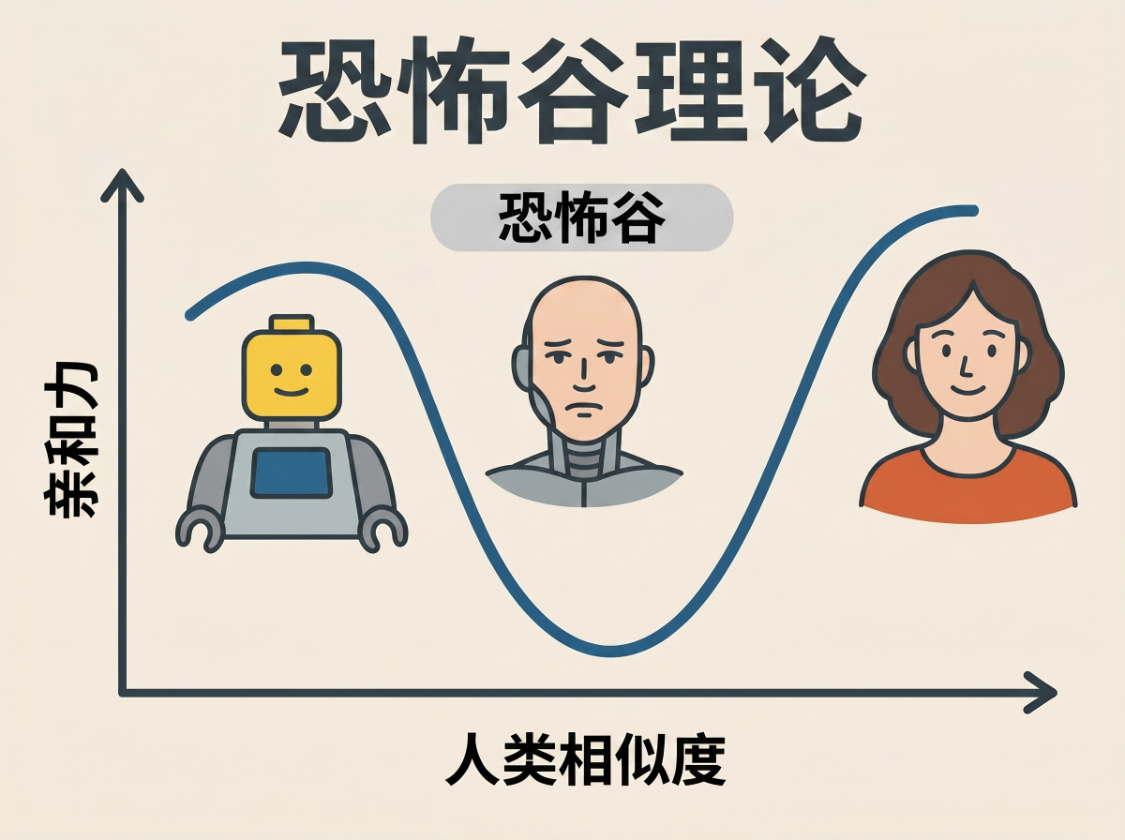
IN FACT, THE AI ROLE IS TOO RIGID, OFTEN NOT BECAUSE YOUR BOTTOM MODEL IS NOT STRONG ENOUGH, BUT BECAUSE, IN THE CONSTRUCTION OF THE HINTS, THE CORNERSTONES OF BUILDING “REAL SENSE” ARE IGNORED. TODAY WE WILL DISMANTLE THREE CORE APPROACHES THAT HAVE WORKED WELL. IF YOU MASTER THEM, YOU CAN QUICKLY DISINTEGRATE YOUR AI ROLE AND HAVE A REAL “LIVING SENSE”。
First move: Focus on detail, with micro-expressions and submersible actions
THE UNDERLYING REASON FOR THE ROLE OF AI IS NOT THAT MODELS ARE NOT WORKING, BUT THAT YOU IGNORE THE BIOLOGICAL DETAILS OF WHAT MAKES A PERSON HUMAN. MANY CREATORS ONLY WRITE “A MAN IS THINKING” WHEN THEY WRITE A HINT, AND THE RESULT IS THAT AI OFTEN PRODUCES A PICTURE OF A EMPTINESS OF EYES, AS IF IT WERE A WOODEN MAN。
The key to describing the person's expression as natural and emotional is micro-expressions and body language. Let's just take this picture of what you've created, which is called a movie pole, and see how the real "living sense" is made out of detail:
Core detail 1: To enrich the mind - describe the "flow" of emotions and "toggle"
existingAI VideoThe tools are already very powerful. If you're going to create a video now, even if the hints are simple when the picture is right, the skin sense and the light of the image are often real, and you've longed to say goodbye to the greasy “plastic man”。
THEN WHY DO WE MAKE THIS VIDEO, AND IT STILL LOOKS LIKE IT DOESN'T TASTE LIKE "AI"
Because it's fake now, it's no longer a fur, it's a state。
In order for you to understand, we're looking directly at a set of comparative cases of men in retro suits sitting on the couch reading letters。
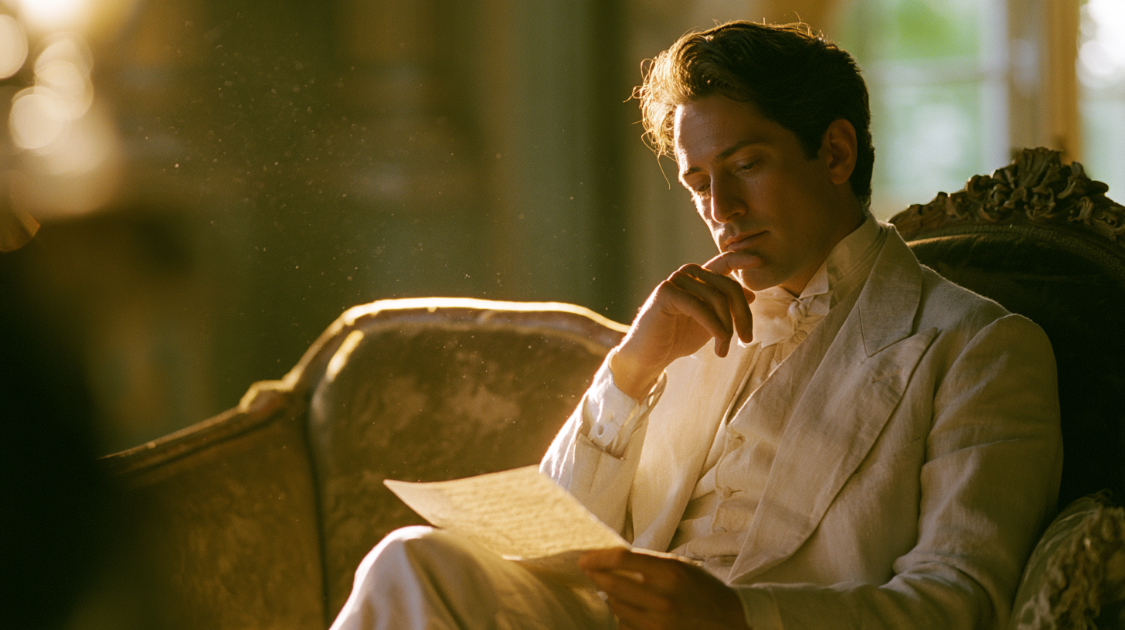
image produced by midjourney v. 8.1 with the following introductory words:
In the video series of the migration system (2007) with the mother soft funus.
Inverse case: refined but empty “tutu material”
A lot of rookies who want to act like a person thinks, enter a hint like this:
"A man in a linen suit sits on an old couch, reading letters, thinking, movie lights."
AI'S VERY GOOD. IT'S REALLY GOOD. BUT YOU TAKE A GOOD LOOK AT THE CHARACTER -- HE'S PERFECT, HE'S STANDARD, BUT HE'S NOT EMOTIONAL。
Although he had his chin in his hand, his face lacked exercise. In a few seconds of video, he had no emotional progression, no internal intensities arising from reading the contents of the letter, and his hand with his chin was as rigid as a slab. It's called "a skin bag, no soul."。
DON'T GIVE AI A STATIC EXPRESSION COMMAND. WHEN HUMAN BEINGS THINK IN DEPTH, THEIR EMOTIONS ARE COMPLEX AND FLUID。
See how we can deepen men's deities in this picture:
Commencement status: Optimal focus on letters, microbrows (with focus on text)。
State of transition: Read a paragraph, the eye creates a tiny beat (rereading or skipping), the eye blinks slightly, and the eyelashes are brightened by the sun。
The sane climax: After reading the last line, the sight rises slowly, looking out of the lens (probably nostalgia, anxiety, decision-making or emotional explosion), and the more complex story in the eyes. The lips were then reduced from light to small, and then closed because of depression。
Video Dynamic Indices Suggested:
When the video is generated, do not give static results, but describe the emotional process:
Thoughtful gaze shipping from reading text to look nostalgic off-camera, eyes blink softly (with illaginalated lashes), subtle eyebrow firrowning and relaxing, lips presclosed with deep repression, then brightly part showing hesitancy. I'm not sure
Introduction of “subtext” in body language
The original hand-to-bar movement was real, but slightly static. In order for action to have a higher sense of soul and physical authenticity, we need to replace static “tips” with dynamic “marrows”. This is an unconscious physical reaction of human beings when they are extremely focused, anxious or hesitant。
We've worked hard on the Moose:
Classic molar chin: Describes the slow, rhythmically smooth and molar fingers (e.g., an index finger and a thumb) on the chin or jaw line. It's an unconscious thought move。
A more nuanced muscular lips: the fingertips consciously squirm at the edge of the lower lip or the mouth. This move is not only extremely film-sensitive, but it also provides an excellent illustration of the complex physical interaction of finger-pointing material and facial skin。
Physico-effects combination: As a result of the mosaics of the fingers, the skin of the face will move finely, and the sleeves of the linen suit produce more complex dynamic wrinkles。
Video Dynamic Indices suggests that instead of just " sitting " , add action and weight changes:
Dynamic hands posture, spirits slow and rhythmicing the Chin and lower jawline, fingertips gently rubbing the lower Lip line. Motion begins skin movement on his face and acceptable dynamics hands in hislines. The movement produces skin movements in the face and additional dynamic wrinkles in the linen cuffs due to changes in position. I'm not sure
Second move: Breaking the swing and using the "environmental confrontation" to keep the movement alive
THE PRESENT AI GENERATION TECHNOLOGY, WHETHER IT'S GRAPHIC OR VIDEO, IS MOST EASILY EXPOSED TO THE "AI TASTE" IN THE PERSON'S ACTIONS AND SHAPE。
In order to speak about this core technique, we will go in two steps: first, to teach you how to establish real life in static images, and then to teach you how to give people a rational logic in dynamic video。
Phase one (photogram): farewell to the "Fake" show, creating a "clip" in static images
WHEN USING AI TO GENERATE IMAGES OF STATIC PEOPLE, THE SIMPLEST MISTAKE A ROOKIE CAN MAKE IS TO PUT A PERSON IN A “VACUUM TECTONIC” STATE。
IF YOU ONLY SAY "A WOMAN WALKS IN THE GARDEN" IN A HINT, AI DOES PRODUCE A WOMAN. BUT YOU'LL FIND THAT HER BODY'S CENTRE OF GRAVITY IS ALWAYS IN THE MIDDLE, WITH THE RIGHT AND RIGHT HAND SYMMETRICAL SWINGS, AND HER CLOTHES ARE STILL ON. THIS MAKES THE PERSON LOOK LIKE A "T-TEAM MODEL" WITH A DENT IN FRONT OF THE CAMERA, WITH NO REAL LIFE。
Demolition methods: introduction of “environmental confrontation” and “physical inertia”
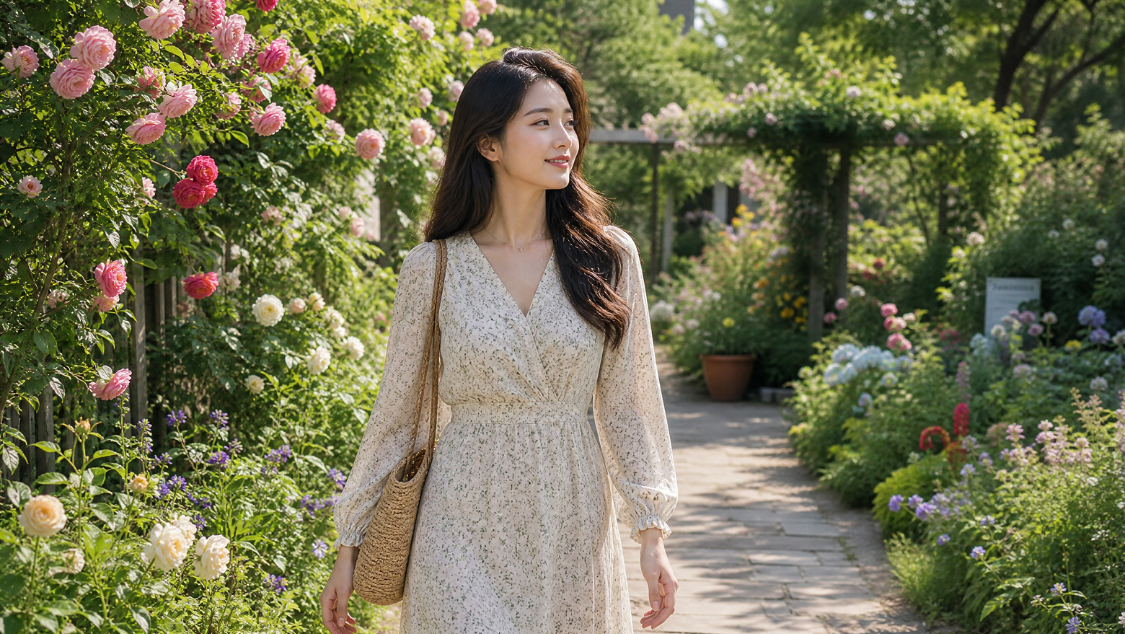
If you want the person in the picture to live, you need to let her have a real physical collision with the surrounding environment. Let's look at this perfect case chart。
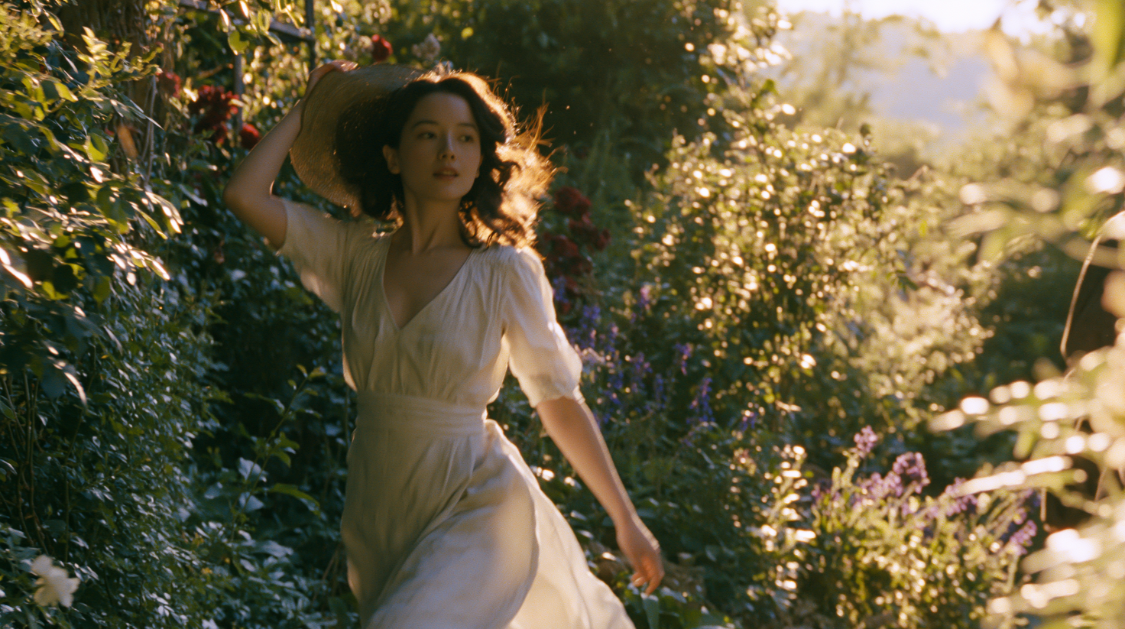
The prompt words are as follows:
In the visual moving service of the movie industry (2007). A beautiful Chinese woman, in a light-skinned summer dress in the 1930s, wandered in a bright, suntan garden. The visual light style of the film Yom Kippur (2007) is used. Swimming motion, snapping when the steps are halfway through. The breeze over. Her arms were naturally raised to hold the suncap, the head was slightly tilted towards the wind, and her hair was light and light. The dynamical pose of the unmade, snapping, forcing the Asian identity. Warm twilight light, glowing light, flashing reflections of soft and emptiness, rich film-grade colours, 35 mm film particle senses, full of stories. I'm not sure
This image is as if it was a frame taken from the film because it made these two things the best:
Introduction of environmental confrontation:
THE REAL WORLD HAS WIND AND RESISTANCE. WE HAVE NOT LET THE CHARACTERS WALK IN THEIR HEAD, BUT WE HAVE INTRODUCED A “WIND”. IN ORDER TO PREVENT THE HAT FROM BEING BLOWN AWAY, THE PERSON CONSCIOUSLY RAISED A HAND TO HOLD THE STRAW HAT, WHILE THE WIND WAS SLIGHTLY TILTED IN THE HEAD. THE IRREGULAR PHYSICAL MOVEMENT OF THE "COUNTER WIND" BREAKS THE SENSE OF SYMMETRIC RIGIDITY CREATED BY AI HABITS。
Manufacture of physical inertia:
REAL ACTION IS CONSISTENT AND HEAVY. IN OUR REMINDER, WE ASK AI TO CAPTURE “ONE HALF OF THE MOMENT OF STEP”. LOOK AT HER SKIRT, IT'S NOT SO SOFT AS TO FALL TO HER LEG, BUT RATHER, IT'S MOVING FORWARD, WITH AN EXTREMELY NATURAL RADIANS COMING BACK。
In static pictures, this unintended little action and physical weight feeling was added, and the twitching completely disappeared。
Phase II (Video): farewell to "blind walking" and giving "inherent logic" to coherent action
When we're perfect in static images, the next step is to generate video. But at this time, new problems have arisen。
NOW THE BIG AI VIDEO MODEL (E.G., DREAM, COVEN, ETC.) IS ALREADY VERY POWERFUL, AND EVEN IF YOU WRITE A SIMPLE INSTRUCTION, THE CHARACTERS WILL HARDLY GET TO THE "ROBOTS" OF THE PAST. IT'S VERY FLUID, AND THE SKIRTS FLOAT。
If it's not rigid, then why does the video look fake or fake? Because it's a fake now, it's a fake without logic。
COMMON AI VIDEO OVERTURNS THE SCENE: YOU'LL FIND THAT THE GIRL IN THE VIDEO, WHILE WALKING, IS WALKING, AND THE HAND WITH THE HAT SUDDENLY DROPS OFF WITHOUT A REASON, OR THE EYES START TO LOOK TO THE LEFT WITHOUT PURPOSE. SHE'S BEAUTIFUL AND SMOOTH, BUT SHE'S LIKE AN "UNIQUE LENS" THAT DOESN'T HAVE A STORY TO TELL. SHE DIDN'T KNOW WHY SHE HAD THE HAT OR WHERE THE WIND CAME FROM。
Demolition methods: use of “environmental factors” to lock the motive for action
DON'T LET THE CHARACTER "BLINDLY WALK" IN THE AI VIDEO. SINCE WE USE "WIND" IN PICTURES TO CREATE A SENSE OF CAPTURE, WE USE "WIND" AS A DIRECTOR IN VIDEOS, FORCING PEOPLE TO REACT IN A COHERENT SUBCONSCIOUS。
LET'S NOT JUST LET AI DO THE "WALKING" MACRO MOVE, BUT LET'S SPELL IT OUT WITH A HINT:
The next time the video is generated, try to write this:
“As the steps are halfway through, a breeze blows through (the environmental cause), she consciously lifts her arms to hold the suncap to protect against the wind (the result of the movement), leans forward with a small weight, a thin skirt follows the wind and moves forward with natural motion (the continuation of the physical state of the conversation).”
WHEN YOU ADD THIS TO THE SET, THE ROLE IN THE VIDEO IS NO LONGER THE BRAINLESS NPC OF RANDOM DISTRIBUTION. HER HAND WAS NO LONGER A MEANINGLESS SETUP, BUT A “HAT”; THERE WAS A REASONABLE SUPPORT FOR HER BODY。
One sentence summing up the second move:
Don't let your role move in a vacuum without resistance, whether it's a drawing or a video. A little wind, a little resistance, and a little physical reaction to the environment. Once you have physical inertia and common sense motivations, your work really has a movie-level sense of reality。
Third move: fine light processing, with "local light source" and "cooling heat" rejecting greasy
WHY IS IT THAT THE A.I.'S PEOPLE, AND THE FIVE OFFICERS ARE SO SOPHISTICATED, ARE ALWAYS USING A "PLASTIC SENSE"? THE REASON IS USUALLY IN THE LIGHT. AI IMPLICITLY LIKES TO LIGHT UP THE WHOLE FACE WITH A "BIG FLAT" LIGHT, AND WITHOUT A SHADOW, THE FACE BECOMES A FLAT PICTURE。
In order to remove this false greasyness, we can adjust it in two steps: first, to process the photoformation in the picture, and then to solve the luminous movement in the video。
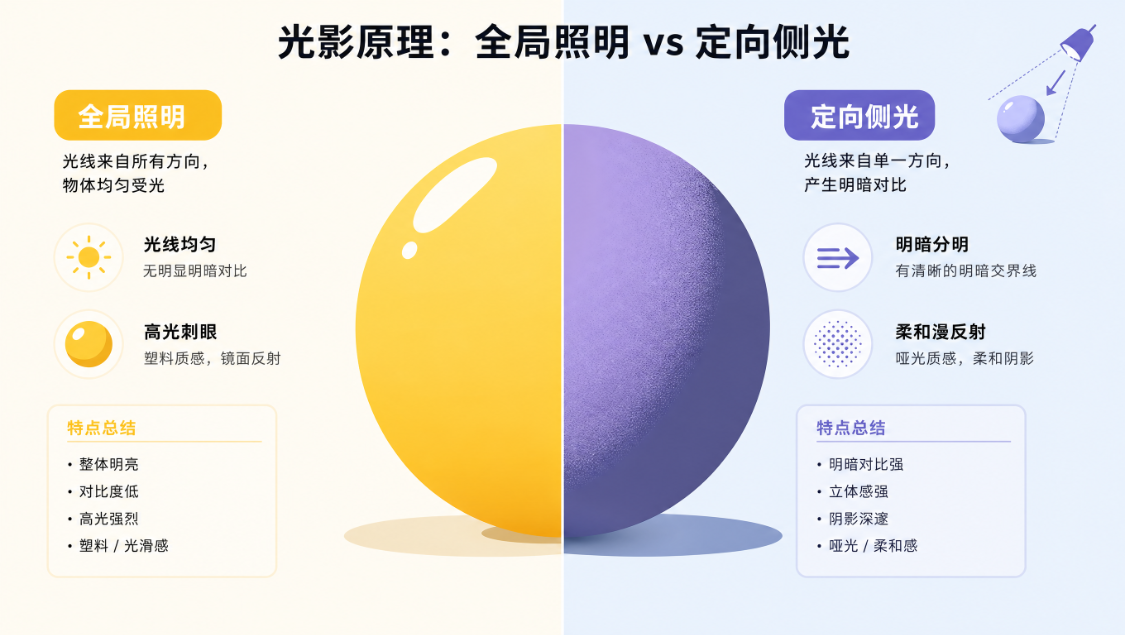
Phase one (photogram): local light and tectonic shape
Do not let the light shine in every corner of the picture. We understand the concept by a strong comparison of the two maps。
Inverse case: “plastic senses” in broad light
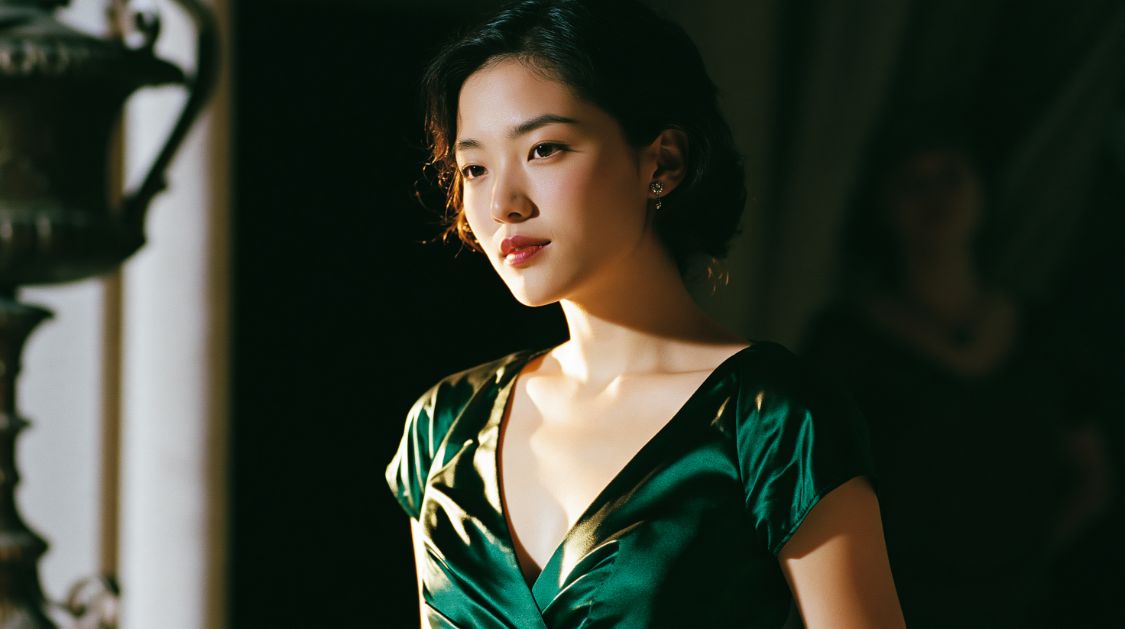
Look at this negative case. While the picture is clear and beautiful, the absence of a clear-cut comparison and the death toll of light on the forehead and nostrils creates an extremely cheap sense of greasy plastic. Chinese women's fine-looking bones have been turned into a flat without any rises or swings in the light。
Positive example: engraving a 3D feeling with shadow
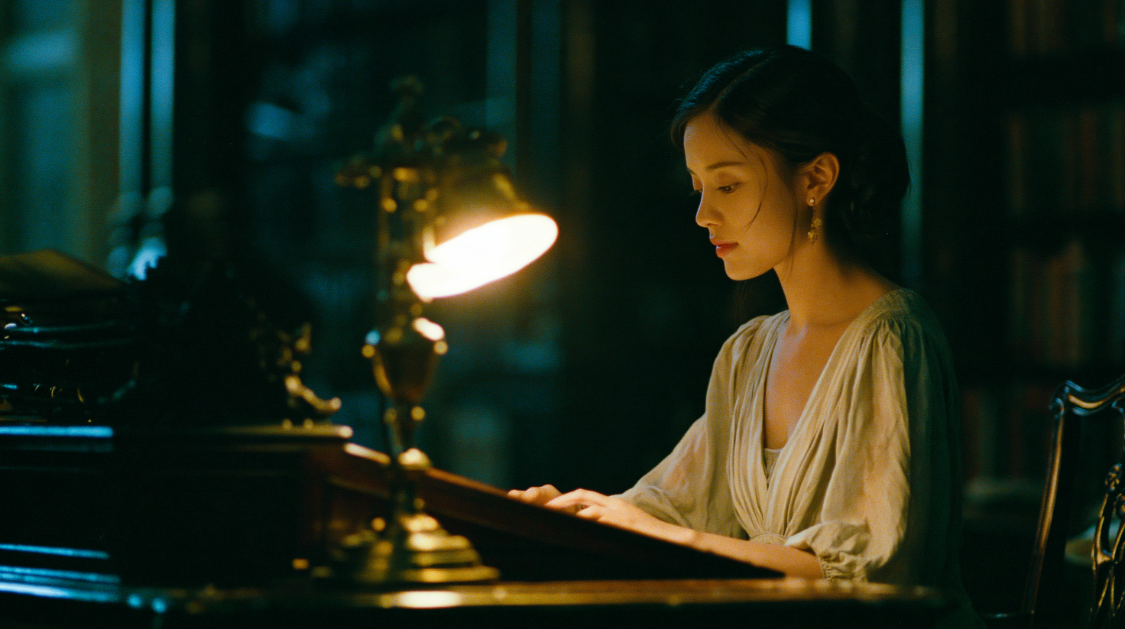
Phrasing (Prompt):
In the video series of the movie series. A Chinese woman with a mind-blowing mind, wearing an antique wood table at the Dark Library of the 1930s dress of light submersible mahjong. Use the visual style of the film Yom Kippur (2007). The practical source of light from an antique brass lamp, which is warm and luminous, lights her face and hand, in contrast to the cool and dark green shadow of her grandmother in the surrounding room. Mute skin texture. The luminous luminous light of the sky around the lamp, a 35mm film particle sense, is full of stories. I'm not sure
HOWEVER, GOOD LIGHT TREATMENT SHOULD BE THIS WAY. THIS GIRL'S PICTURE UNDER THIS LAMP LOOKS VERY NATURAL AND TASTELESS
Learn to leave white and "hidden light" (local light source):
Instead of using global lighting, it uses only a retrograde lamp as its main light source. It only shines on the side of the girl's face and hands, leaving the background in the dark shadow. With a dark, dramatic comparison, nature shows the true rise and fall of the bones of the face。
Warm colour comparison:
Lights have temperatures and layers. The light is warm yellow on the face (sweet light), while the background library displays dark blue and green light (cold light). This “pre-heating cold” colour confrontation is a good way of opening up space and making the scene more real。
3. Defining skin material (mute skin):
in order to be greasy from the source, mandatory instructions must be added to the hint: matte skin texture. warming light on a delicate, dumb skin produces a soft, lukewarm reflection, and that is never the kind of glacial plastic。
Phase 2 (Video article): Life and Death in the Bottom Chart, Video Tictionary Society "Deductive"
We spent so much of our energy in the picture phase to teach the shadows in order to “slut”。
Now, the big graphic video model is very smart, and it's perfect for all the quality of the first picture you uploaded. If you only need a character to do some small-scale moves, don't make video tips too complicated。
The new guy's missing: drawing snakes to add an overstate
With a perfect bottom map, many newcomers, when they produce videos, still copy all of the "cold-hot contrast", "dum-skin" and "retro-plaster" in their graphics。
It's not helping。
Optimistic operation: only small physical actions
Now that the picture is real enough, and the environment and the light are fixed, there's only one thing you need to do in the video message: tell it where to move。
The video is very brief and indicative (based on the background map of the girl in the lamp):
"Subtle breaking, gentle keeping moving, keeping original lighting."
(Slight breath, gentle typing, keeping the light. I'm not sure
Look, it's that short。
AS LONG AS THE BOTTOM MAP HAS A STRONG SENSE OF TEXTURE, AI WILL FOLLOW ITS ORIGINAL PHYSICAL LOGIC. THE GIRL'S CHEST WILL RISE AND FALL, HER FINGERS WILL KNOCK ON THE KEYBOARD, AND THE SHADOW OF A LAMP WILL BE ATTACHED TO HER DUMB SKIN。
One sentence summarizes this:
THE ENERGY OF 90% IS FOCUSED ON GRINDING THE LIGHT AND THE QUALITY OF THE “FLOOR MAP”. AS LONG AS THE PICTURE IS HUMAN ENOUGH TO PRODUCE A SMALL-SCALE DYNAMIC VIDEO, LEARN TO GIVE THE HINT "DECLINING" AND AI WILL NATURALLY GIVE YOU BACK A VERY REAL FILM SHOT。
SUMMARY: THE THREE CORE APPROACHES THAT GIVE AI A “LIVING SENSE”
The performance is intended to “subtext”: break the scene with microthermal and subconscious action
Don't write: "Thinking," "worried," "Face-in."。
To write: The movement of eyes (e.g., "the sight is rising slowly"), the slight movement of facial muscles (e.g., "the twilight and relaxing eyebrow") and the subconscious movements of physical inertia (e.g., "the rhythm of the finger")。
Heart: Emotions are mobile, people are put in their inner play, the vibes disappear。
Actions are intended to be “confrontational”: building physical logic with environmental resistance
Don't write: "Go for a walk in the garden," "walk."。
To write: Environmental factors (e.g., “blowing by a breeze”), actions to counter the environment (e.g., “underconscious to hold the hat against the wind”) and snapping instantaneously (e.g., “half-step, little body forwards”)。
Core: Don't let the role go in a vacuum, add reasonable physical logic and motivation to the action, so the video doesn't look like an empty lens。
The light shadow learns to hide: partially emptied and carved, and the video is decisively reduced
Don't write: "The brightness is even" and "the perfect light is unblemished."。
To write: Local light sources (e.g., "refutable lamps"), cool contrasts (e.g., "cold-faced background") and mandatory locking of materials (e.g., "mute skin")。
CORE: TO GET GREASY, YOU HAVE TO USE SHADOWS TO SHAPE YOUR SENSE OF 3D. ONCE YOU'RE IN THE PHOTO PHASE, YOU'RE GOING TO BE ABLE TO "CRACK" THE LIGHT AND THE SENSE OF QUALITY, AND YOU'RE GOING TO BE ABLE TO GENERATE THE VIDEO WITH A DECISIVE "CUT OFF" — WITH ONLY THE SLIGHTEST ACTION (E.G., "SLIGHT BREATH, TYPING" ), AND AI WILL NATURALLY INHERIT THE PERFECT LIGHT。