


AI VideoIt doesn't look real enough, it doesn't have to be a misword or a model that doesn't match the camera mission. The same frame, the same hint, is inserted into different models, and the results may be completely different. Some models keep people's skin, product material and image colours well, but they are not suitable for large-scale action; others are better at running, dancing, complex mirrors and multiple reference material, but the quality of the details generated is not necessarily what the project needs most。
The selection of Violin O3 or Seedance 2.0 focuses on three aspects: how much action the lens requires, whether it relies on multi-modular reference, and whether the project places more emphasis on action completion or final quality. Full scripts and detailed spectroscopes can be delivered directly to Seedance 2.0, and high-quality frames and light motion lenses can more easily exploit the artistic advantage of Violin O3。
The course will be based on actual production, detailing the strengths, slabs, applicable lenses and hints of the two models。
I. Three dimensions to determine model selection
Full scripts and detailed spectroscopes can be delivered directly to Seedance 2.0. When the scenery, the movement of the person, the motion of the lens and the time sequence of each shot are sufficiently clear, the model is able to complete the movement and the sequence of the lens by the lens。
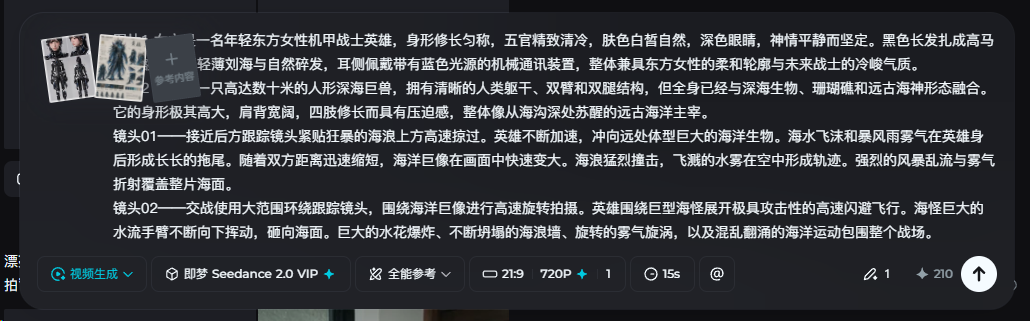
For example, with the uploading of assets and detailed spectrophs, a high-quality video is directly available
Violin O3 and Seedance 2.0 can generate high-quality AI videos. In some shots, the O3 effects will be more complete
In other shots, Seedance 2.0 clearly has a better understanding of action and camera movement. The selection does not require a single model for the entire piece, but rather a judgement of the most important delivery target for each shot。
A truly effective choice is:
– Need for co-production of multiple pictures, reference videos, audio or different types of material, with priority given to Seedance 2.0
– There is only one frame, but the person needs to run, dance, fight, quickly turn around or complete a large body move, priority is given to Seedance 2.0
– The lens consists of visible propulsion, rounding, following, crossing or multiple scene changes, priority being given to Seedance 2.0
– THE LENS IS LIMITED TO SPEECH, BACK-TO-BACK, BLINKING, A SLIGHT TURN, SMALL EXPRESSION AND LIMITED PHYSICAL EXERCISE, GIVING PRIORITY TO O3
– THE MOST IMPORTANT IS THE IMAGE QUALITY, COLOUR, PRODUCT DETAILS AND INITIAL REDUCTION, PRIORITY O3
– There is a need for high-quality 4K lenses to be generated under the current budget, with emphasis on Violin O3 (lower than security 2.0 4k), at a price based on the platform page at the time of use。
One sentence summary:
Complex action and multi-mode selection Seedance 2.0; light motion and extreme paint quality selection OC3。
Even if all the spectroscopes have been completed, they can continue to be distributed according to this standard: a high-quality frame requires only a minor exercise, to be handed over to Clin O3; and a detailed spectroscope contains a large performance, complex mirrors or multi-scenes change, to be handed over to Seedance 2.0。
Note: Clin O3 in the text contains 3.0 Omni (which can be used to generate video, not only for initial frames), 3.0 for initial frames or tail frames only)
Core differences between the two models
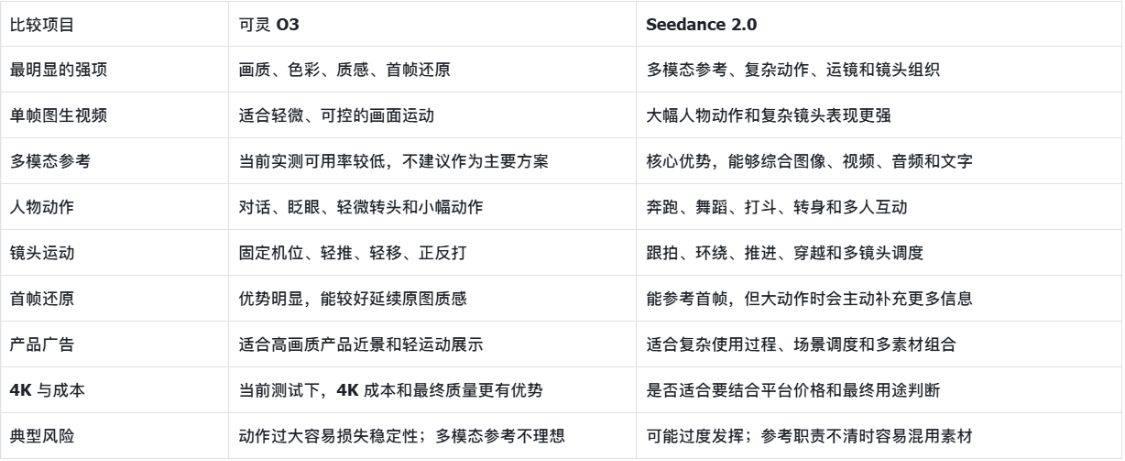
This table is more useful than "which model is stronger." Cream O3 is like a camera that's good at taking fine pictures, and it's loyal to the head frame, and it keeps the light, colour and material of the original map perfectly. Seedance 2.0, more like an action director and a spectroscopy director, is good at understanding what people are going to do, how the cameras are going to move, and how different materials should work together to create a picture。
III. Absolute advantages of Feedance 2.0: multi-modular reference
Multiple mosaics mean that models can understand different types of material at the same time, such as person charts, scene maps, product charts, reference videos, sound and text. Seedance 2.0 ' s Full Reference is not an additional function, but the core competencies that it is most worthwhile to use。
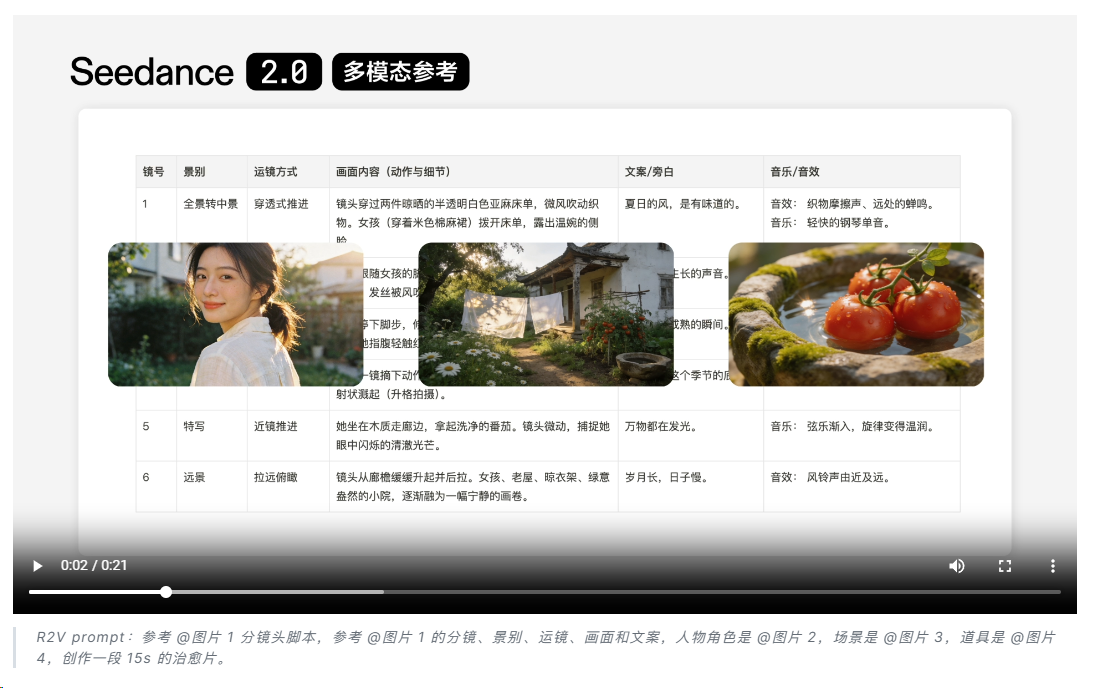
YOU CAN HAVE THE CHARACTER CHART TAKE RESPONSIBILITY FOR CHARACTER IDENTITY, THE SCENE MAP TAKE CHARGE OF SPACE AND LIGHT, THE PRODUCT CHART TAKES CHARGE OF THE LOOK, THE ACTION VIDEO TAKES CHARGE OF THE PERSON'S MOTION, THE OTHER VIDEO TAKES CHARGE OF THE LENS, AND THEN YOU CAN USE A HINT ABOUT WHAT YOU WANT. THIS METHOD OF WORK IS APPROPRIATE FOR SHORT BRANDS WITH ONLY APPROXIMATE DIRECTION AND ZERO BULK MATERIAL, AS WELL AS FOR MULTI-PHOTOGRAM SHORTS, MV, ACTION SCENES AND COMPLEX ADVERTISING, WHICH ALREADY HAVE DETAILED SPECTROSCOPY。
According to the current reality, the multi-modular reference for Vitruistic O3 is almost impossible to create a stable workflow. It may not be able to make an accurate distinction between the effects of each material, or may not combine actions, characters and scenes into expected results. Therefore, when the project clearly relies on a multi-modular reference, it is not recommended to impose the use of Vitruistic O3 in the pursuit of graphics, and to directly select Seedance 2.0 is more efficient。
Multistate material must be clearly divided
When you use Seedance 2.0, the most important thing is not to upload the material, but to make it all clear. Personal maps are responsible for identity, including five officials, hair, clothing and shape; scene maps are responsible for space structure, light and environmental materials; product maps are responsible for shape, packaging and branding information; action videos are responsible for the movement of people; and mirror videos are responsible only for how the camera moves. The more monolithic the material, the easier the model is to call。
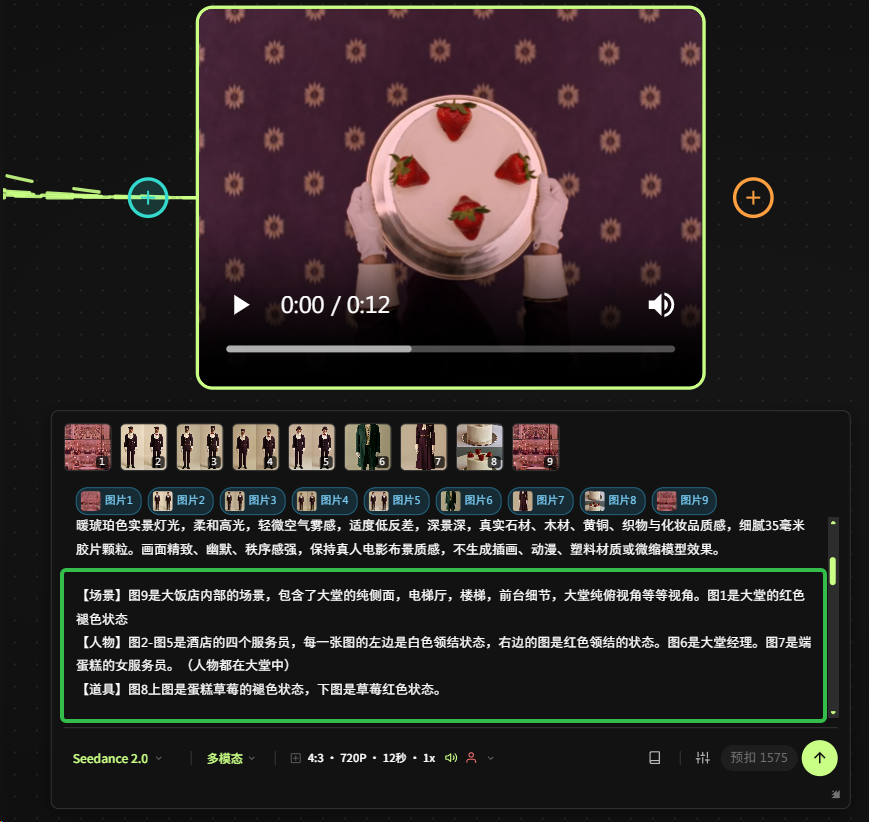
Identify and identify assets
If only "Reference to the above pictures and videos" is written, the model needs to speculate on the role of each material. It may lead to the appearance of the person in the action video in a film, or it may use the scene picture as a model that must be replicated, or even mix the clothing and products in the different materials. The description of the reference should therefore be accompanied by an indication of what was not. For example, action videos provide only the rhythm of action and should exclude the identity, clothing and background of the person in them。
a detailed text of the text is available in the textCue word tutoriali don't know. https://www.1ai.net/58243.html
IV. Second advantage of Feedance 2.0: A single frame can also make a big move
Many people think that only a multi-modular mission needs a Seedance 2.0. Indeed, even if there is only one frame, as long as it involves large-scale action in the picture, it deserves priority。
Large-scale movements include running, jumping, fast turning, dancing, fighting, bending over, multi-person interactions, and moving people from close to far. Models need to be constantly completed with parts of the body, changes in clothing and spatial relationships that are not shown in the frame. Seedance 2.0 has a better understanding and continuous generation of this type of action, and the movement of the person is usually more in range and closer to the description of the hint。
When describing such footage, actions should be written in the order in which they actually occurred, rather than just a few verbs. The turn is followed by a start, followed by a detour of the barrier and, finally, by a stop; each step corresponds to a new physical focus and space relations. The camera route is also separated from the movement of the person, so that the model knows where the camera starts, how it follows, when it stops and where it ends。
Massive action does not mean that the hint must be long. What is really important is that there is a causal link between the actions, that there is reasonable contact between the person and the environment, and that the lens movement has a clear starting and end point. The abstract “very filmy” cannot replace these specific messages。
V. THE ABSOLUTE ADVANTAGE OF THE CLIN O3: RESTORATION OF THE PAINT AND THE INITIAL FRAME
THE O3S ARE REALLY POWERFUL PLACES, AND THEY'RE A TOUCH OF THE ORIGINAL AND THE FINAL PICTURE. WHEN THE TOP FIVE CHARACTERS, SKIN, CLOTHING TEXTURE, PRODUCT MATERIAL, LIGHT AND COLOUR ARE ALREADY GOOD, THE CLIN O3 CAN MORE FULLY SUSTAIN THESE VISUAL MESSAGES。
IT'S VERY IMPORTANT FOR THE ELECTRICIAN AD AND TVC. WHETHER THE PRODUCT IS PACKAGED IS DEFORMED, WHETHER THE BOTTLE BODY IS REAL, WHETHER THE PERSON'S SKIN IS PLASTIC, WHETHER THE CLOTHING IS STABLE, AND WHETHER THE IMAGE COLOUR IS HIGH WILL HAVE A DIRECT IMPACT ON THE COMMERCIAL SENSE. UNDER THE SAME CONDITIONS OF MINOR EXERCISE AND INITIALS, VIOLIN O3 TENDS TO BE MORE COMPLETE WITH REGARD TO THE CONSISTENCY OF A PERSON'S EMOTIONS AND PRODUCTS, AND LESS RIGID “FALSE PERCEPTION” OF A PERSON. WITH THE SAME BUDGET AND CURRENT PLATFORM PRICES, ITS GRAPHICS, COLOURS AND 4K COSTS HAVE A CLEAR ADVANTAGE AND ARE PARTICULARLY WELL SUITED TO TURN THE HIGH-QUALITY INITIALS ALREADY PRODUCED INTO A FINE DYNAMIC LENS。
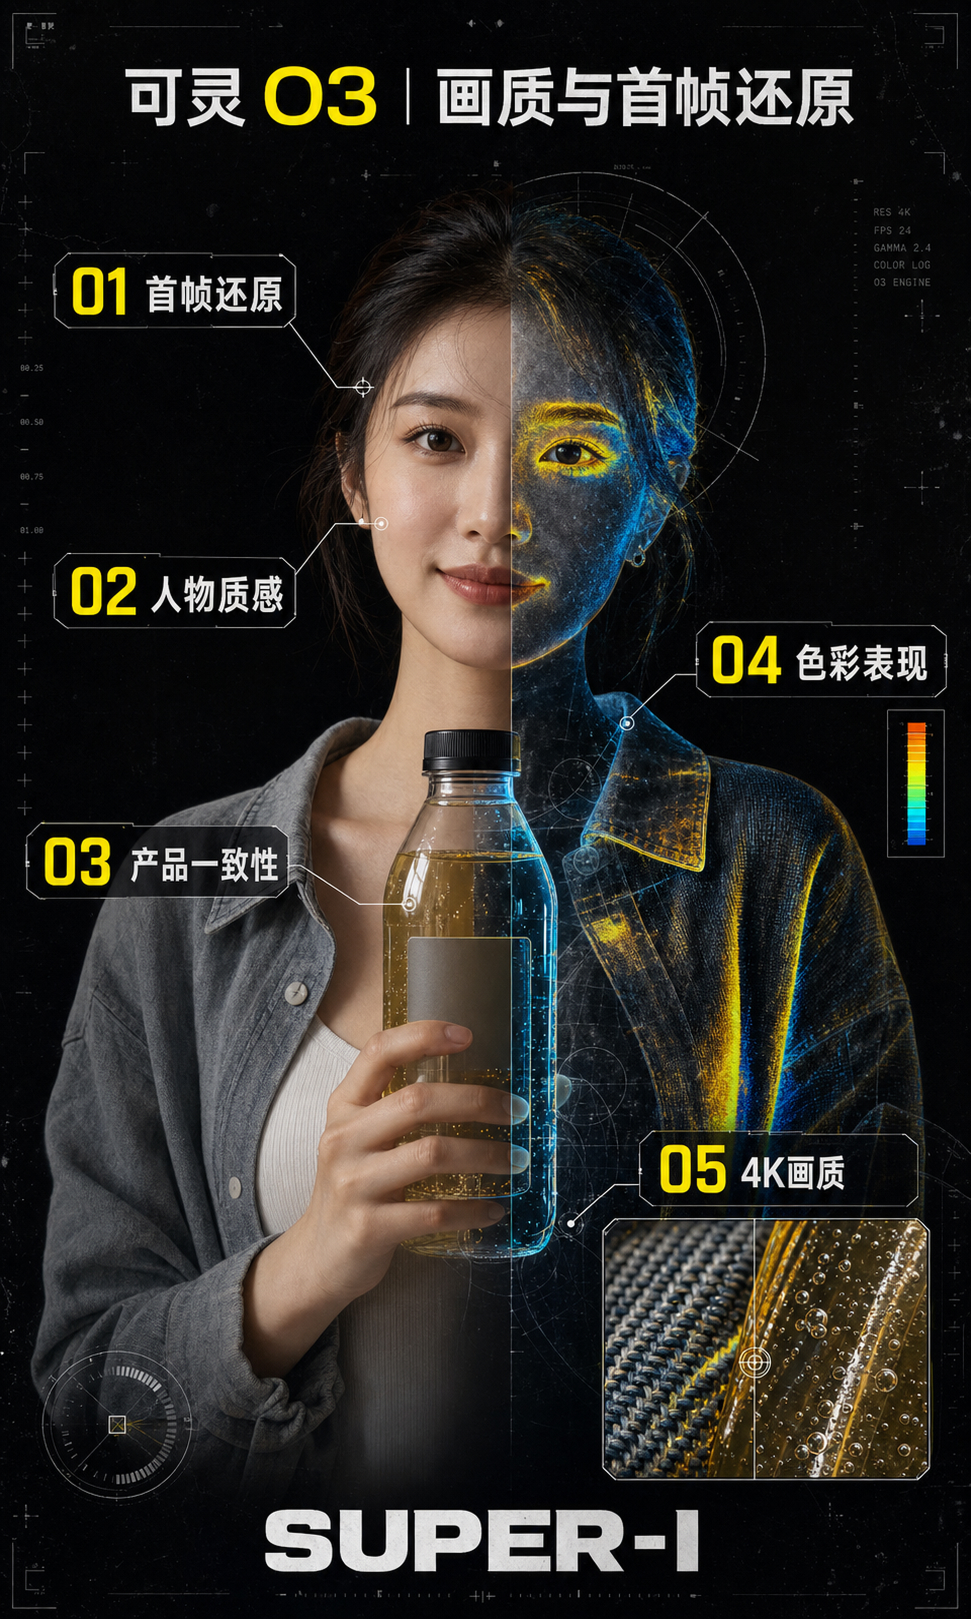
BUT THIS ADVANTAGE REQUIRES THE PREMISE THAT THE FRAME ITSELF MUST BE GOOD ENOUGH. THE MORE FAITHFUL THE O3 IS, THE EASIER THE ERROR IN THE FRAME IS TO BE PRESERVED. THE HAND OF THE PERSON, THE TEXT OF THE PRODUCT, THE LENS, THE REFLECTION AND THE VEIL ARE CHECKED BEFORE THEY ARE GENERATED。
THESE SHOTS ARE PREFERRED TO CLIN O3
(b) Positive and negative footage of person conversations
– The person blinks, breathes, slightly turns his head and looks small
- bottling, packaging, material and light display of products
– Models standing, little swinging or slow lifting
– Fixed position, slight propulsion or small-range trans-shipment
– There is a high-quality frame that wants to preserve the original to the maximum extent
– QUALITY 4K OUTPUT IS REQUIRED, WITH A DESIRE TO CONTROL THE GENERATION COST。
THE O3 WRITING FOCUS IS ON CONTROLLING CHANGE
THE PICTURE IS ALREADY IN THE FRAME, SO THERE IS NO NEED TO RECHARACTERIZE ANOTHER SET OF STRUCTURES AND ENVIRONMENTS. THE TEXTUAL DESCRIPTION OF VIOLIN O3 SHOULD FOCUS ON THREE ASPECTS: WHAT HAPPENS TO A PERSON OR PRODUCT SLIGHTLY, WHETHER THE CAMERA MOVES, AND WHAT HAS TO CONTINUE THE FRAME. THE MORE RESTRAINED THE MOVEMENT, THE EASIER THE MODEL IS TO PRESERVE FACIAL, MATERIAL, COLOUR AND DETAIL。
The character lens can tear the performance to four levels: eyes, mouth, head and shoulder. In dialogue, mouth motion is the main change, with eyes and expressions being matched and head and body stable; emotional lenses can change eyes first, then a slight look. The product lens should give priority to the protection of bottle shapes, packaging text, material reflections and brand colours, so as not to allow the product to rotate quickly in the image or be overshadowed by the Minister ' s time。
CAMERA EXERCISE ALSO REQUIRES RESTRAINT. FIXED SLOTS ARE THE MOST STABLE, SLOW-MOVING AND SMALL-SCALE SUBSIDENCE. WRAPPING, FAST-MOMENTATION AND LARGE-SCALE MAPPING CHANGES WILL FORCE THE MODEL TO SUPPLEMENT SPACE INFORMATION OUTSIDE THE INITIAL FRAME AND WILL UNDERMINE THE MOST VALUABLE INITIAL REDUCTION ADVANTAGE OF THE VIOLIN O3。
VI. WHY IS THE DIALOGUE PLAYING RIGHT AND RIGHT
The dialogue was a way of cutting back and forth between the perspectives of two people when they spoke. Each camera is usually dominated by the upper body or face of the person, with a smaller movement, with a focus on the eye, mouth, face and image。
This corresponds to the advantage of Clint O3. The first is to produce a high-quality frame for each of the two characters, and then to allow the model to finish talking, blinking, noding and minor expression, so that the role looks better. If a conversation also involves a rise, move, go around the table or interact with multiple people at the same time, then the large action segment can be handed over to Seedance 2.0, which will then be taken back to the contours of the colin。
In other words, there is no need for a single model for the same play. The vision and complex movement uses Seedance 2.0, the view, close-up and back-to-back use of Violin O3 and, lastly, the unified rhythm and colour of the clip, tends to be more stable than having a model carry all the lenses。
VII. How the complete script, the detailed spectroscopy and the asset map were delivered to Seedance 2.0
The complete script can be delivered directly to Seedance 2.0, but it is best to prepare asset maps at the same time. This is the story and emotion of the show, the spectroscopy depicts the scene, the movement and the mirror, and the asset map covers fixed persons, clothing, scenery, products and key props. The three types of information combined, the model knows what to shoot and what to look like。
The person ' s assets should provide a clear image of the face and body, the scene assets should describe the space structure and light, and the products and props assets should be fixed in shape, colour, text and material. There can be no contradiction between different assets, otherwise it will be difficult to maintain cross-scenes consistency。
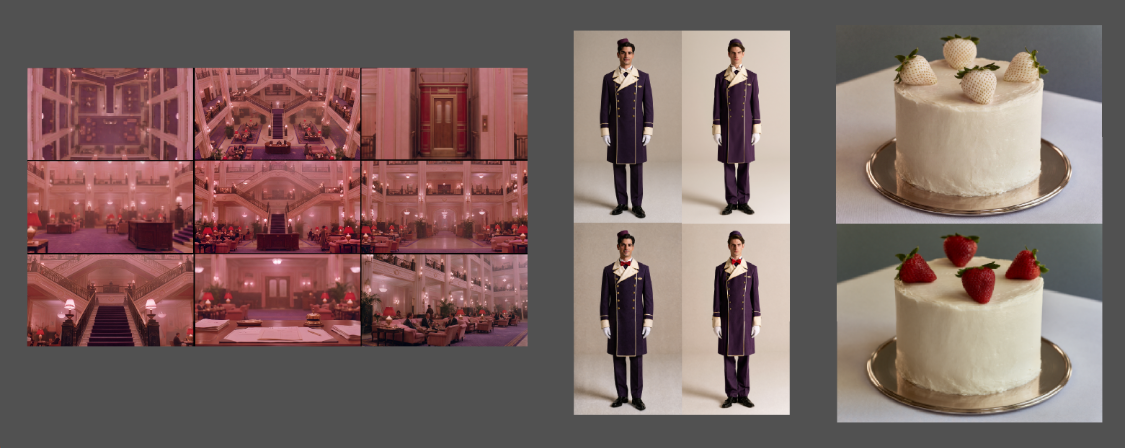
Assets chart
The spectroscope describes the profile, the movement of the person and the camera, the movement of the lens, and the continuous direction of the person, the location of the product and the light. The asset map reduces the model's public perception, so that the two combine to make better use of the motion, mirror and multimodular capabilities of Seedance 2.0。
detailed feedance 2.0 tips can be used to refer to this introduction tutorial. https://www.1ai.net/58243.html
VIII. Combining by lens is more practical work stream
IN AN ADVERTISEMENT, SHORT PLAY OR MV, THERE ARE USUALLY TWO TYPES OF DEMAND: SOME LENSES FOR COMPLEX MOVEMENTS AND CAMERA MOVEMENTS, OTHERS FOR THE FACE OF THE PERSON, THE MATERIAL OF THE PRODUCT AND THE COMMERCIAL. THERE'S NO NEED FOR A MODEL TO COMPLETE THE WHOLE PIECE。
This can be distributed as follows:
– Environmental set-up, person movement, running, dance, fighting and complex mirrors: Seedance 2.0
– THE PROFILE OF THE PERSON, THE CONVERSATION IS IN THE BACK, THE PRODUCT FEATURE AND THE LIGHT EXERCISE HIGH-QUALITY LENS: CLINT O3
– Common reference for person charts, scenes, action videos and audio: Seedance 2.0
– THE HIGH-QUALITY FRAME HAS BEEN DEFINED, WITH ONLY THE COLOUR AND DETAIL TO BE RETAINED: VIOLIN O3。
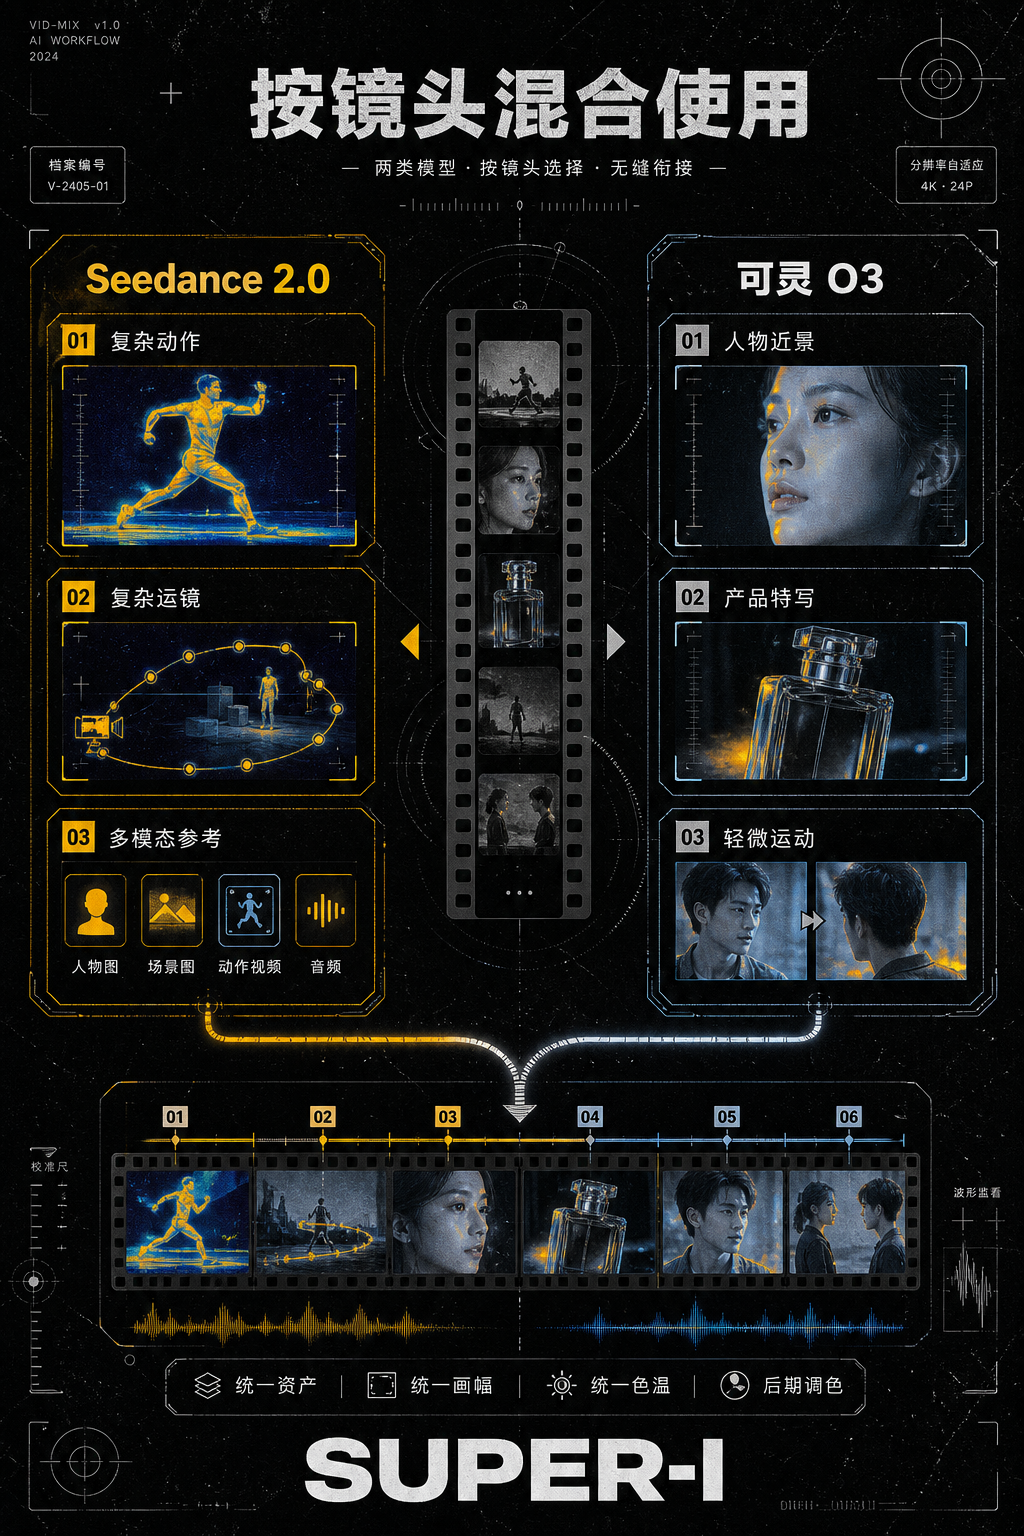
Eventually, the two models are combined with the lenses that are generated by unifying character setting, clothing, product drawings, drawings, color temperature and later coloring. A different model does not automatically cause a break in style, provided that the pre-vision visual standards are uniform and the later stages are corrected as necessary。
IX. FINAL SUMMARY
The choice of Violin O3 and Seedance 2.0 depends mainly on action range, lens complexity, multi-modular demand and graphic target. A full script, a detailed spectroscope and a clear lens description can be sent directly to Seedance 2.0, which is particularly appropriate for content that contains complex actions, large-scale mirrors, multiple lens narratives or multi-modular references。
The strength of Seedance 2.0 is to understand and implement complex campaigns. It is suitable for multi-modular full power reference and for generating large-scale actions from a single front frame. The strength of the Spirit O3 is the cost of 4K, which is more advantageous under the conditions of paint, colour, frontal reduction and current conditions. It is more suitable for conversations that are being fought back, people's minor movements, product viewings and other lenses focused on visual quality。
Instead of deciding which model to use for the whole piece, you have to judge the most important task for each shot. Send Seedance 2.0 for movement and movement, and Clint O3 for paint and detail, and then combine them with clippings and mosaics to get closer to a stable professional production process。