

If the person's skin is more natural, the lens is better, and the movement is more stable, why does the official focus on long narratives, multi-mode references and video editors? And why is the gap between 2.5 and 2.0 less obvious in some simple dance and animation scenes
It's really worth comparing, not “which version looks up to date”, but what really happened to them in their actual creation. Can the characters stay on? Can the state of the first shot continue to the next? Is the relationship between complex actions clearer? Can reference materials be used more accurately? After the generation is complete, can you modify the locals directly instead of the entire article
So in this section, let's re-comparison between Feedance 2.0 and 2.5 in the same creative logic, see what actually went up, what was the most interesting change, and under what circumstances it would be more appropriate to continue to use 2.0, and under what circumstances 2.5。
Chapter 1: What is the upgrade of Feedance 2.5
Following the release of Seedance 2.5, it is easy to turn the first feeling into a sentence if it is just a few of the resulting cases:
It's more real. The person's skin is more natural, the shadows are better integrated and the movement looks more stable。
These changes do exist, but if only 2.5 were to be understood as a “characteristical update”, this upgrade would be underestimated。
Let's take a look at Feedance 2.0。
When it was released in February 2026, Seedance 2.0 was no longer a simple Vincentian video or graphic video model. Officially, there is a unified multimodular audio-visual co-generation structure, which allows for the simultaneous receipt of text, pictures, videos and audio, as well as the availability of complex action, multi-subject interaction, multimodular reference, video extension and video editing. One time you can generate a 15-second multi-media video content。
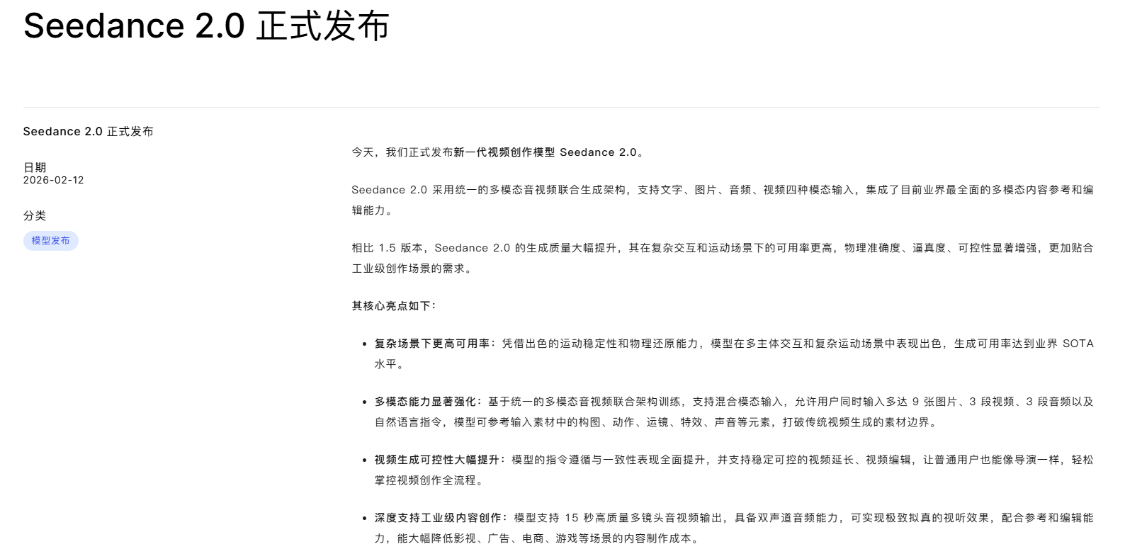
Official introduction
So we can't simply understand:
2.0 won't be complicated。
2.0 cannot be edited, 2.5 can be edited。
Indeed, many of the capabilities that we see now are already in place in 2.0。
2.5 The real thing to do is to move forward in a few very important directions for full video production on the capability framework already set at 2.0。
The official orientation of 2.5 is also very clear: the demand for users is moving from “to produce a video clip” to “to complete a complete creation”. Thus 2.5 focuses on long narrative, multi-modular reference and editorial capabilities and further improves the quality of images, voices and movements。
A brief summary of this change can be understood as:
Seedance 2.0 is already very good at generating videos, and Seedance 2.5 is beginning to focus more on how to make a video in its entirety。
That is also the premise of our next understanding of all upgrades。
Because 2.5 really opens the gap, it doesn't have to be in a simple five-second shot。
The advantage of 2.5 will only be magnified as the video grows longer, the number of people and the complexity of the movement, the amount of material to be consulted and the need for continuous modification after generation。
Chapter 2: From 15 to 30 seconds, the real upgrade is "continuous creation."
One of the most easy changes to understand is the length of a single video。
Seedance 2.0 supports 15 seconds of high-quality multi-membracing video output, while 2.5 increases the single-time generation time to 30 seconds and supports continued extension. The official emphasis was also placed on 2.5 reinforcing camera switching, scene conversion and continuous narrative capability in long videos rather than simply dragging an action from 15 to 30 seconds。
There are two very different concepts here。
The first one is called: The video is longer。
The second is called: The story can be longer。
It's, of course, a long video if it's just a 30-second walk on the street, but it doesn't mean so much for real video creation。
The real difficulty is that people leave the room first. Through the corridor. And interact with another person. Then into new space. Finalize a new action。
The official 30-second case in 2.5 involved a person moving out of the backstage dressing room, passing through the backstage channel, interacting with staff and dancers, and finally getting on stage. In other words, 30 seconds inside is not just a scene, but can organize multiple lenses of logic。
it's from byte beatseedance2.5 official
T2V prompt: One shot with a hand-held stabilizer and a camera slowly advancing from the red thick curtain gap to the hot backstage dressing room. Young female singers were back-to-back-to-face headphones and were reminded by staff that she was ready to go on stage. She looked back at the camera and started singing City Pop. Back-scenes follow, singers walk through the curtain into the back channel, naturally interact with their partner, and a staff member hands her the microphone. The singer and the dancer then went up to the stage, and the camera went around the back, and the red and black dances, the LED screen, the pursuit of light, the smoke and the reflection floor gradually spread. The camera was eventually brought to the stadium, with a crowd of viewers, lightboards, fluorescent sticks and cheers, and created an atmosphere of youth freedom。
At that point, the importance of coherence began to emerge。
We used to sayAI VideoThe most common is the face。
The first frame is this character. The last line is this character. The face hasn't changed, it's called the same. But it's not enough to really do a continuous video。
For example, a girl just got wet in the first shot。
When she enters the room, the Five will certainly remain the same。
But more importantly:
Her hair should still be wet。
There should be rain on the shoulder。
The umbrella in hand can't just disappear。
If the person in the previous shot had experienced a fight, the injuries on the next shot, the broken clothes and the state of his body should also continue。
So real continuity has at least three layers。
The first level is continuous identity。
The character is the same person。
The second level is visual continuity。
Clothes, hairstyles, accessories, props, scenery have not changed inexplicably。
The third level is continuous。
What has happened to the first shot is still there。
Comparative examples
Compare the same hint, personal assets
Video alerts are as follows:
The same adult young female investigator, approximately 26 years of age, has short hair in black, is cold and white, is very sharp, and is alert and restrained. She was wearing a dark gray short waterproof coat, which contained white shirts, black long pants, black short boots, a dark brown old leather bag on her right shoulder, and a long, black umbrella in her right hand. There was a fresh graft in the position of the left cheekbone, a slight fracture in the mouth horn and traces of dust and a slight tear in the left shoulder and sleeves of the coat. Throughout the video, the profile of the five officials, hairstyles, clothing, purses, umbrellas, position of wounds and overall quality remained consistent。
Story happens on rainy night. The figure had just experienced a chase and a brief fight, running out of the narrow alley and slowing down under the dark lights. Her short black shoulder was wet by rain, with a few stubbles on her forehead and face, and her white shirt neck and shoulder were wet by rain. She was in a hurry to breathe and later confirmed that no one was coming after her and then headed for the corner of the corner。
In this situation, she pushed the glass door of the convenience store into the room. The identity and shape of the person remains completely unchanged, the hair is still clearly wet, the shoulder and sleeves of the coat are still covered with rain and dust, the left face is bruised, the mouth of the mouth is broken and the slight torn marks on the left shoulder of the coat continue to be preserved. She was standing by the door, breathing slightly, quickly observing the inside of the shop, closing the umbrella slightly and the rain fell to the ground along it. The light in the warm yellow shop naturally works on her moist hair, skin and coat, creating a clear internal and external photolytic。
She then took a shot and entered the narrow back of the corridor behind the front desk of the convenience store. It is still the same face, the same black shoulder short hair, a dark gray waterproof coat, a white shirt, black long pants, black short boots and a dark brown old leather bag. The left cheekbone bruising, the broken mouth, the slight tearing of the left shoulder and dust marks of the coat continue to be preserved, the hair and shoulder remain in a damp state, and the top of the coat still shows traces of undried rain。
She placed the black long handle umbrella on the side of the wall, but the bag remained on the right shoulder and did not suddenly disappear. It then went to the back silo metal wash and looked at the mirror to see the wound on the left face, rubbing light water and blood on the side of the face with its back. Her breath was steady, but she remained vigilant。
Finally, she took over the condition and, after simple treatment of the wound in the back, took the black long handle umbrella again, returned from the back and was ready to leave. Five officials, hairstyles, clothing and purses remained exactly the same, and bruises on the left face remained in place, although the blood was simply wiped and the mouth was still slightly broken. Hair and jackets are still wet, but little less water than when they enter the door, with a semi-wet state of natural transition, and the dust on the left shoulder and cuffs of the coats and slight tear marks remain。
She stood at the door of the convenience store, looking through glass at the rainy night streets outside, confirming that it was safe to open the black umbrella and push the door back into the rain. The whole video requires strict identity, vision and state continuity, without random changes in the person ' s looks, clothing, props, wounds and scene logic; rain, injury, fatigue and vigilance that have already occurred in the previous lens need to continue naturally in the follow-up。
The camera as a whole uses film-sensitization style. It starts with a middle view and a rain night, and then slowly moves to a semi-near view; enters the convenience store and follows the person to a semi-observation camera; the back section slowly moves from the center to the mirror; and finally follows with a side-massive lens on the front door. The whole highlights the state of damp hair, wounds, broken coats, continuous tight umbrellas, purses and characters, real light, fine material and a continuous narrative atmosphere。
This is my character
comparison effect
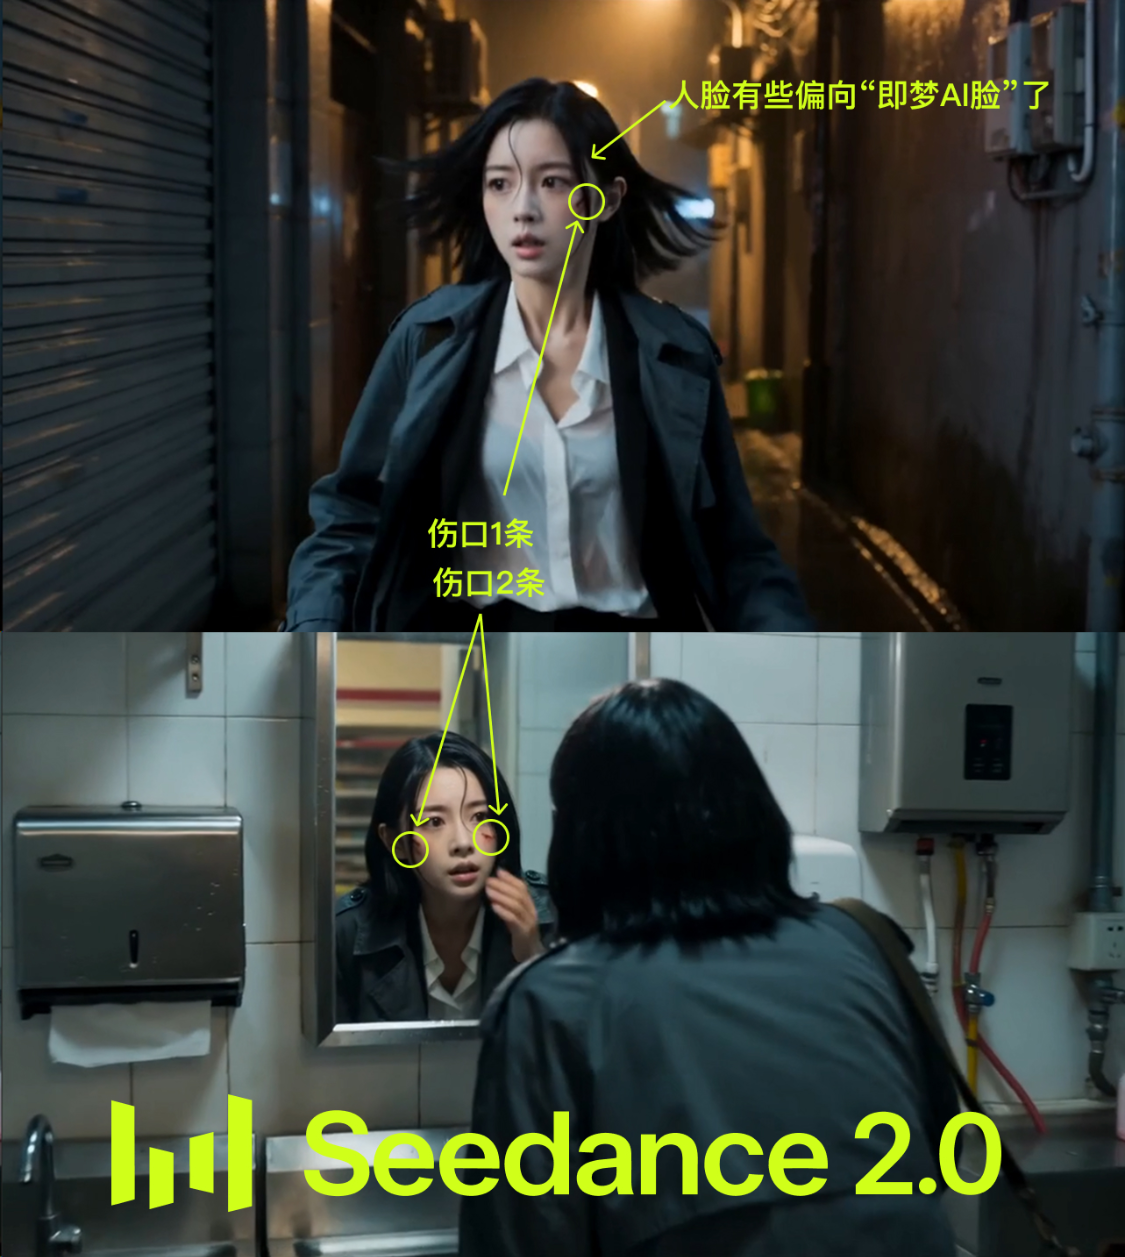
effect of tedance2.0
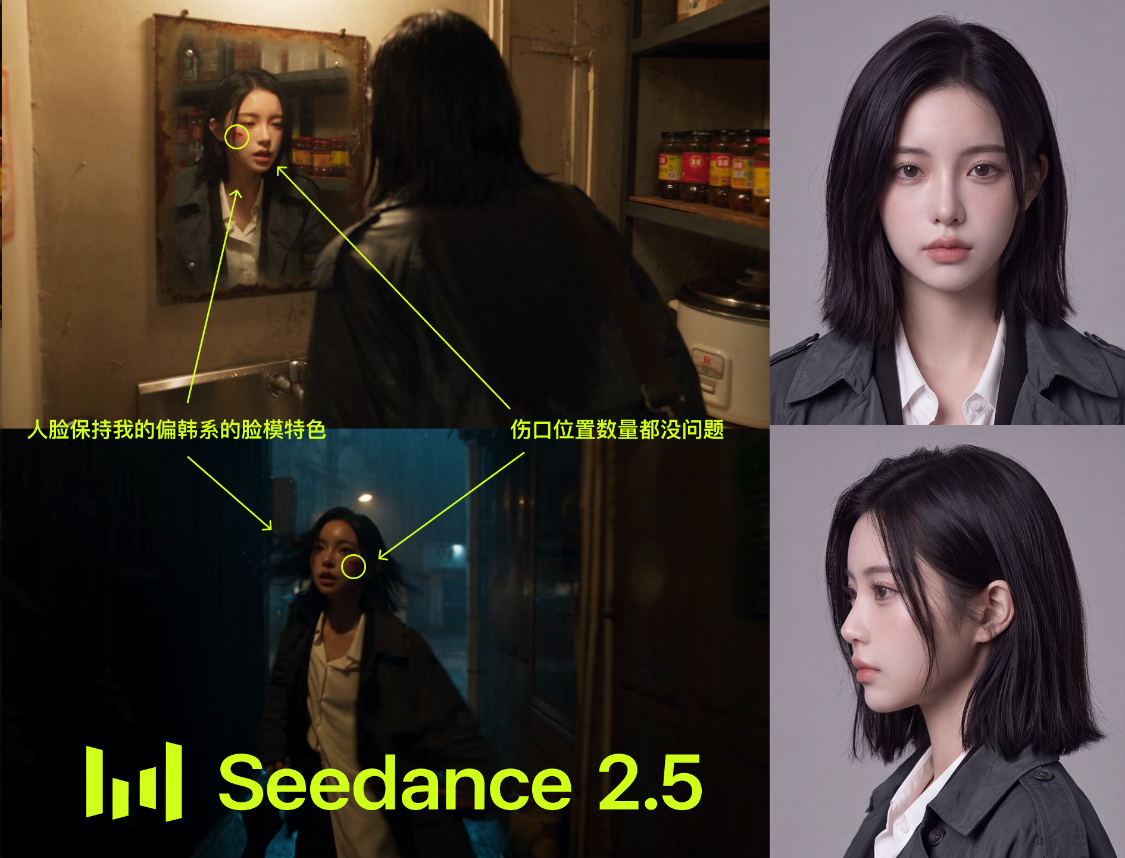
the effect of seeingdance2.5
Of course, “state consistency” is not an official, separate functional name, but is more a form of creative experience that we draw from the results of actual generation。
BUT IT'S VERY IMPORTANT FOR SHORT PLAYS, SERIAL DRAMAS, A SINGLE SHOT AND TVC。
The official video extension also mentioned in particular that 2.5, while continuing to produce follow-up footage, would enhance the continuity of key figures, the environment and the overall narrative rhythm。
So from 15 seconds to 30 seconds, it's time on the surface。
What really matters is that the model begins to have more room to process:
Personal status。
Space change。
Camera relation。
Story development。
And the continuity of the lenses。
This is much more valuable to videos that require a full narrative than a simple 15-second increase。
Chapter 3: The picture is more real, but what really changes is the person, the light and the movement
1. Personality
If Chapter II is about “Can video be kept,” then it solves another problem:
After holding down, does it look real enough
During the release of Seedance 2.5, the official reference was made to the common sense of artificial generation of the AI video, which optimized the mass of the object, the skin and eyes of the person, the light shadow and the colour saturation, as well as a further increase in physical performance。
This is particularly visible in the human content。
Because the sense of truth does not come only from pores and resolution。
It also comes from whether the person is actually affected by the environment。
For example, the person standing under a warm yellow light should naturally appear on his face。
The person enters the blue night view and the skin, hair and clothing should also reflect in cold colour in the environment。
When a person passes through a strong light, the light should change naturally as the person moves。
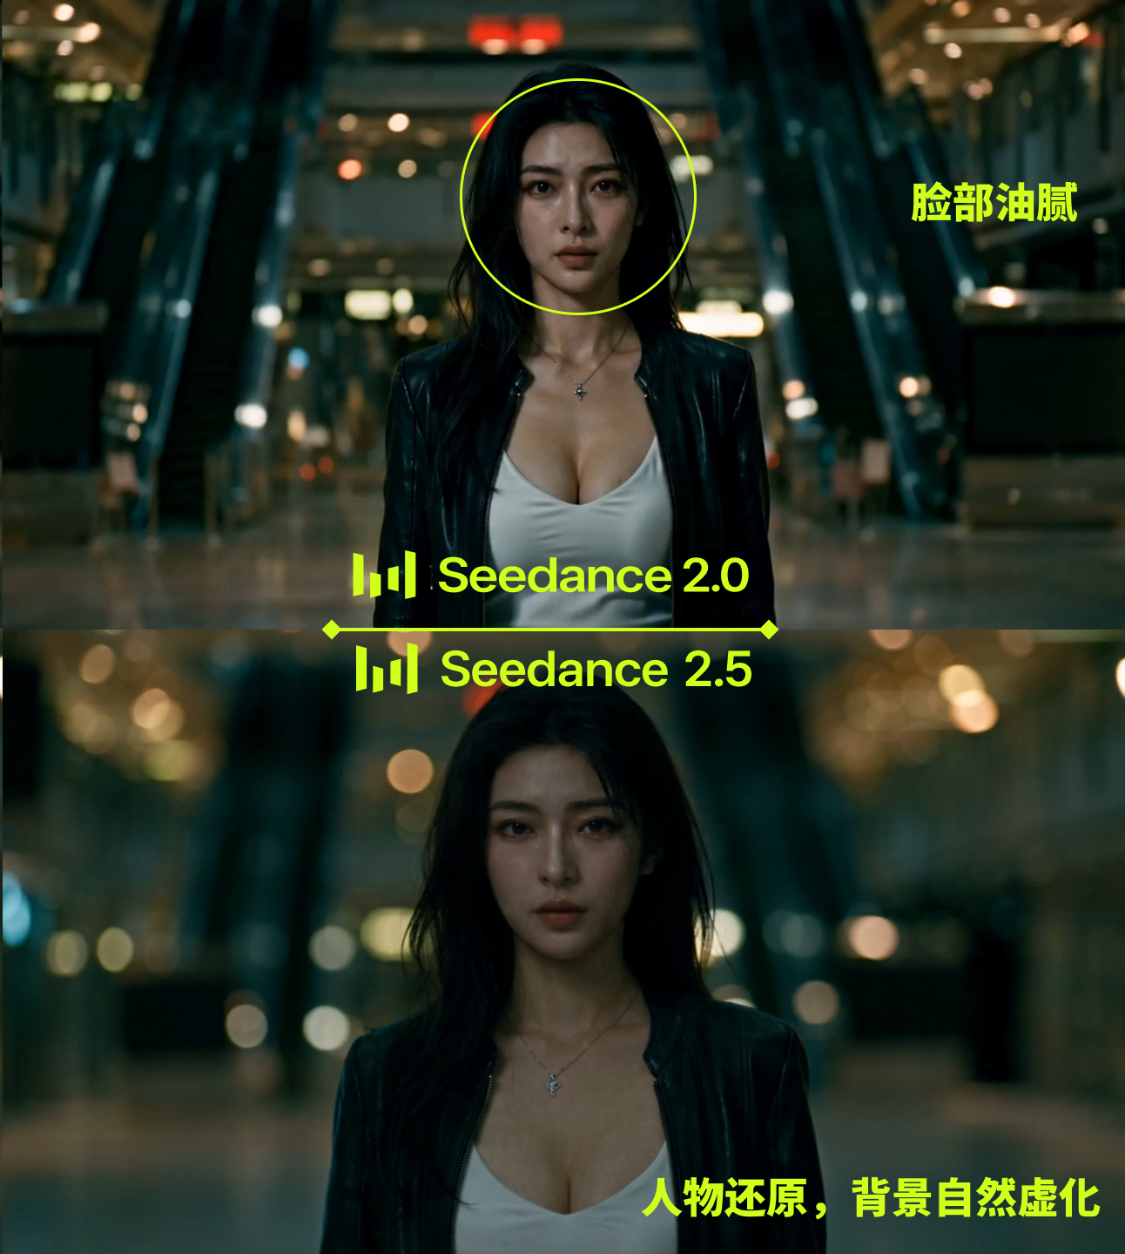
2.0 Local colours of yellow and grey are more likely to be found in some of the profile of the person, and the person ' s skin is more likely to feel similar to wax; in the 2.5 test, the integration of the person with the surrounding light becomes more natural。
This is my personal asset chart:
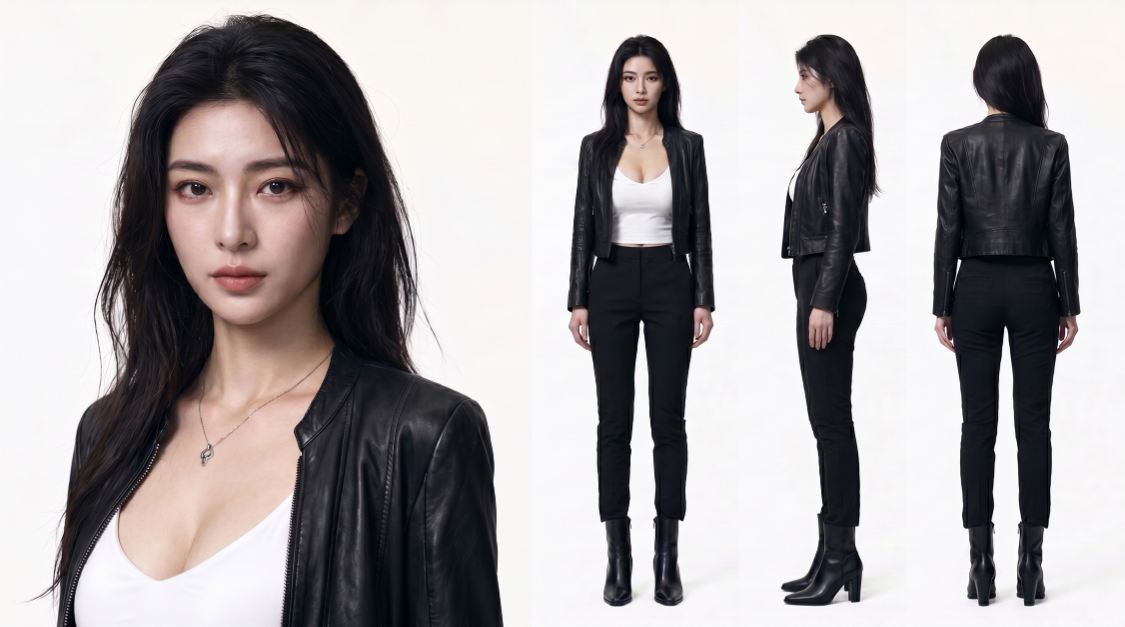
Video alerts are as follows:
One shot at the end, a Cubrick-style suspense shot, with a long focus on the person, and then a slow, short focus on the landscape. The middle court in Hong Kong's high-end mall was closed on the night after the rain, with space empty, quiet and cold, and Hong Kong wind film writing a sense of substance. Image 1 of the young Asian female hero in black leather, standing in the middle of the court, wearing black short leather jackets, white silk straps, black high waist trousers, black short boots, small silver locks, consistent faces, consistent clothing。
The camera began to use a long focus view, only her face, shoulder and upper body. Rather than standing in a rigid state, she was in a state of perceived abnormality: a mild breath, with her eyes looking forward and slowly looking to the second level, a slight tightening of her lips, a soft touch of her fingers on her chest, and a calm but vigilant expression. Scatter the background
The lens then remained absolutely stable, with strict mid-axis symmetry, slowly moving from long to short focus, and the horizon gradually opened from the medium to the panorama. The complete environment was revealed: she was standing in the middle of the post-closure mall, with all the luxury shops around her being closed, the escalators stopped and the second-floor corridor was empty. All the advertising and electronic window screens around the perimeter were on at the same time, and every screen was showing real-time surveillance images of her standing in the middle of the courtroom, like the whole mall was watching her. The protagonists are becoming smaller in the landscape and the sense of space oppression is growing. In the end, she looked up slowly, looking at one of the screens and realized she was locked。
green shadows, amber-coloured mall heat light, red security light dots, 35 mm film particles, low luminous contrasts, real camera movement, film writing substance, no text, no logo。
So we can understand this upgrade more precisely。
It's not simple:
2.5 higher。
They are:
2.5 The relationship between characters, materials and the environment is being improved。
A static picture is real, just a first step。
Complex movements
When you actually get into the video, you have to see if it's real。
This is another important upgrade — complex moves。
Here again, the relationship between 2.0 and 2.5 needs to be made clear。
When Seedance 2.0 is released, complex action and multi-person interaction are in themselves important capabilities. The official display of difficult sport cases, such as double-skating, and the emphasis on physical motion, physical relations and interaction stability in complex operations. It has even been able to deal with complex situations with more role and more detailed description。
it comes from a byte beatseedance 2.0 official blog
T2V prompt: a competitive double-skating scene. The opening lows follow the skates, and the details of the ice chips and the reflections are clear. Entering the rotational segment, the male axle slightly failed and the rotational rhythm collapsed. The women quickly refocused their focus, looked calmly and suggested “Stay with me” and took the initiative to steer the men back to the rhythm. The line was then seamlessly connected and stabilized. The climax is a synchronous jump combination, a straight air posture, a clear ice, and a perfect alignment of sound. The women were wearing a dark blue dress and the men were dressed as competitive sports. The whole picture is a full narrative from stress failure to cool completion of the competition, reflecting the technical and psychological strength of top double skating。
So we can't say 2.0 doesn't understand the movement at all。
More precisely:
2.0 has been able to complete complex operations, and 2.5 continues to improve continuity, naturality and interaction in complex movements。
In particular, in the context of fighting, this distinction is more evident。
THE PROBLEM MOST LIKELY TO ARISE IN AI IS NOT “NOT STRONG ENOUGH”。
ON THE CONTRARY, MANY AIS ARE PARTICULARLY FIERCE。
Two people have been waving. Always running away. The body keeps spinning. The camera is also moving crazy。
The problem is you don't know anything:
Who hit who? Who's working. Why did this man suddenly fly out? What's the relationship between one and the next。
In the 2.5 test, the connection and interaction between actions is more evident。
Comparative examples
it's okay to create it, but it's been created many times, and it's too flaunted, and it's not stable enough for the gun and the sword
i seedance 2.5 straight out, the mirrors are more stable, and every weapon collision is strong
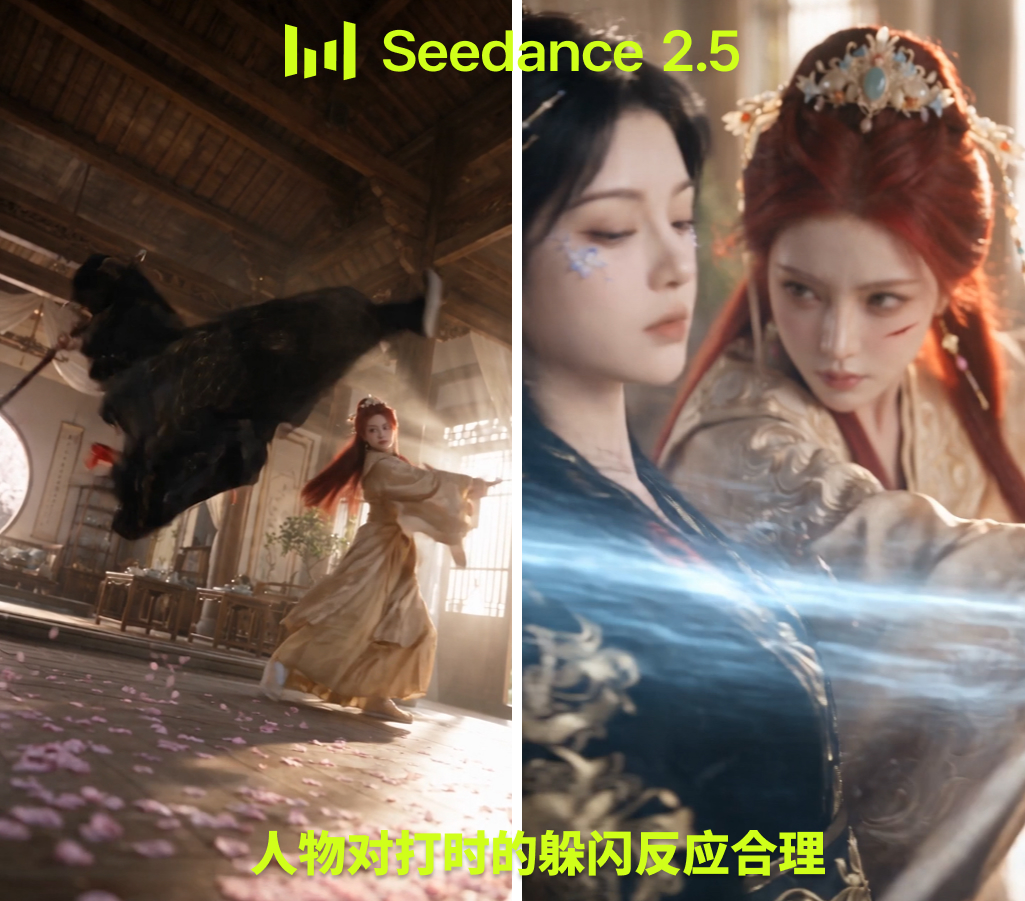
We can sum up this change in one sentence:
From " action can be generated " to " action relations become clearer " 。
However, 2.5 did not fully address all physical problems. The same restriction is retained in official statements, which clearly indicate the physical legitimacy of complex movements and the stability of a large number of subjects when they interact at the same time。
So 2.5 makes complex actions more useful, but it does not mean that all of them can be successful once in a while。
For us, it is a more reasonable understanding:
Easy move, 2.0 is working。
The advantage of 2.5 is even more evident when there is more complex interaction, contact, stress and continuous movement among people。
CHAPTER 4: WITH THE UPGRADING OF REFERENCE SKILLS, AI VIDEOS ARE BECOMING MORE AND MORE LIKE DIRECTOR-MADE
In addition to long video and image quality, 2.5 is a very easy-to-neglected but in fact has a significant impact on professional creation:
More and more complex reference materials can be used。
Seedance 2.0 itself supports a very complete multi-modular reference。
A single generation allows the input of up to nine pictures, three videos and three audio segments at the same time, combined with a text instruction to refer the model to the characters, graphics, actions, mirrors, sound and visual effects of these materials。
it comes from a byte beatseedance 2.0 official blog
R2V prompt: Reference @Photo 1 Script script, Reference @Photo 1 Spectrum, Speculation, Mirror, Image and Script, character character character @Photo 2, scene @Photo 3, props @Photo 4, creating a 15s healing film。
It's actually a lot of short video。
Up to 2.5, a single generation of up to 30 pictures, 10 videos and 10 audio sets can be generated, with a significant increase in reference capacity. At the same time, different modes of reference, including action, creativity and structural references such as white models, continue to be strengthened。
The most important thing about this upgrade is not:
"I can finally upload 30 pictures."
What really matters is:
We don't have to put everything in the hints anymore。
it's from the byte beatseedance2.5 official blog
R2V prompt: 30 seconds of concert session, 16:9, screen, film-sensitization, real music hall light, warm gold stage lights, formal classical concert atmosphere. The scene @Figure I, Pianist reference @Figure II, cello reference @Figure III, violin reference @Figure IV, lead sing reference @Figure V, other bands such as orchestra reference @Figure VI to Fig X, choir references @Figure XV to XVIII. Central to the stage is the front, the pianist is by the piano, the band is on both sides and back, and the choir is behind the stage. At the beginning of the concert hall, the pianist drops the key, the lead singer goes into the light, and the camera carries the violin, the cello and the orchestra, the violin is bright and the cello is warm. In the latter band, the lead singer communicates with first-row viewers for a short time and the audience smiles and nods. The end shot, the end of the performance, the audience followed by applause。
Chapter V: Precision
Seedance 2.0 actually supports video editing and extension and can be adjusted for the specified content. Therefore, 2.5 is not the first time that Seedance has editorial capacity, but rather continues to move in a more precise and stable direction。
2.5 Increased time control。
At the generation stage, we can schedule the content according to a specific time frame, including what happens in this period, how the camera changes and when the scene turns。
Once the generation is complete, the person, action or plot in a particular section may also be tailored, while maintaining, to the extent possible, the continuity of the modification。
Chapter VI: 2.5 is not a complete replacement of 2.0. What should be the choice
Under what circumstances continue to use Feedance 2.0
The video itself is relatively short。
There are only 2-3 subjects。
People move simple。
It doesn't need to be too complicated to continue。
There are few references。
There is little need for repeated modifications after the generation is completed。
In this case, 2.0 remains a very mature video generation model and there is no need to impose 2.5 for “new”。
What's better for Feedance 2.5
It takes more than 15 seconds of a series。
There are multiple lenses, multispace changes。
People need to be consistent over time。
Back-and-back lenses need to inherit the character status。
It includes complex actions such as fighting, chase and multi-person interaction。
A large number of people, scenes, products, actions and sound references are needed。
TVC, PLAY SHORTS OR PROFESSIONAL ADVERTISEMENTS ARE BEING PRODUCED。
It will also require partial modifications, re-products, mirrors or further extensions。
These scenes are where 2.5 really have an advantage. The overall official orientation of 2.5 also focuses on 30 seconds of narrative, more precise reference control, more reliable editing and professional video production processes。
Conclusion
If we really compare Feedance 2.0 with 2.5, we find that this update is not a simple graphic upgrade。
Seedance 2.0 has developed a very complete set of AI video capabilities: multi-modular input, complex movement, character consistency, audio-visual synchronization, video extension and editing, which do not suddenly appear in 2.5。
2.5 What is really going to be done is to continue to advance these capabilities towards complete production。
Fifteen seconds becomes 30 seconds, but it is important that long narratives become more complete。
Coherence continues to rise, but it is important that the status of the person and the lens relationship become more sustainable。
The picture is more real, but what matters is not just clarity, but more natural between people, light, materials and the environment。
So if it's important to sum up in one sentence the biggest difference between Feedance 2.5 and 2.0, I would like to understand this:
Seedance 2.0 addresses “how to generate a good video”, and Seedance 2.5 begins to address “how to complete this video”。