

WHY DO SOME OF THE A.I. CHARACTERS APPEAR FOR ONLY A FEW SECONDS AND WE CAN REMEMBER? THE REASONS ARE OFTEN HIDDEN IN SEVERAL CLEAR FEATURES: A SLIGHTLY EXAGGERATED HAIRCUT, CAREFULLY DRESSED AS A MEETING, ACCOMPANIED BY AN UNEXPECTED MOVE. THE CONTRAST BETWEEN THE PERSON'S APPEARANCE AND BEHAVIOUR ADDS A LITTLE BIT TO THE ORDINARY SCENE。
In this section, we're going to design a visible role from zero, and then let him do a natural, rhythmic move. NothingHiggsfieldMembers can also use available reference materials to complete the demographic synthesis in their usual canvass. It's more useful to know the division of material and the lingo than to remember the position of a button
So then, in my thinking and in my steps, you can do something like this. Let's do it
Step 1: Access to the Higgsfield official network to select reference pictures
Opens the Higgsfield website and finds the AI Inflencer character section (click jump)
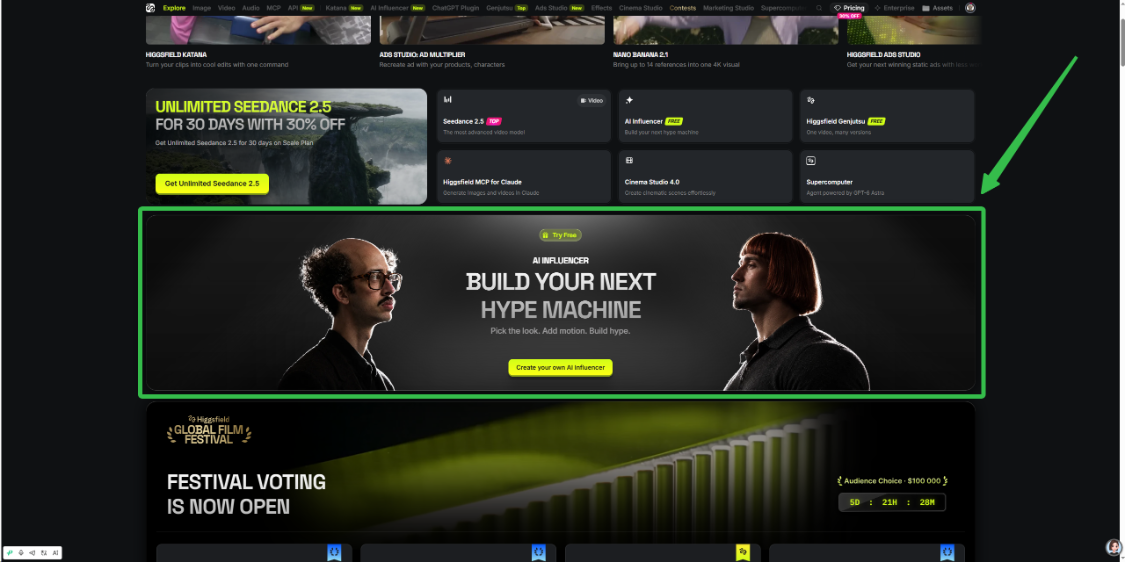
Upon entry, the selected person is examined for face, hair, body and clothing. Select your favorite head, top and bottom, and find the preferred ones to download directly。
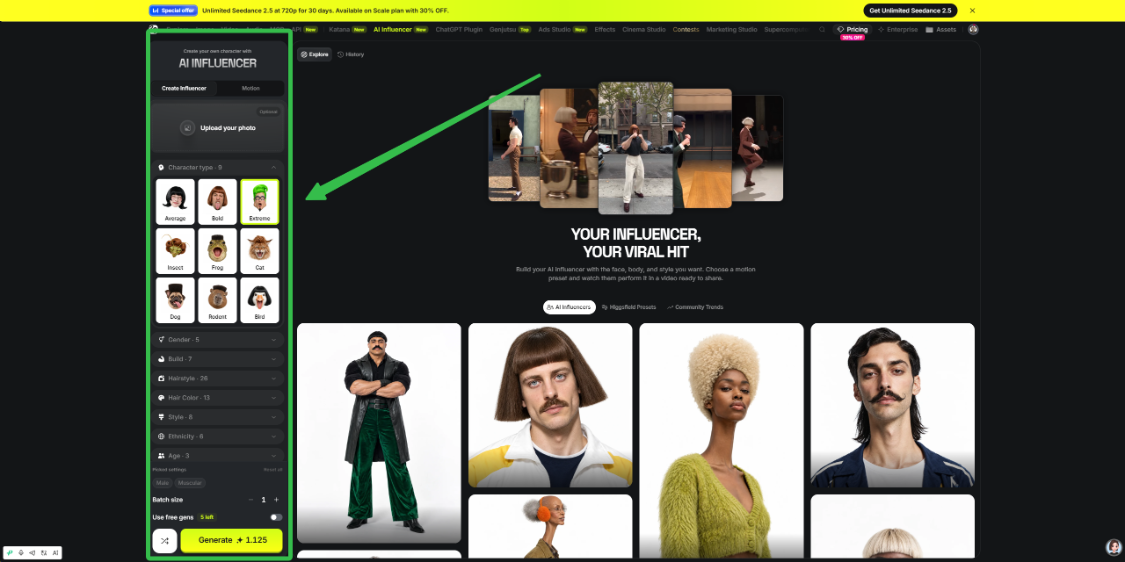
Step two: Import canvass, synthesize complete characters
When you get a reference, open your usual canvas. You can use FlowPix (click to open the web page) or libTV or Tapnow. We need to use seedream 5.0pro/ Nano banana pro/ Gpt image 2.0。
Imports a header, load, and lower load separately, and adds a picture to generate node, using three charts as reference material for that node. The model is available for Sedream 5.0 Pro, Nano Banana Pro or GPT Image 2, provided that the canvas used is already connected to the corresponding model. They provide image generation or editing capability, with the number of reference maps and the billing of charges being the entry point。
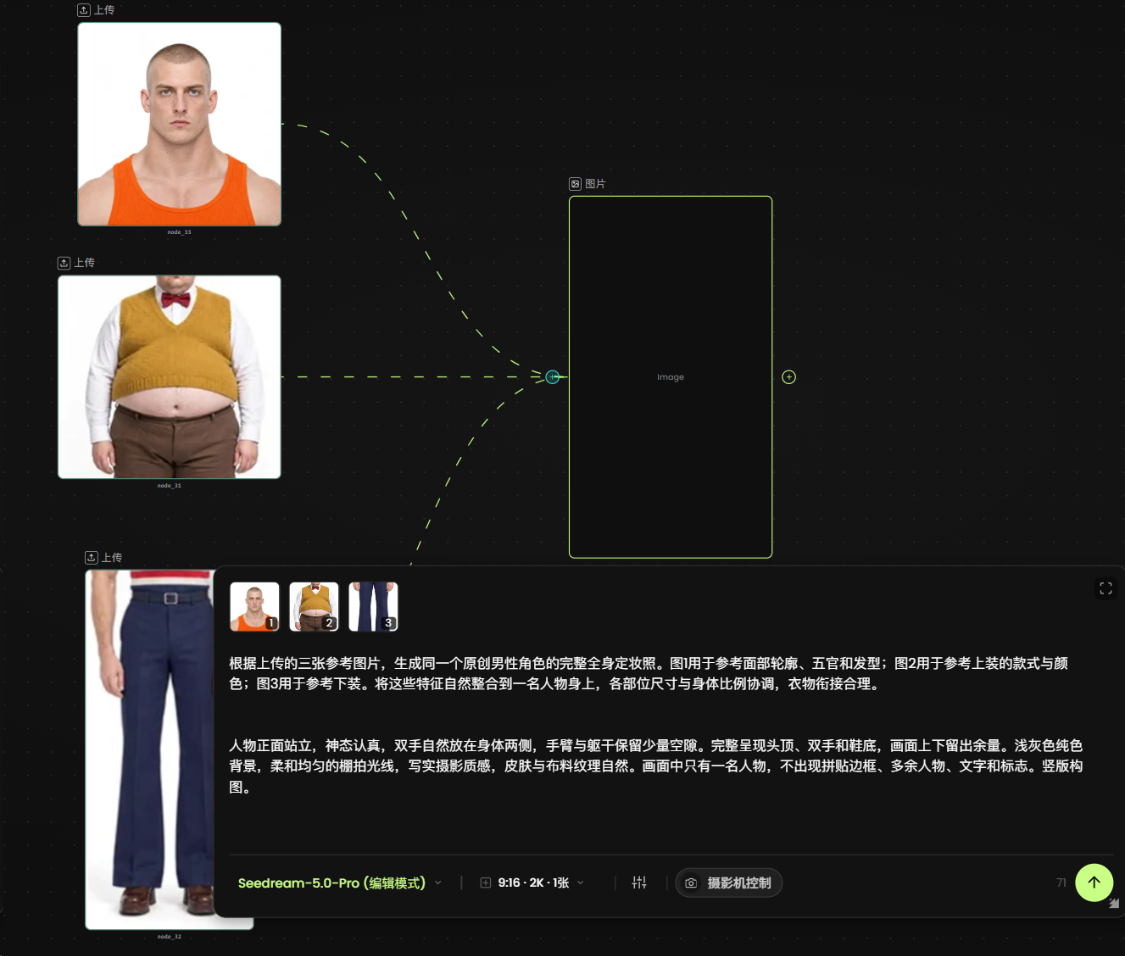
This route allows for the synthesis of characters out of the Higgsfield membership process, but the models in the canvas may still be charged. The budget should be organized in both person charts and videos, first to confirm the image of the person and then to start video production。
The term “mix these pictures into one person” is too vague, and models may generate a collage directly, or may mix the faces of several of them. In turn, they should describe the use of the material, the structure of the person, the image and the style of the image。
The following example can be used to maintain the order of upload:
Based on three reference images uploaded, a full-body make-up photograph of the same original male role was produced. Figure 1 refers to the profile of the face, the five officials and the hair type; figure 2 refers to the style and colour of the upper load; and figure 3 refers to the lower load. These features are naturally integrated into a person, the size of the section corresponds to the body ratio and the clothing is properly connected。
The person stands face-to-face, takes his or her mind seriously, with his or her hands on both sides of the body, and leaves a small gap between his or her arms and torso. Full display of head, hands and soles of shoes, with leftovers up and down. Light gray, pure background, soft and even shed light, written photo sense, skin and fabric texture natural. There is only one person in the picture, and there are no collages, redundant characters, words and symbols. A vertical map。
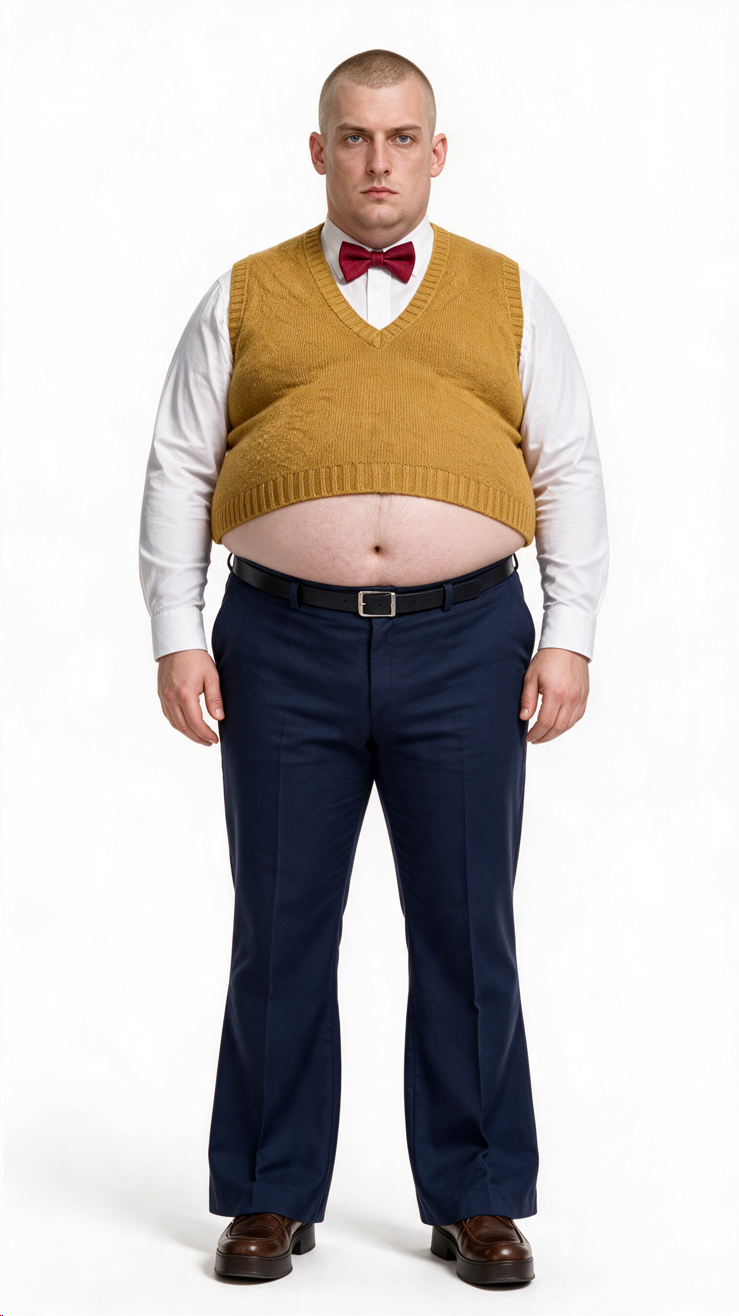
Figure 1, figure 2, figure 3 are illustrative numbers only. If the canvas assigns other names to the material, the actual name is used for the input or the corresponding picture is selected through the reference button to avoid inconsistencies between the numbering and the material。
Once the person is identified, the whole body chart is saved and the scenes and movements continue。
Step 3: Select a suitable action video
Opens a shivering or other video platform, looks for a dance video that you like more, downloads it and saves it as an action reference for later role videos. You can also choose other interesting characters, so let's move the role we just synthesize。
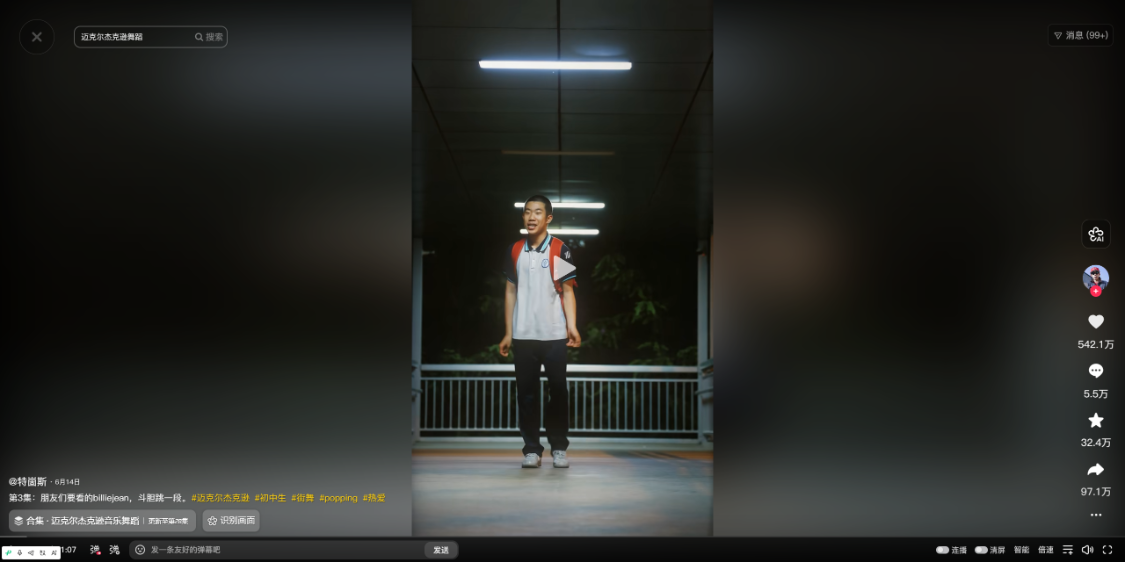
This is the video I'm looking for. It's from @Terius
Step 4: Convert action footage into deep video
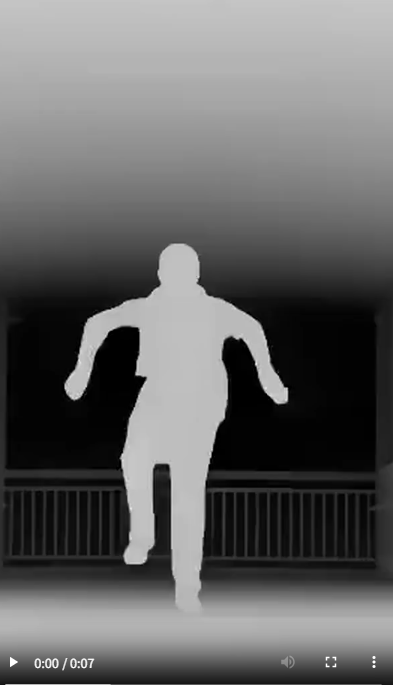
Opens libTV (click on the web page), uploads the dance video that has just been downloaded, using the video-to-deep video function inside. Upon completion, the generated deep video is downloaded and next used with the image of the person, so that the character can refer to the action in the video。
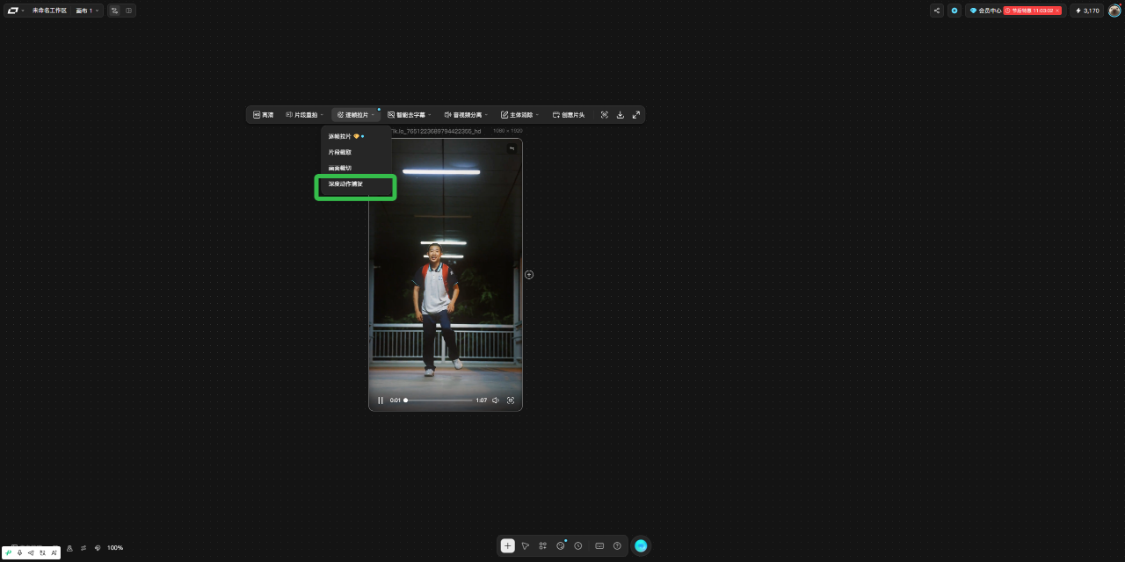
Step 5: Generate role videos in combination with person charts and depth videos
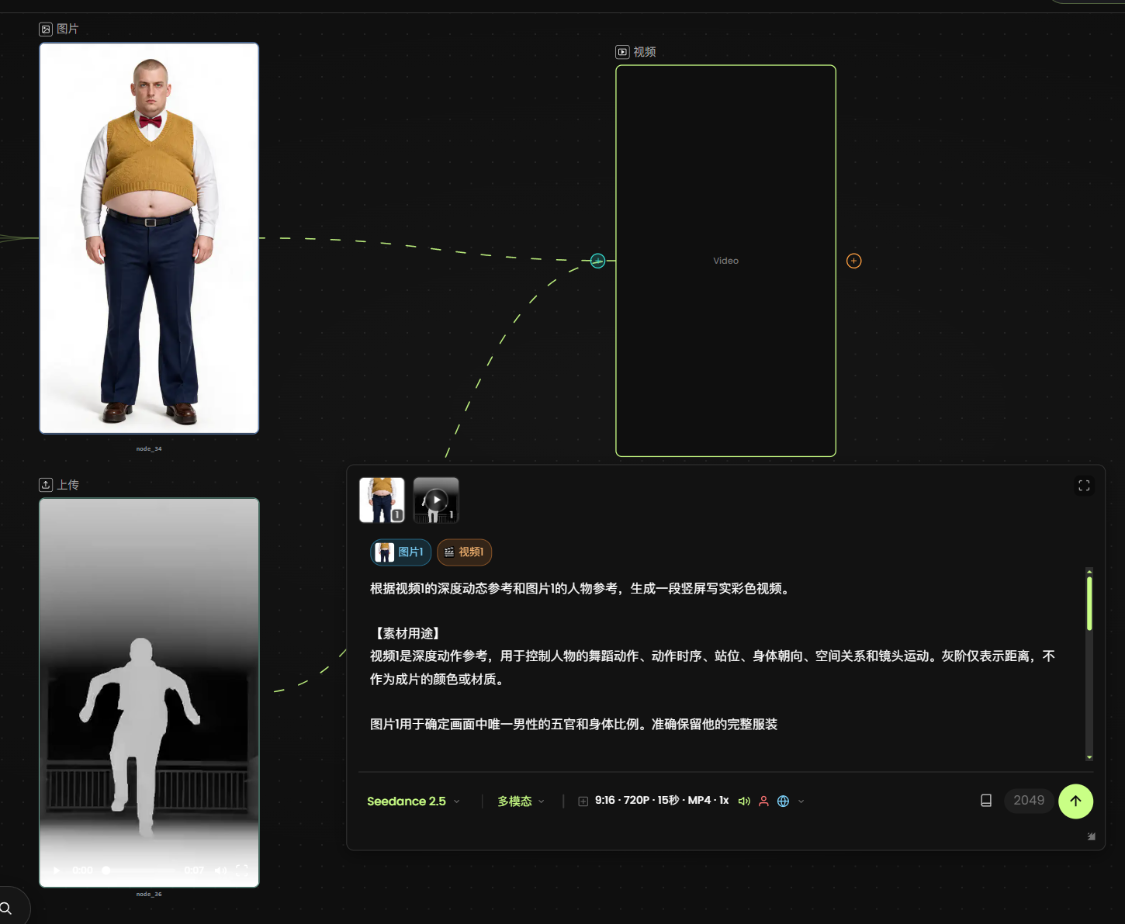
Go back to the canvas, create video generation nodes, and choose the mode that supports graphic and video reference. You can try Feedance 2.5
The figure is used as a visual reference, and deep video is used as an action and space reference。
The following examples are based on fixed-space dance clips, which are used instead of their own:
Based on the depth dynamic reference for video 1 and the character reference for picture 1, a wall-screened coloured video is generated。
The material
Video 1 is an in-depth action reference used to control the person ' s dance moves, movement time, position, body direction, space relations and lens movement. The grey steps represent only distance and do not act as the colour or material of a piece。
Photo 1 is used to determine the ratio of five officers to the body of the only male in the picture. Keep his whole outfit exactly
[actions echoing]
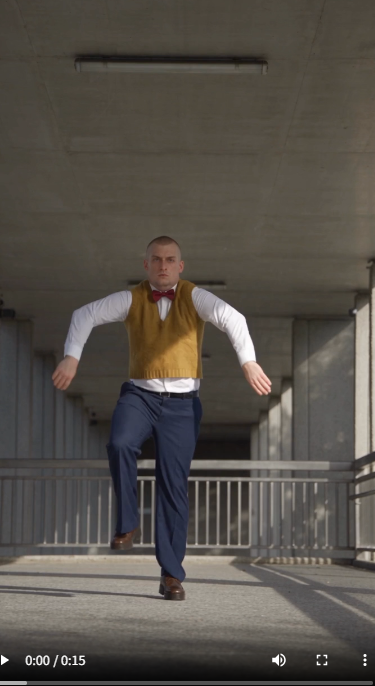
The person completes a continuous dance according to video 1. The person follows the arms of the person with the exact lifting and withdrawal, the right and the right arm, the knee, the side step, the right and the left, and the weight shift. The sequence of actions, the direction to the left, the range, the speed and the pause time are based on video 1, which does not mirror, does not add new steps, and does not repeat actions。
Keeps a serious look on the face of the person, contrasts with the movement of the dance. Head direction and body movement follow video and facial identity and body ratio remain stable。
"Scene and Camera"
Based on the background structure of video 1, a real gallery scene with poles, horizontal bars and peace on the ground is generated. The use of natural, soft sunlight and low saturated building colours, and people's exposure to light and surface projection are consistent with the environment. The white photo background of the character reference map is not used。
Keep the full body image of video 1, the figure ratio and the camera motion, and do not add to the face. Foot contact with the ground is accurate, supports foot stability, does not slip and projectes the physical movement of the person。
"Image Request"
Real photography, one shot at a time. Five officials, hairdressing, dress-levels and material-by-frame. To avoid the reproduction of people, the drift of their faces, the deformation of their fingers, the slippage of their feet, the piercing of their skins, the colouring of their clothes, the distortion of their bars and the blinking of their background。
There are no subtitles, superscripts, slogans or watermarks。
Once the action test has been completed, the tunnel can be converted to a streetside, stage or large indoor space。
For example, the scenery should be changed to read: “The background is a quiet street with retrogressive buildings, where the person stands on a flat sidewalk, with a positive fixed position, full-body lens, and light in the sun and nature.”
The exercise in this section could begin with a “full figure, plus a five- to eight-second single-person action”. The appearance, movement, lenses and space are first reciprocated and then the scenes and dramas are gradually increased. The more indicative the text, the easier the production process will be。