



Today, I'd like to introduce you to a proposal by the Beijing Institute of Artificial Intelligence for a unifiedImage Generation ModelOmniGenOmniGen can be used to perform a variety of tasks including, but not limited to, text-to-image generation, subject-driven generation, identity preservation generation, image editing, and image condition generation.OmniGen requires no additional plug-ins or operations, and it automatically recognizes features (e.g., desired objects, body poses, depth mapping) in the input image based on textual prompts.
Related links
- Thesis: https://arxiv.org/pdf/2409.11340
- Code: https://github.com/VectorSpaceLab/OmniGen
- Trial: https://huggingface.co/spaces/Shitao/OmniGen
summarize
OmniGen is a unified image generation model that generates a variety of images based on multimodal cues. It is designed to be simple, flexible and easy to use. The authors have provided the inference code so that everyone can explore more features of OmniGen.
Existing image generation models often need to load multiple additional network modules (e.g., ControlNet, IP-Adapter, Reference-Net, etc.) and perform additional preprocessing steps (e.g., face detection, pose estimation, cropping, etc.) in order to generate satisfactory images. However, we believe that future image generation paradigms should be simpler and more flexible, i.e., generating various images directly from arbitrary multimodal instructions without additional plug-ins and operations, similar to how GPT works in language generation.
Due to limited resources, OmniGen still has room for improvement. The model will continue to be optimized and hopefully it will inspire more general image generation models. You can also easily fine-tune OmniGen without having to worry about designing a network for a specific task; all you need to do is prepare the appropriate data and run the script. Imagination is no longer limited; everyone can construct any image generation task, and maybe we can achieve really fun, fantastic and creative things.
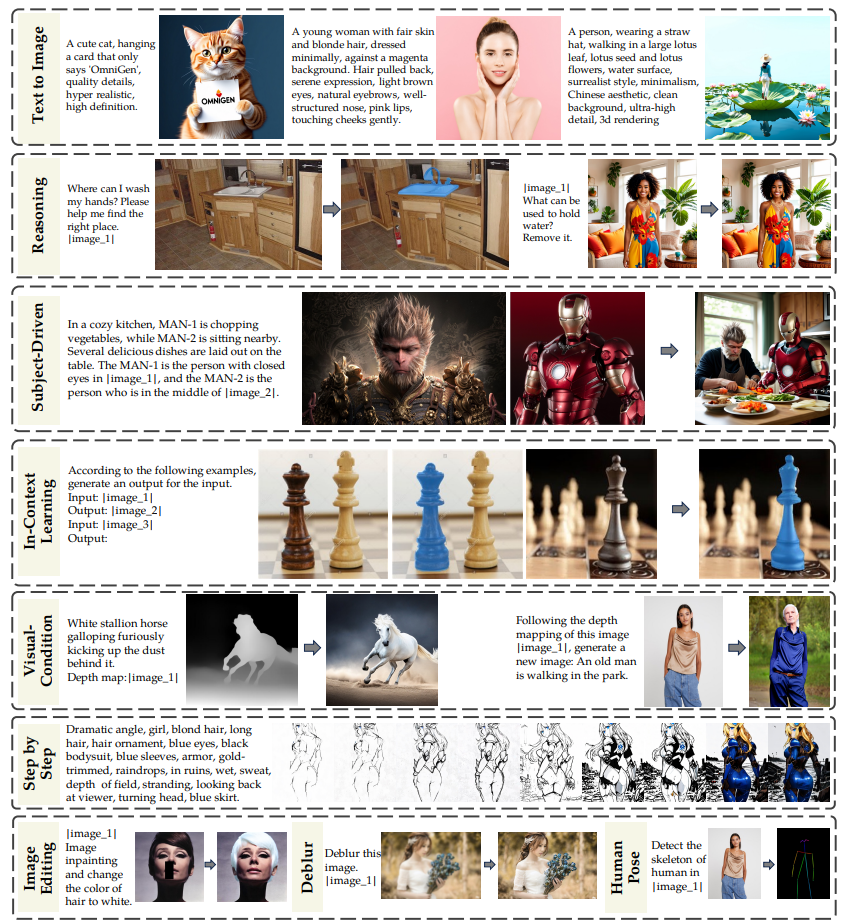
What can OmniGen do?
OmniGen is a unified image generation model that can be used to perform a variety of tasks including, but not limited to, text-to-image generation, subject-driven generation, identity preservation generation, image editing, and image conditioning.OmniGen does not require any additional plug-ins or manipulations, and it automatically recognizes features in the input image based on textual prompts (e.g., the desired object, body pose, depth mapping). ).
Below is a description of OmniGen's capabilities: Flexible control of image generation with OmniGen Demo
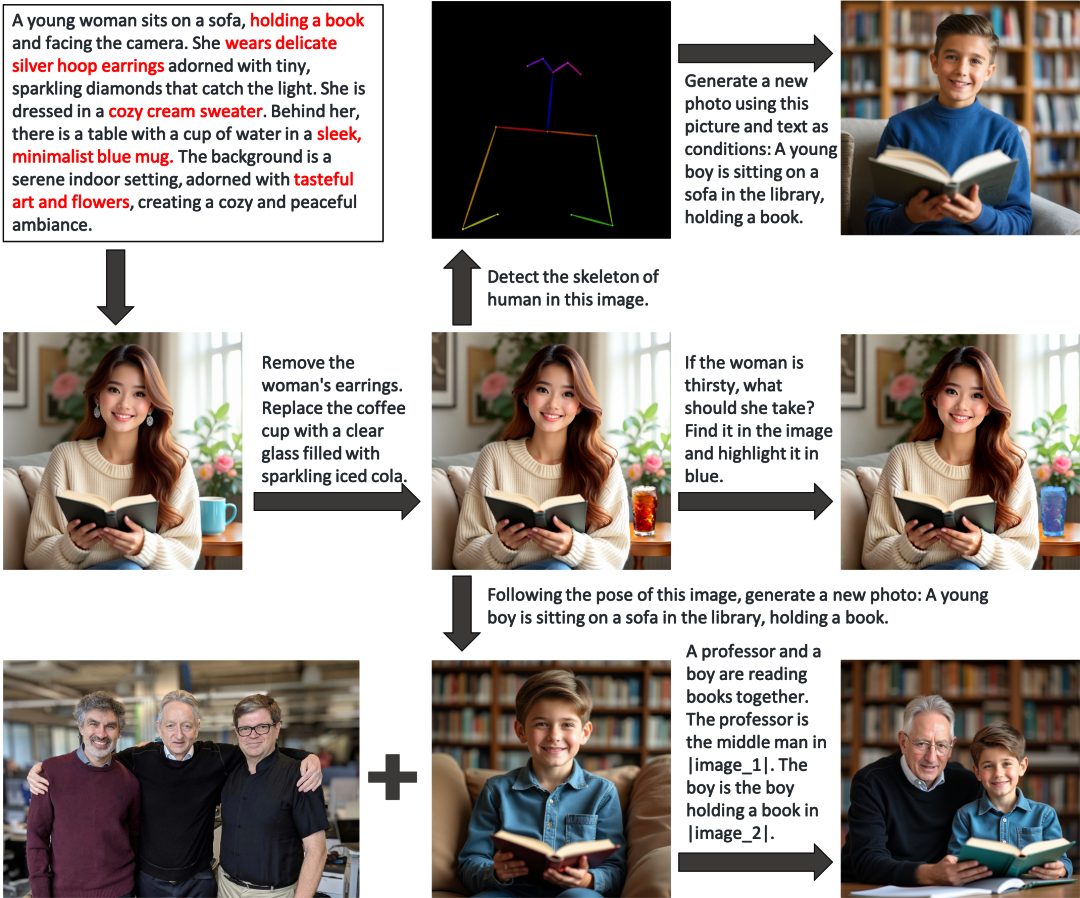
Quote Emoji Generation
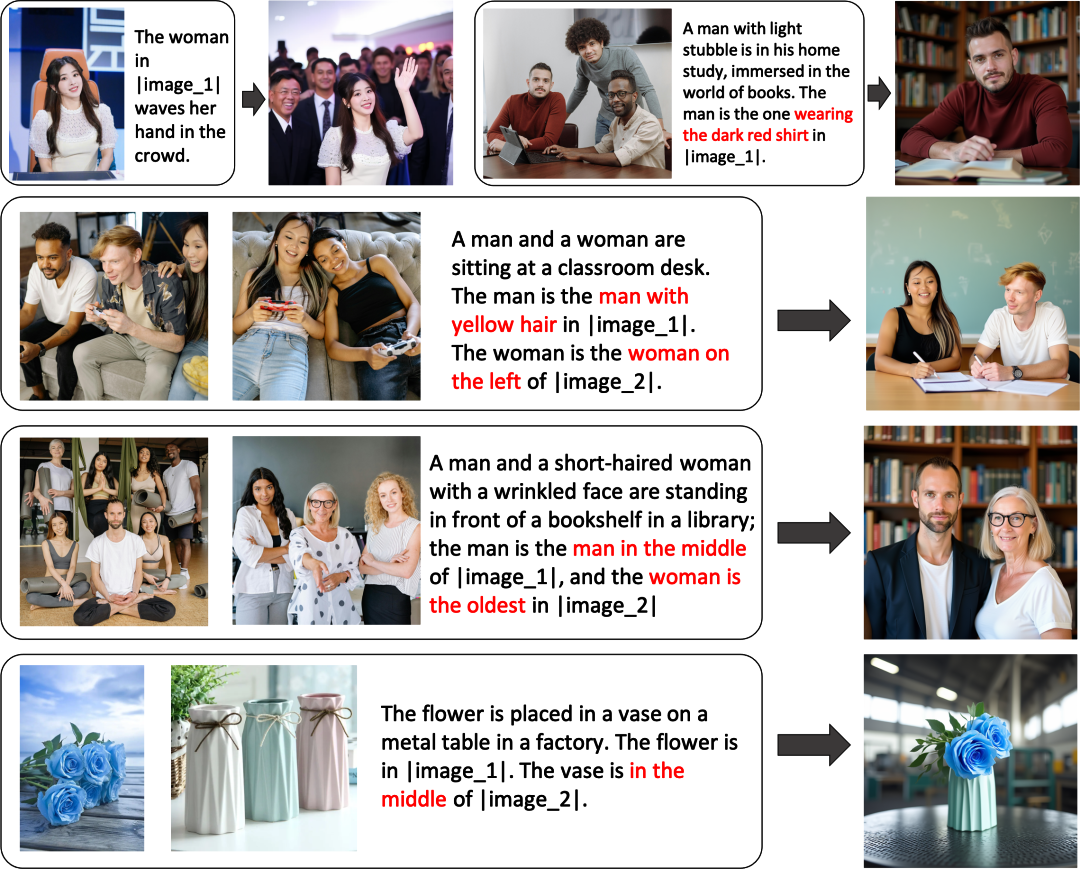
Multiple images can be entered and objects in the images can be referenced using simple, common language.OmniGen automatically recognizes the necessary objects in each image and generates a new image based on those objects. No additional operations such as image cropping or face detection are required.
methodologies
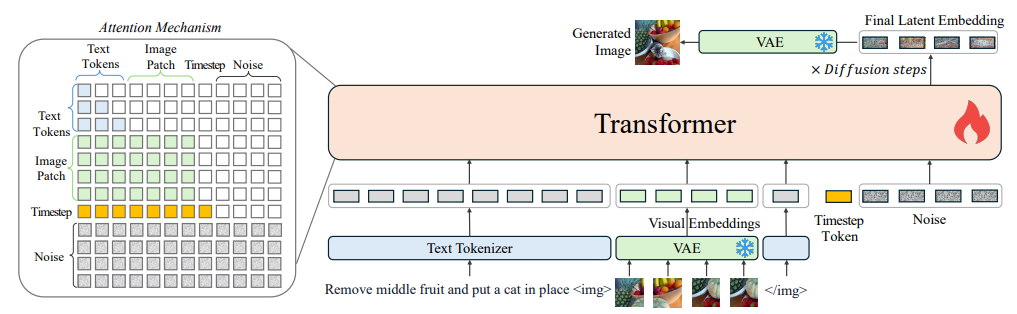
OmniGen's FrameworkThe text is tokenized and the input image is converted to an embedding by VAE. The text is labeled as tokens and the input images are converted to embeddings by VAE. OmniGen can accept free-form multimodal cues and generate images by rectification methods.
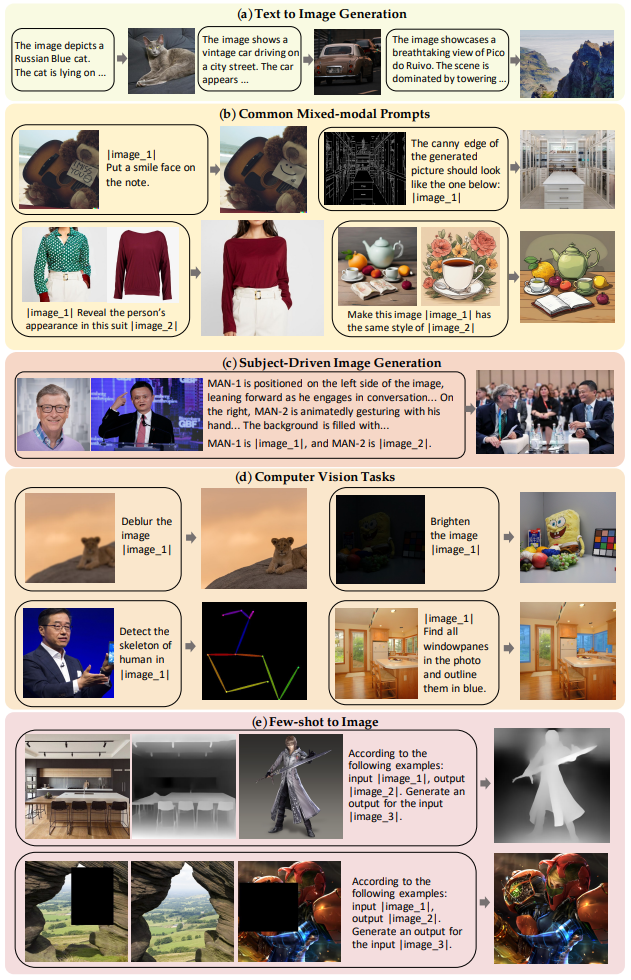
Example of OmniGen model training data. Inputs from all tasks are normalized to an arbitrarily interleaved image text sequence format, which is used as the model's cue. The placeholder |image_i| indicates the position of the ith image in the cue.
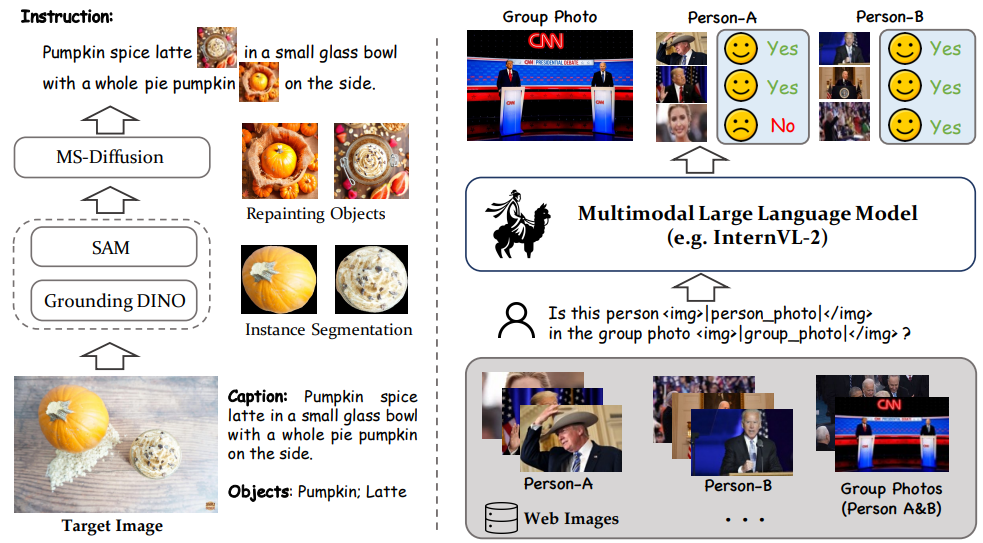
(a) Description of the construction process of the GRIT-Entity dataset. We use instance segmentation and redrawing methods to acquire a large amount of data. (b) Illustration of the cross-validation strategy used in constructing our web image dataset. For the ensemble of Person A and Person B, we extracted several images from the single photos of Person A and Person B and asked MLLM whether they appeared in the ensemble. The group photo is retained only if the "yes" ratio of both Person A and Person B reaches a specific threshold. The single images labeled as "yes" were then used to construct data pairs with the corresponding group images.
More results on display
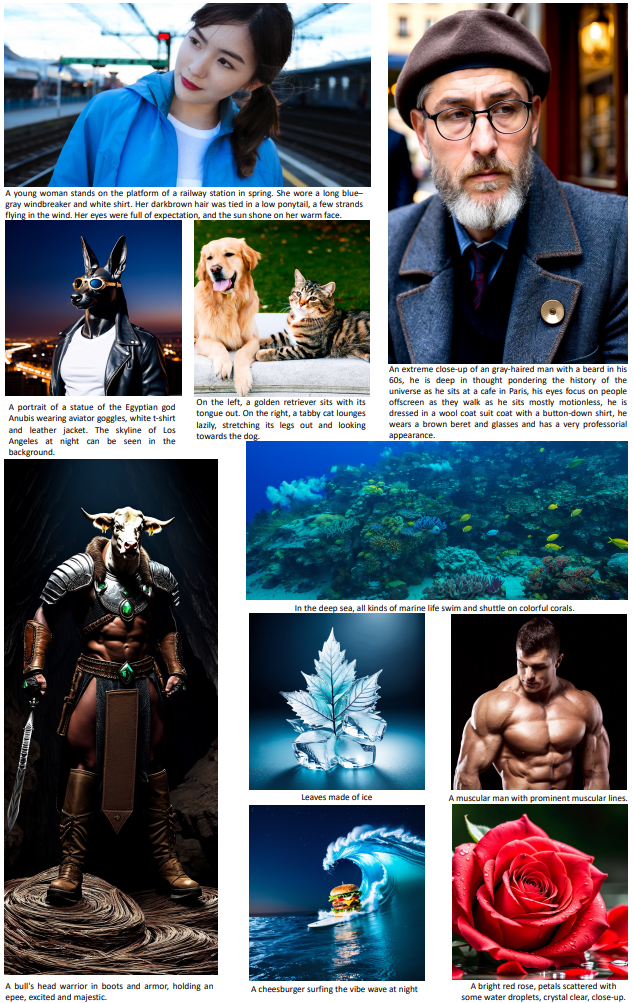
Results of text to image generation.
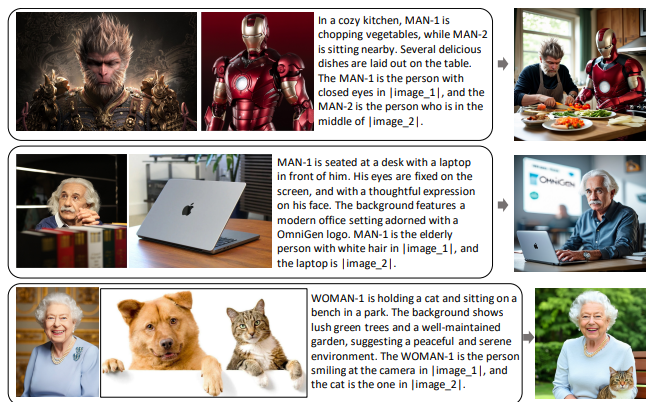
Theme-driven generation of resultsOmniGen can generate a new image based on the objects in the reference image. When the reference image contains multiple objects, OmniGen can automatically recognize the required objects based on text commands.
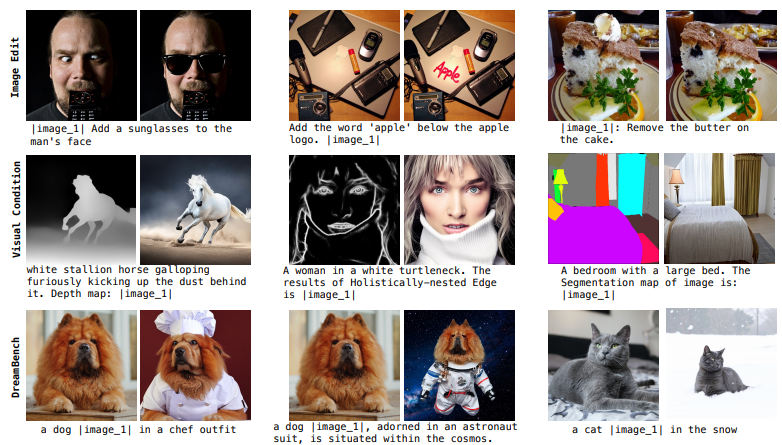
OmniGen results in different image generation tasks.
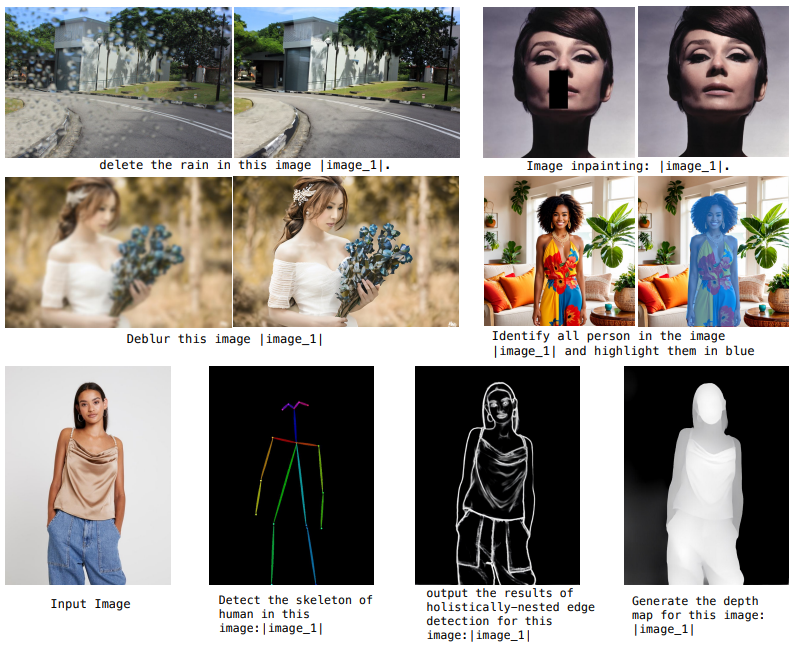
OmniGen results in a traditional variety of vision tasks.