


Today in 2026AI VideoThe tool is no longer the toy that simply twists the picture。
BUT I FOUND OUT THAT 901 TP3T'S FRIENDS WERE STILL IN THE OLD THINKING OF 2024 WHEN THEY TRIED TO RESET THE GREAT AL。
A lot of people saw a great video。
AND THEN YOU THROW IT TO AI, AND YOU ASK IT, "WHAT IS THIS?" PLEASE GENERATE A VIDEO FOR ME. WHAT YOU GET IS OFTEN A PICTURE STYLE, BUT MOVING IS NOTHING LIKE THAT。
The virulent push-and-pull lens, the delicate light flow, all gone。
Why? Because from the very beginning, you considered the “outcome” as the “process”. Video is not an animation. Video is a continuous change in the parameters of “time” and “space”。
IF YOU ONLY GIVE AI A SCREENSHOT, IT'S LIKE SHOWING THE CHEF A PICTURE OF THE FOOD, BUT YOU EXPECT HIM TO RETURN THE FIRE AND THE FIRE FROM COOKING -- IT'S NOT LOGICAL. TODAY, I DON'T TEACH YOU THE ADJECTIVES OF FALSE HEADS。
WE NEED TO TALK ABOUT SOMETHING REAL: HOW TO USE THE "SPORTS LAWS" OF THE BACK-UP VIDEO FROM AI. WITH THESE THREE METHODS, YOU CAN GET BACK CONTROL OF THE VIDEO CREATION。
Chapter I: Inverse “generation process” rather than “image content”
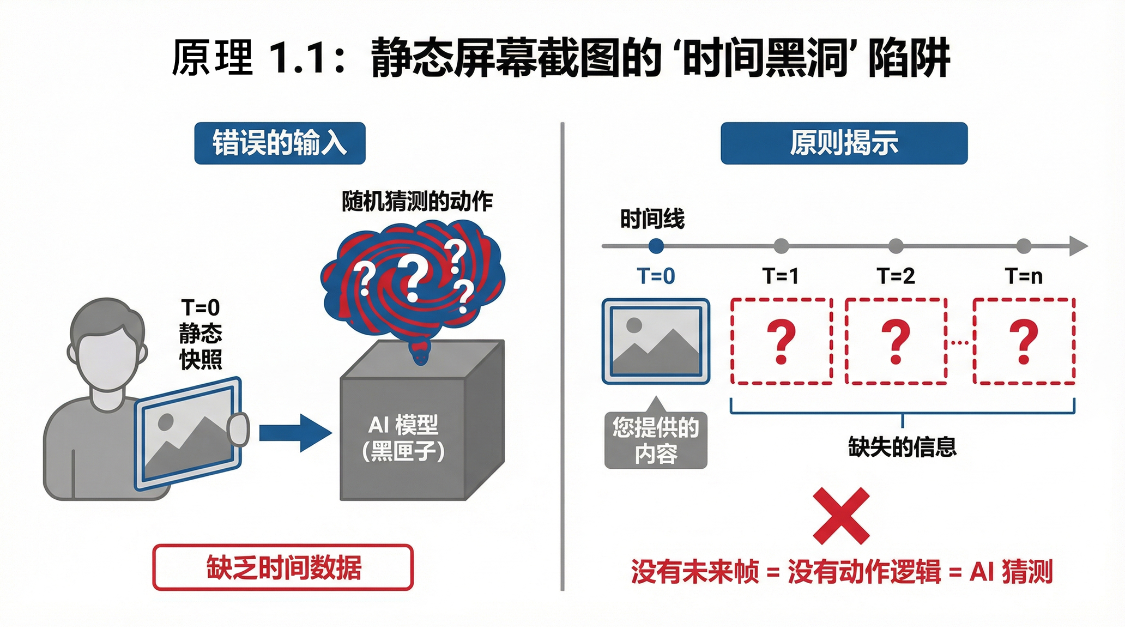
1.1 Static traps: Why fail to intercept
In the eyes of multi-modular models (e.g., the latest Gemini 3 or Chat GPT 5.2), a static cut-off is only a slice of a "T=0" moment. It does not contain T = 1, T = 2-minute information。
AND WHEN YOU THREW IT TO AI, YOU WERE ACTUALLY SAYING, "PUT ME A THING THAT LOOKS LIKE THIS." AND YOU SAID, "LET IT MOVE." BECAUSE THERE'S NO "MOTION LOGIC," AI STARTS GUESSING. IT COULD MAKE THE CLOUDS FLOAT TO THE LEFT OR THE TREES TO THE RIGHT. THAT'S WHY YOU CAN'T RECREATE THE ROOTS OF THE HYMN OF THE ORIGINAL VIDEO
You lost time dimension information。
1.2 Correct position: Three frames
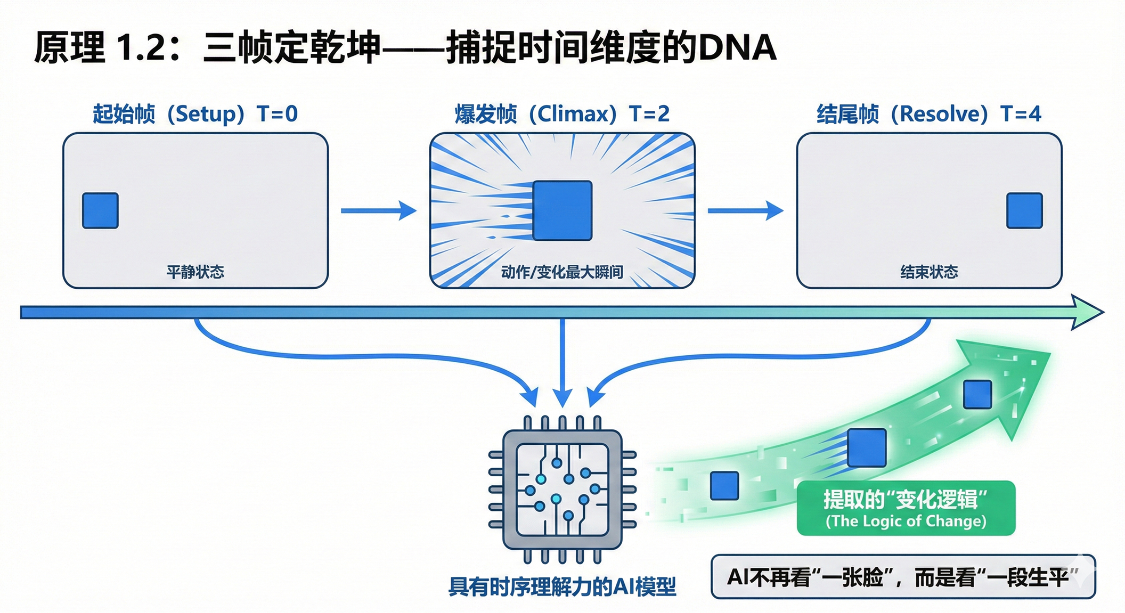
To reverse the logic of a video, we cannot just look at “one face”, we look at “a lifetime”。
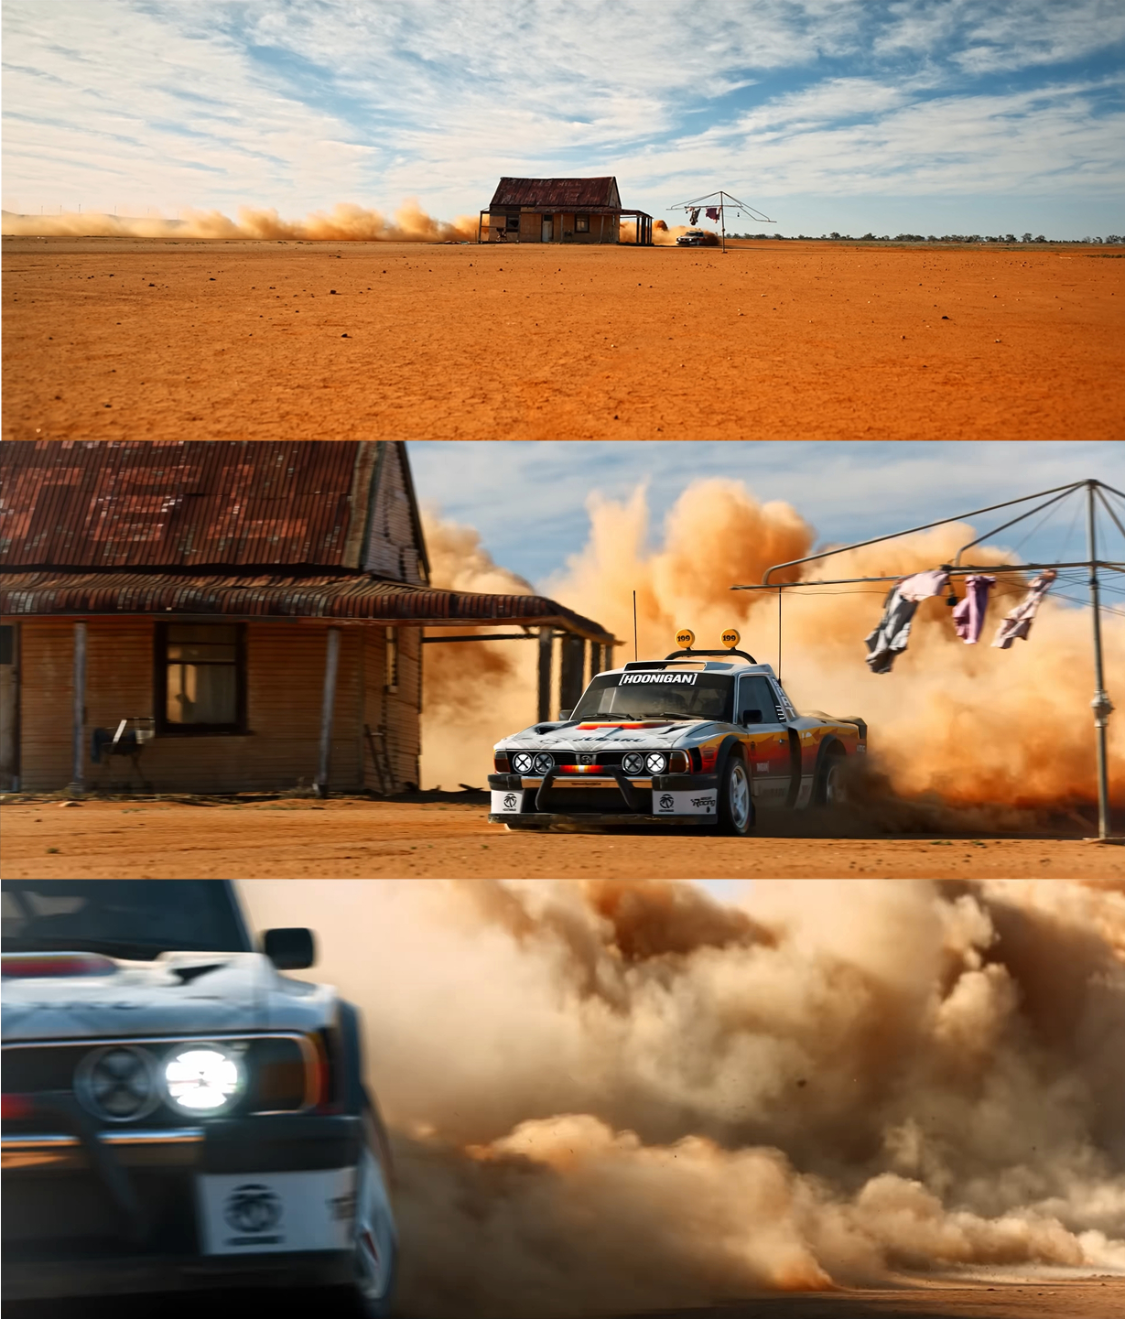
The correct approach is to intercept three key nodes from the original video:
Start frame (The Setup): The state of calm before action begins。
The Climax: The moment when the action was the largest and the light was the sharpest。
End frame (The Research): Image after action。
OPERATIONAL: DON'T ASK AI "WHAT'S THIS DRAWING?" YOU NEED TO FEED THESE THREE MAPS TO A VISUAL MODEL WITH A "TIME-SEQUENCE UNDERSTANDING" AND THEN ENTER SUCH A COMMAND:
“Analysis of the changing logic of the three maps. Please tell me, from figure 1 to figure 2 and then to figure 3, what has happened to the physical shift of the main subject in the picture? Where's the light coming from? Please describe this "process of change" rather than the picture itself."
At this point, AI no longer extracts “a girl in a red dress”, but “a red block accelerates movement from the lower left to the upper right in two seconds, with changes in the view from f/2.8 to f/11”. This is the DNA of the video。
The following figure provides a reference:
Enter pictures and hints in Gemini
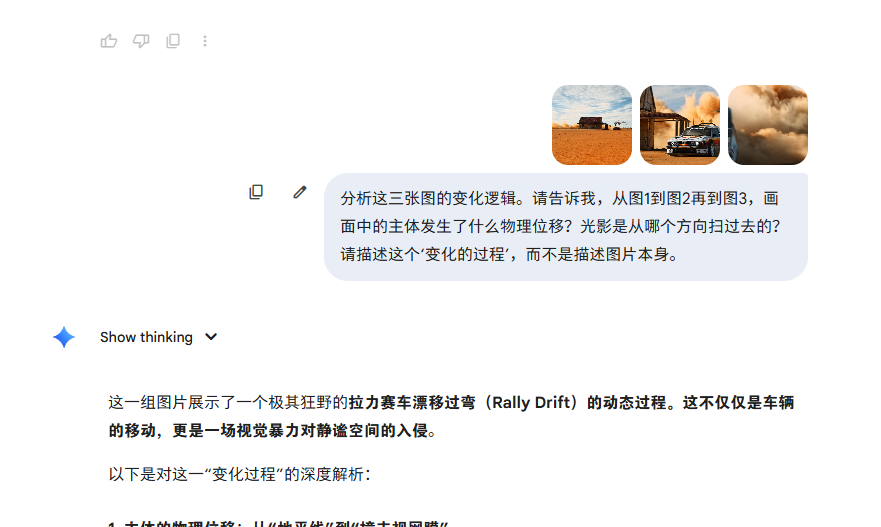
“An already silent desert space is torn apart by violence from a high-speed metallic object. With devastating kinetic energy, the subject bites the camera from the point of vision from the point of vision to the point of death, squeezes through the security space of the image through intense horizontal drift, and eventually completely submerges the sight of the observer with sky-spreading dust and close mechanical details.”
Chapter 2: Counter-directive with "Camera Motion Structures"
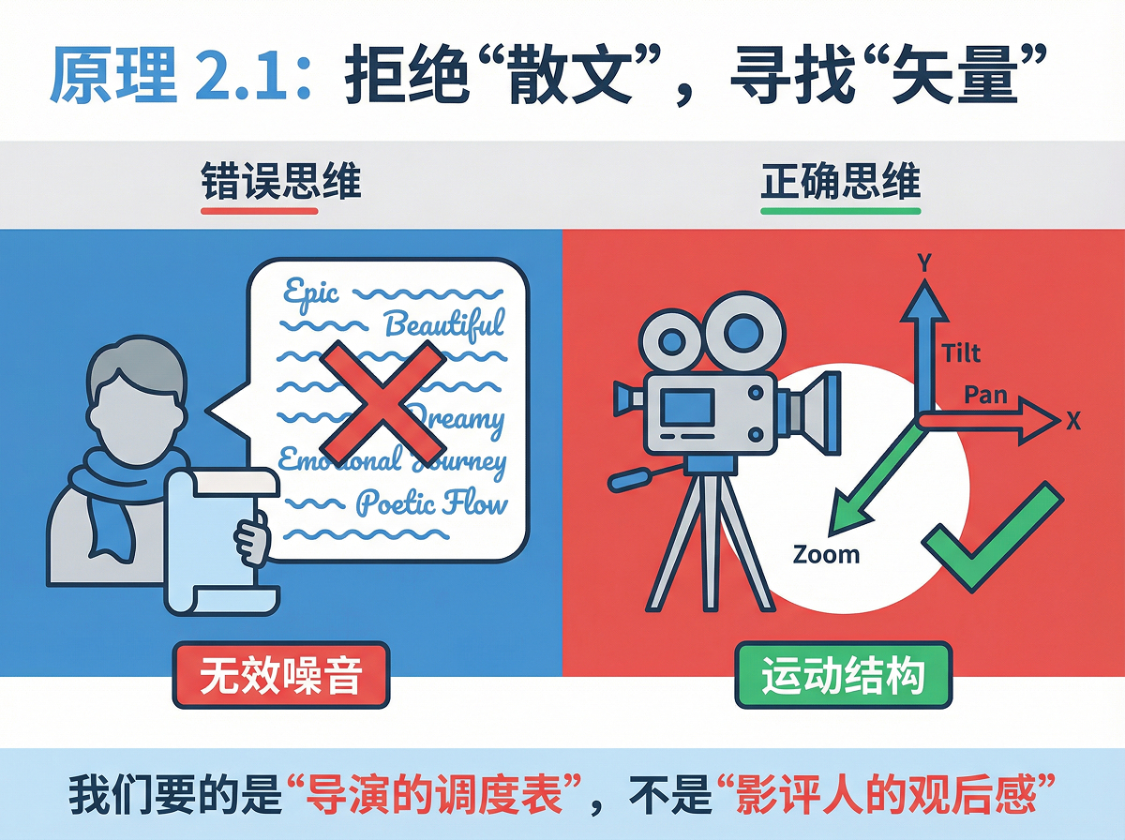
2.1 DON'T LET AI WRITE A ESSAY
A LOT OF ROOKIES LIKE TO ASK AI, "WHAT'S THIS VIDEO USING?" AI USUALLY RESPONDS TO YOUR BEAUTIFUL ESSAY: "A GREAT SENSE OF EPICNESS, THE SHADOW OF LIGHT, THE ATMOSPHERE OF HOPE..."
Stop! Stop. These words may be useful in 2024, but in 2026 they are not valid noises for video models that seek precision control。
The nature of the video is the relative motion of the camera and the object. Inversely, we're going to be a “routing sheet” for the director's perspective, not a “visional feeling” for the critic's perspective。
2.2 Search for "move vectors"
WE'RE GOING TO LEARN TO ASK QUESTIONS WITH “SCIENTIFIC STUDENTS”. WE NEED TO INDUCE AI TO OUTPUT VECTOR INFORMATION。
Wrong question:
"This video feels amazing. How did it go?"
Correct question:
"Ignoring the image of beauty. Please focus on camera path。
Is this a push shot or Zoom
HOW DID THE CAMERA'S PHYSICAL COORDINATES (X, Y, Z) SHIFT
Does the visual malformation at the edge of the image increase over time? (to judge the extent of the wide angle)”
Why would you do that? Because the current video generation model already supports more precise parameters control。
In the case of “push lens”, the background changes (Paralax)。
In the case of " focal " , the background changes only in size and not in vision. If AI recognizes this, you can get a key parameter: –camera_motion zoom_in or –camera_motion dolly_forward. The difference between this word is the difference between “large sense” and “pPT animation”。
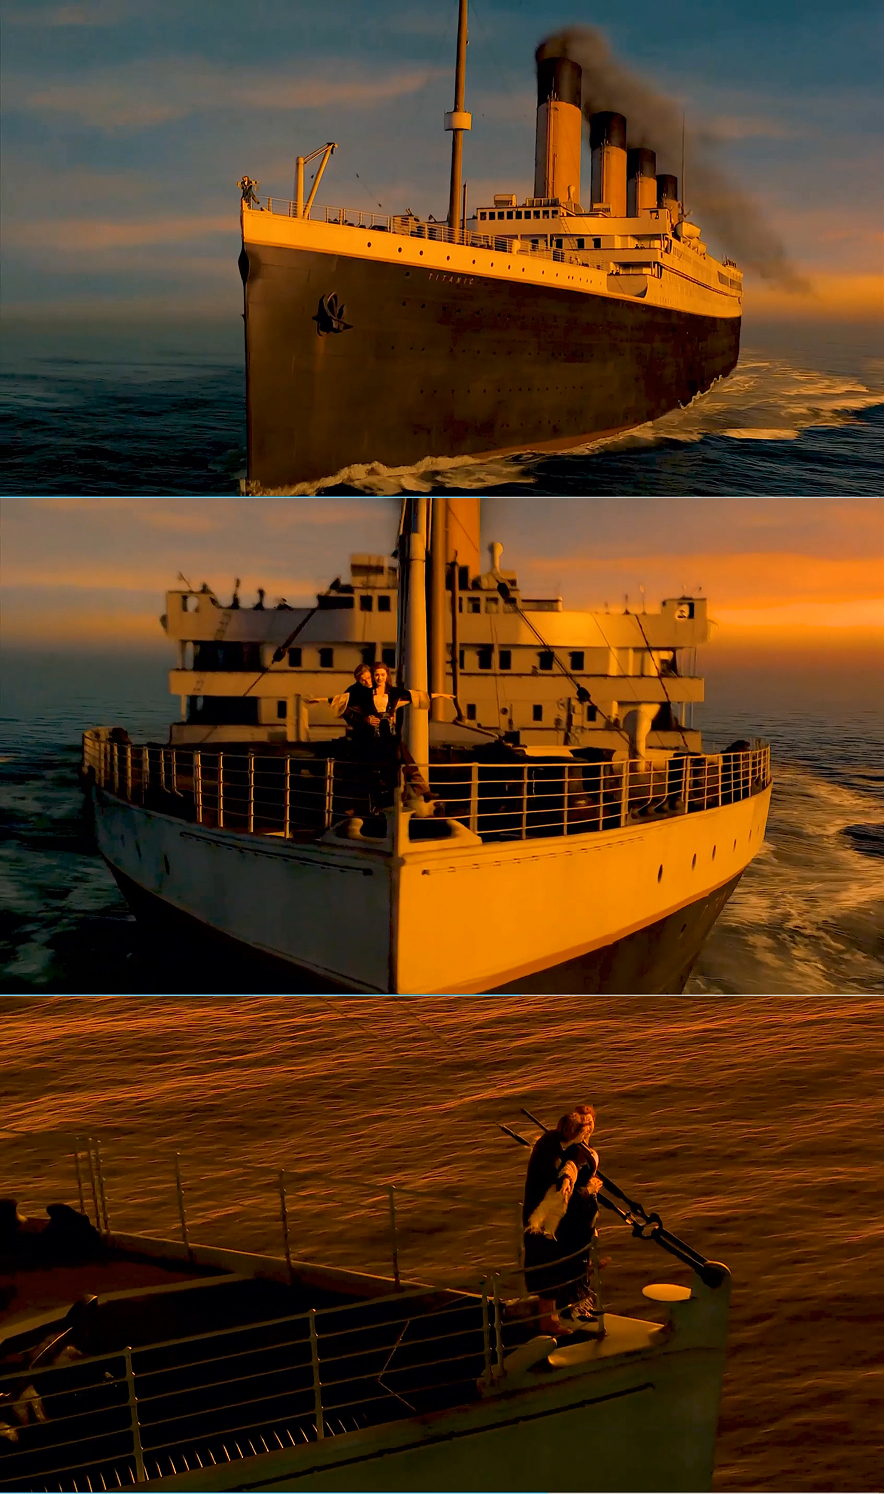
Example:
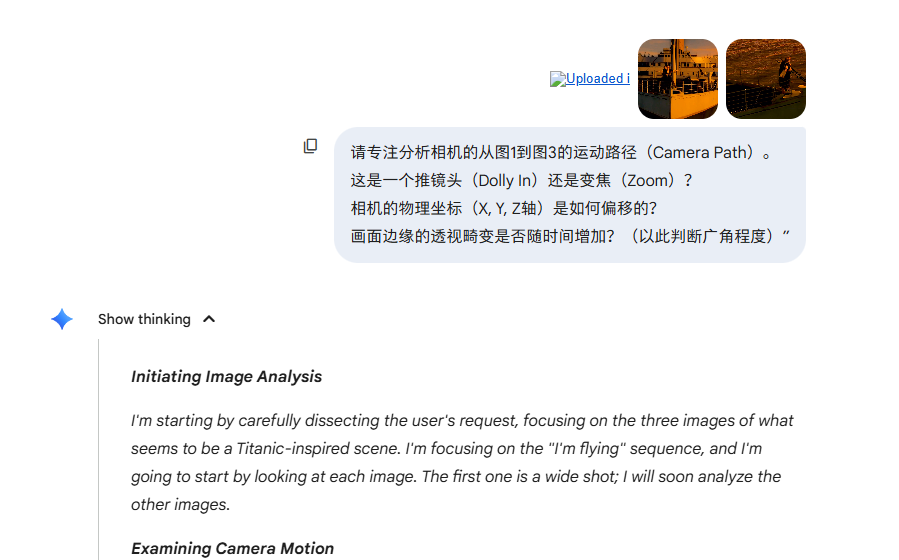
"Cinematic Drone shot, establishing the ship's bow, camera breaks a shiping motion, dolly in and crane up, translation from highness and close-up, dynamic prosperity change, side of the ocean
Chapter III: Imaging expression instructions — from “wish” to “programming”
3.1 Arts of Translators
This is the most critical step and the watershed between “white” and “experts”。
THE EASIEST MISTAKE FOR A ROOKIE IS TO COPY A LONG SENTENCE FROM AI ANALYSIS. FOR EXAMPLE, THE AI ANALYSIS SAYS: "THE LENS IS LIKE A BIRD THAT PASSES THROUGH THE SEA WITH A FREE AND DANGEROUS BREATH..." YOU THROW THAT BACK INTO THE VIDEO AND THE MODEL PROBABLY DOESN'T UNDERSTAND
WE'RE GOING TO TRANSLATE AI'S “EMOTIONAL DESCRIPTION” MANUALLY INTO “PARAMETER INSTRUCTIONS”。
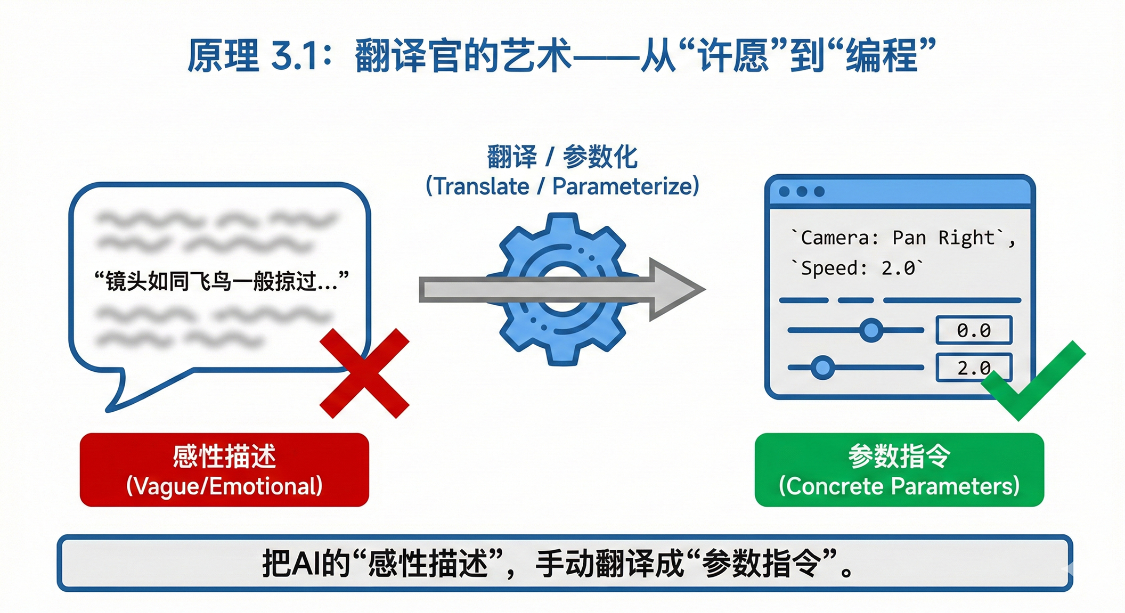
3.2 Elimination of used words and creation of an “implementation format”
In 2026, we followed the very simple principle of “action + parameters”。
See how to translate:
Sensitivity description: "Imaging, browsing the whole scene."
After translating:
Sensory description: "The image is very high and the movement very strong."
After translation: Motion Weight: 8 / Chaos: 20
Sensual description: "The sense of time passing, the rapid change of light."
Translation: Speed: 2.0 / Lighting: Time-lapse
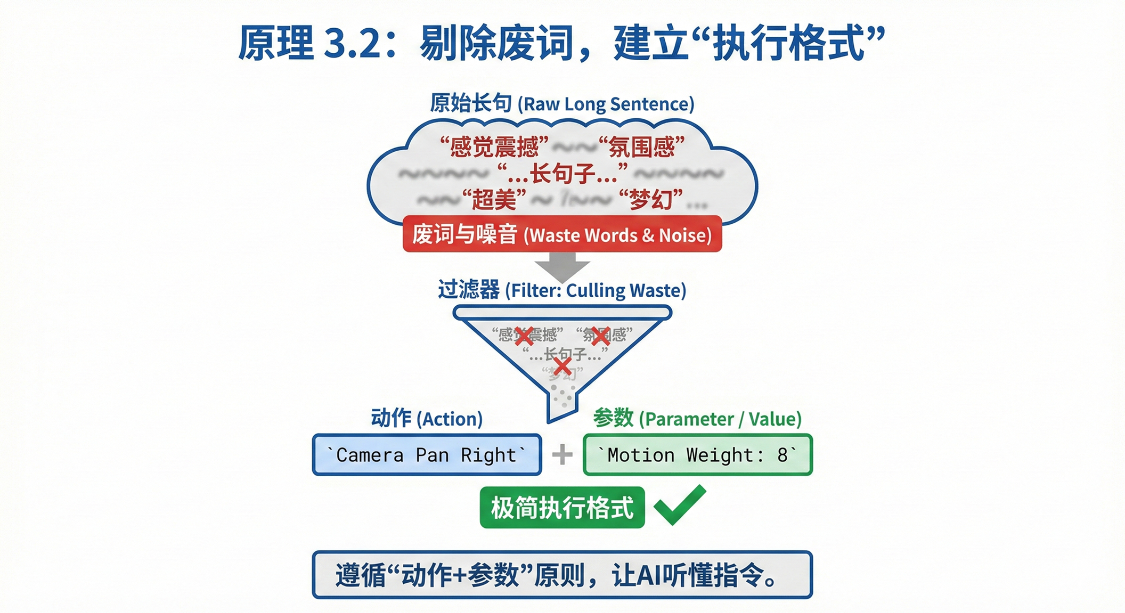
Let's say you want to reset a video called "Sebolpunk City Rapid Drift." And don't write, "A cool future city, flying fast, the lights are drawn." To write (based on inverse result):
Subject: Cyberpunk City Street, Neon Lights, Action: Hyper-lapse Forward.
ONLY WHEN YOU START USING VERBS AND NUMERICS CAN AI REALLY UNDERSTAND YOUR DIRECTOR'S INSTRUCTIONS。
CONCLUSION: DECONSTRUCTIVE GYMNASTICS, MASTER OF AI
In fact, the so-called "video inversion" is essentially deconstructing the laws of sports。
THE AI VIDEO GENERATION TECHNOLOGY HAS SO FAR CEASED TO BE THE "TICK CARD GAME." IT'S GETTING LIKE A SOPHISTICATED PHYSICAL SIMULATOR。
If you only focus on the color and the structure of the image, you'll always have to follow someone else。
But when you learn to strip off the image, to touch the logic of the parameters behind it -- to pull, to shift the focus, to shift the light -- you really have the freedom to create。
Remember, don't go "wish" a good video, go "build" it。