


On September 15th, the StepAudio3 series of models, including StepAudio3realtime, StepAudio3ASR, StepAudio3TTS, StepAudio3Gen and StepAudio3Music, were officially launched today, with multiple models ranked first on the Artificial Analysis list. The above five models are now onlineStep StarOpen platform。
Officially, the StepAudio 3 series addresses several core scenarios: real-class voice generation, full audio content generation, real-time voice interaction, complex scene voice understanding and music creation。
1AI THE FOLLOWING IS AN OFFICIAL DESCRIPTION OF THE ATTACHED MODEL:
StepAudio 3 Realtime: Not only "can interrupt" but more understand, think and act
Today, an increasing number of Realtime voice products have supported full-time, interrupted and low-delayed interaction. What really opens the gap is not just “can you listen and talk at the same time”, but whether the model can understand and judge when to answer in a conversation that continues to take place while doing its reasoning and task。
StepAudio 3 Realtime further enhances real-time interactive capacity around this goal, supporting live-time dialogue between original and working people。
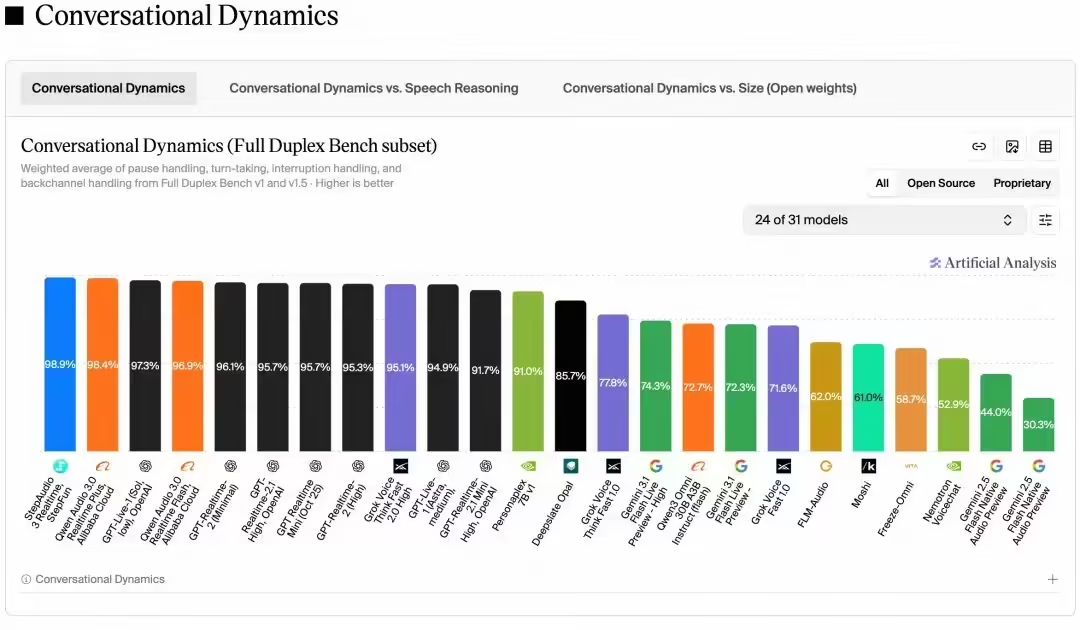
StepAudio 3 Realtime ranked first in the world with a combined score of 98.9%, demonstrating the leading real-time voice interaction. This means that models are not only able to "understand" and "answer" but are more able to judge the rhythm of dialogue like people in real communication -- knowing when to respond, when to wait, and how to deal with temporary disruptions and continuous feedback from users。
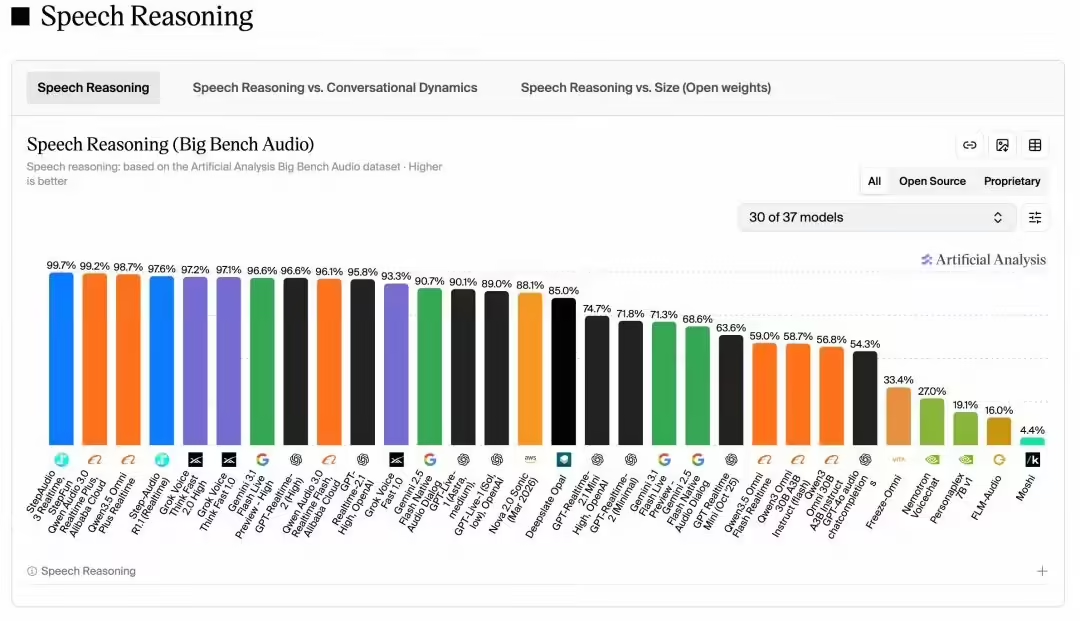
At the same time, StepAudio 3 Realtime ranks first on the global list with 99.7%'s voice reasoning accuracy. Speech Reasoning Focus Model's ability to directly understand audio and perform complex reasoning tasks is an in-house assessment of “native”Voice ModelOne of the most authoritative third-party benchmarks。
Models can also understand semantics, semantics, emotions, sub-linguistics and environmental sound, so that real-time interaction does not depend solely on textual content, but uses more complete audio information to understand user intent。
In the face of complex problems, StepAudio 3 Realtime supports a parallel between reasoning and voice generation and continues to organize and deepen follow-up answers while responding quickly。
More than that, Tool Call and the long mission can be performed in a walk without blocking the current voice session. Users can continue to communicate while the task is running, and when the results are completed they will naturally return to the current context。
This allows the Realtime voice model not only to "talk more naturally" but to hear, say, think, do in the same ongoing conversation。
StepAudio 3 ASR: From hearing to understanding
TRADITIONAL SPEECH RECOGNITION PRIMARILY ADDRESSES “WHAT IS HEARD”, BUT IN THE REAL WORLD, SPEECH OFTEN INCLUDES DIALECTS, ACCENTS, PROFESSIONAL TERMINOLOGY, SYNONYMS AND COMPLEX CONTEXTS. THE TRULY AVAILABLE ASR MODEL REQUIRES NOT ONLY AN ACCURATE TRANSLITERATION OF SOUND, BUT ALSO AN UNDERSTANDING OF WHAT IS EXPRESSED BY THE SPEAKER。
StepAudio 3 ASR combines high-precision speech recognition with context understanding, knowledge and reasoning of large language models, allowing voice recognition to move further from “identify sound” to “understand language”。
It supports the recognition of multiple scenarios, such as Chinese, English, dialects, Chinese and English, long audio and professional fields, which can be adapted to different linguistic contexts and expressions. At the same time, building on the knowledge understandings provided by the mega-linguistic model, StepAudio 3 ASR is able to identify more accurately complex elements such as names, place names, professional terminology, and enhance the recognition of professional expression in such areas as medicine, law, finance, automobiles, programming, etc。
Models can also handle complex inputs such as whispers, fast speeds, vague reading, singing and background music, allowing for more accurate recognition and use of voice in a real sound environment。
THIS MEANS THAT THE ASR MODEL IS NO LONGER JUST A VOICE-REPEATING TOOL, BUT IS ABLE TO UNDERSTAND, RETRIEVE AND USE EACH SEGMENT OF THE VOICE MORE ACCURATELY. THE MISSION WAS CARRIED OUT WITH PRECISION IN MINUTES OF MEETINGS, VIDEO SUBTITLES AND LIVE READING, INTELLIGENT PASSENGER SERVICE, CAR-BORNE INTERACTION, MEDICAL RECORDS, FINANCIAL SERVICES AND PROFESSIONAL CONTENT PRODUCTION。
StepAudio 3 ASR in the Artificial Analysis non-fluent speech recognition accuracy list, Wer (the word error rate) is only 1.7% and ranks first in the world。
StepAudio 3 TTS: More than just reading, more like real expression
IT CARRIES NOT ONLY TEXTUAL INFORMATION, BUT ALSO RICH EXPRESSIONS OF SPEECH, RHYTHM, PAUSE AND EMOTION. HOW TO GET THE VOICE GENERATED BY AI CLOSER TO REAL COMMUNICATION HAS BEEN AN IMPORTANT DIRECTION FOR VOICE GENERATION MODELS。
StepAudio 3 TTS is a real-life voice generation model for real-time interactive scenes that aims to move AI voice from "accurate sound" to "natural expression."。
Models are highly consistent with human natural speech patterns in terms of the sound base, tone level, rhythm and air-suspension, not only to generate textic speech, but also to restore the sub-linguistic expression in real communication, such as laughter, hesitation, stasis, repetition, re-proximation, etc., and to bring synthetic speech closer to the real person。
At the same time, StepAudio 3 TTS is able to understand the expression of intent in the context of semantic content, and to adjust emotions and tone to make voice expression more relevant to the context. In terms of real-time interaction, the model is based on a flow-based generation structure that produces and plays synchronized and meets real-time voice applications。
StepAudio 3 Gen: human voice, sound, environment, music, one generation
Traditional audio content production is often a long link. Roles, environment sounds, sound effects and background music need to be produced separately and then edited, aligned and mixed to form the final work。
StepAudio 3 Gen tried to integrate these previously dispersed links into a model。
It is based on natural language descriptions and reference audio, and produces a unified human voice, sound, environmental sound and background music. Users need only describe roles, scenes and dramas and do not need additional training for specific roles or scenarios. You can directly generate audio content with full sound levels。
More importantly, these voices are not simply superimposed。
StepAudio 3 Gen supports the fine control of the sound, speech, tone, emotions, dialects, and sub-linguistic features such as laughter, breathing, pause, etc. of multiple characters, and can further specify the time and sequence of white, sound, environmental and background music。
This means that the model is not only " generating sound " , but is also beginning to be involved in the sound design and sequencing of the entire content。
For film, animation, games, radio dramas, audio books and short video creators, the sound production process that would have required material collection, multi-tool collaboration and extensive later processing had the opportunity to be condensed into a generation and continuous iterative process。
StepAudio 3 Music: more than just generation, more creative
Music generation models have become more and more good at producing a song in one sentence. But real music is not supposed to be like "simplified cards." The creator may already have a song, a song, a melody, a musical score, or a Demo, hoping AI would then go down to compose, adapt and make。
StepAudio 3 Music therefore supports not only generation from zero, but also multi-wheel interactive creation based on ABC spectrometry control。
MODELS SUPPORT A VARIETY OF FUNCTIONS, SUCH AS SONG CREATION, SINGING CHORUS, SONG RECITATION, ETC. USERS CAN PROVIDE A VARIETY OF INPUTS, SUCH AS LYRICS, SINGING, REFERENCE SONGS, ABC SPECTROMETRY, SO THAT THE MODEL CONTINUES TO BE GENERATED AND REFINED AROUND EXISTING CREATIONS。
At the same time, users can directly control the wind, the human voice, the melody, the rhythm, the instrument, the mood, the paragraph and the quality of the text in the natural language。
The model also models the song structure of the main song, side songs, bridges, inter-syncs, as well as the melody development, energy change and singing expression across the paragraphs, so that the goal is not just “a good piece of music”, but a complete and coherent piece of structure。
In particular, in a sing-and-song scene, the user needs only a sing, and the model understands the melody, rhythm and emotion, and further complements the sound, rhythm, instrument and complete composer。
A warm, sweet City Pop male song, a little jazz and a little rocky, romantic。
This allows the music megamodels to enter more deeply into the real music production process than just a "one-key song generation" tool。