


The news of September 18thAliQuestionsToday, the new generation is officially on the lineholomodal model Qwen3.8-Omni-Flash is already available on the Chira-Ai platform. The model allows for the simultaneous processing of text, images, audio and video input to support the 1M context。
Full-state models refer to multiple input forms that can be processed simultaneously, such as text, images, audio, video, etc. Officially, while maintaining the capability of the same size text model, the total modulation capacity was significantly higher than that of the previous generation。
Qwen3.8-Omni-Flash increased the average score of the previous generation Qwen3.5-Omni-Plus by more than 26% in the cumulative 30 assessments. In audio-visual Agent, Coding and long-range missions, WildClawBench-MM up 36.5 points, AgenicVBench up 22.3 points and UniClawBench down 69.6 points。
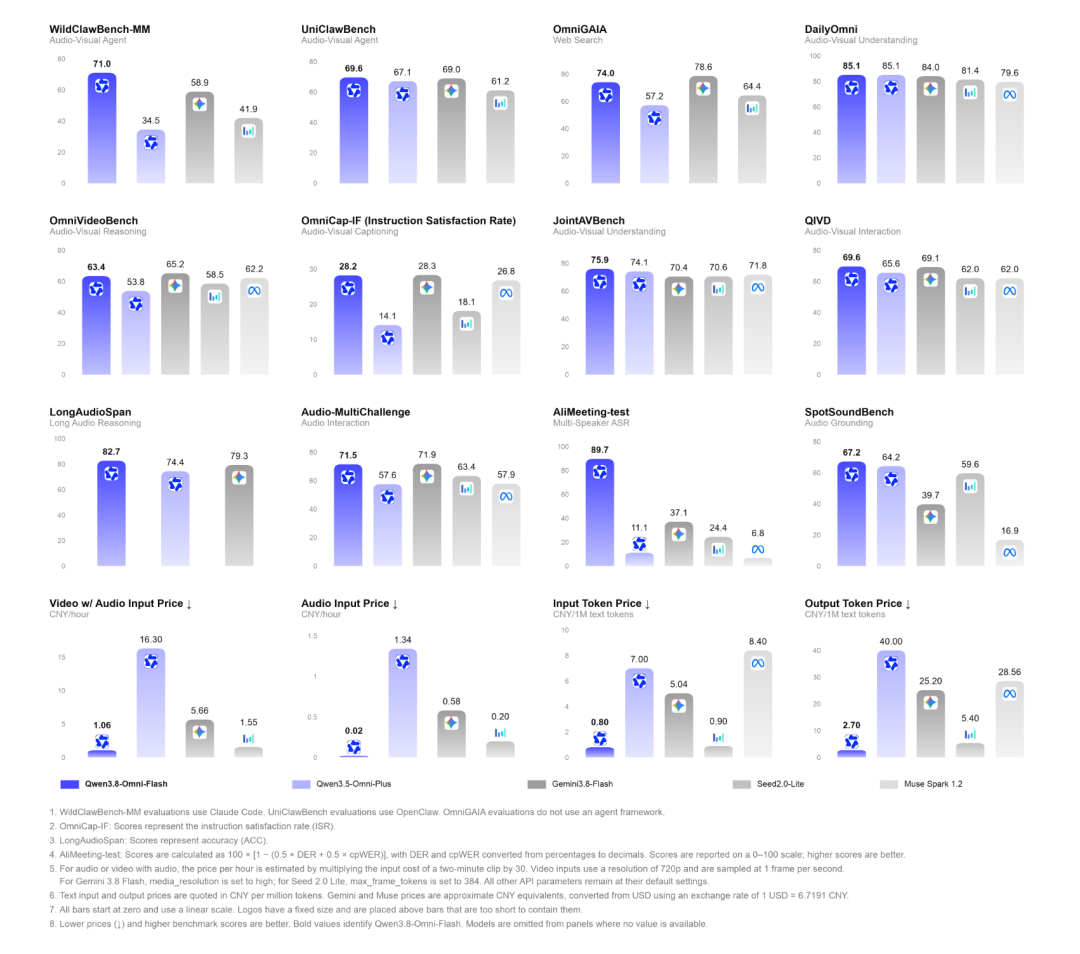
In terms of basic capacity, LongAudioSpan is up 8.3 points, OmniVideo Bench is up 9.6 points and OmniCap-IF is up 8.5.4.1 points. AliMeeting's DER / cpWER decreased from 88.11/89.61 to 3.35/17.18。
Officially, its audio-visual capacity is close to Gemini 3.8 Flash and its overall audio capacity exceeds Gemini 3.8 Flash. API has an hourly reduction in audio input prices of more than 981 TP3T and an hourly video input price of more than 931 TP3T。
Qwen-MM-Plugins was officially expanded and the source Qwen-Live Harness was opened to support long-sound videos. The former is oriented towards demand-based awareness of long-distance workflows, tool call-up and implementation, while the latter is oriented towards real-time, continuous, whole-state interaction。
In the area of long-sound video understanding, the model supports needs-based descriptions, Agentic Active Forensics, Conference Mission Advances and video depth studies. Controlled video Caption specifies the description object, time range, information particle size and output format。
In the Agentic long-sound video understanding, the OmniVideoBench accuracy rate increased from 63.4 to 67.8, and Token consumption decreased from 145,736 to 79,117, a decrease of approximately 45.7%。
In the conference scene, the model supports a maximum of one hour of audio and video input, which allows for the completion of voice-to-mouth, content transfer and identity, generation of minutes and to-dos, and analysis of project risks. Combined with tools, you can also send mail, sort jobs or code。
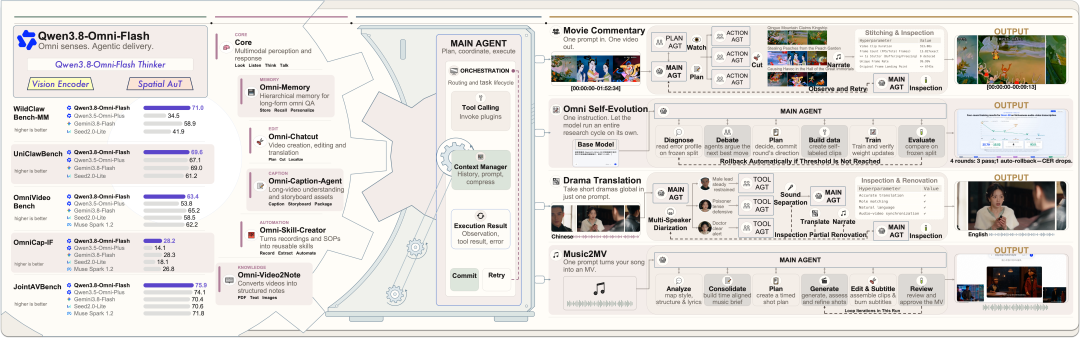
In the area of audio and video production, Music2MV understands song structure, rhythm and emotions, and outputs time-stamped lyrics. Short play translations allow for role recognition, oral translation, role-cloning, remixing of tracks and partial quality checks。
In the long-film narrative, users provide video and a sentence demand, and Agent completes a full-modular understanding, key scenario extraction, narrative planning, choreography, clipping and tablet quality。
In the model optimization experiment, Qwen3.8-Omni-Flash tried to upgrade Qwen2.5-Omni-3B's Sichuanphone recognition capability within 12 hours. It selects its own assessment set and constructs 3413 training data from the 4-wheel experiment, with the character error rate dropping from 25,79% to 15,30%, a relative decrease of about 40,7%。
With regard to the compression of information, Qwen-MM-Plugins Open Source Video2Note can generate several hours of video content for the text's PDF notes. Omni Skill Creator can extract standard operating procedures from the operational demonstration and convert them into reusable Agent Skill。
A real-time version of Qwen3.8-Omni-Flash-Realtime completes perception and response at the same time as audio and video stream input and calls the tool in real-time context. IT House noted that it also supported real-time language companionship, joint modelling of pronunciation and semantics, and understanding of non-standard expressions affected by accents。
Officially, the real-time version is the first full-modular model to support “hearing-resolution”, integrating spatial sound and visual information and judging the direction and distance of the sound. It can also inject identity creation, expression style, business knowledge and interactive rules through Skill。
In the Agenic Omni Unioning assessment, the official performance of Qwen 3.8-Omni-Flash with Gemini 3.8 Flash and Agent with access to Qwen Code was compared to OmniVideo Bench, Video-MME-v2 and LVOmni Bench。
The results of the Qwen3.8-Omni-Flash-Realtime API's actual throughput and delayed performance information and integrity testing in different input scenarios are also published。