



We often see various parameters such as 10 billion, 50 billion, 200 billion, etc. added to the end or prefix of the introduction of large language and diffusion models. You may wonder what this means—it could be related to the size, memory limit, or usage permission, but it is not explicitly defined as such.
InChatGPTOn the first anniversary of its release, the AIGC Open Community will introduce the meaning of this parameter in an easy-to-understand way.OpenAIThe detailed parameters of GPT-4 have not been announced, so we will use the 1750 billion of GPT-3 as an example.
On May 28, 2020, OpenAI released a paper titled 'Language Models are Few-Shot Learners', which introduced GPT-3 and gave a detailed explanation of the parameters, architecture, and functions of the model.
Paper address: https://arxiv.org/abs/2005.14165
Meaning of parameters in large models
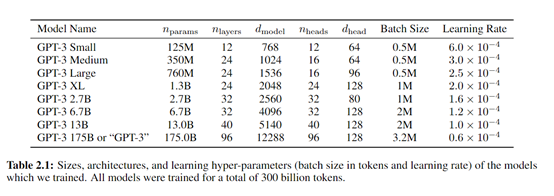
According to the paper, the parameters of GPT-3 reached 175 billion, while GPT-2 only had 1.5 billion, an increase of more than 100 times.
The substantial increase in parameters is mainly reflected in the comprehensive enhancement of storage, learning, memory, understanding, and generation capabilities., which is why ChatGPT can do anything.
Therefore, parameters in large models usually refer to the numerical values used to store knowledge and learning capabilities in the model.These parameters can be thought of as the model’s “memory cells”, which determine how the model processes input data, makes predictions, and generates text, etc..
In a neural network model, these parameters are mainly weights and biases, which are optimized through continuous iterations during the training process. Weights control the interaction between input data, while biases are added to the final calculation to adjust the output value.
Weights are the core parameters in neural networks, and they represent the strength or importance of the relationship between input features and output.Each connection between network layers has a weight that determines how much influence the input of one node (neuron) has on the calculation of the output of the next layer..
Biases are another type of network parameter that are usually added to the output of each node to introduce an offset, allowing the activation function to have a better dynamic range around zero, thereby improving and adjusting the node's activation level.
In simple terms,GPT-3 can be thought of as a super large office assistantsuperproductiveAn assistant in a large office with 175 billion drawers (parameters), each of which contains some specific information, including words, phrases, grammar rules, and punctuation principles, etc..
When you ask ChatGPT a question, for example, help me generate a shoe marketing copy for a social platform, the GPT-3 assistant will extract information from the drawers containing marketing, copywriting, and shoes, etc., and then re-generate it according to your text requirements.
During the pre-training process,GPT-3 will read large amounts of text like humans to learn various languages and narrative structures as part of its pre-training process..
Whenever it reads new information or tries to generate new text, it opens these drawers and looks inside to try to find the best information to answer questions or generate coherent text.bestto answer questions or generate text with coherence
When GPT-3 does not perform well enough on certain tasks, it will adjust the information in the drawer (update parameters) as needed so that it can do better next time.
So, each parameter is a small decision point for the model on a specific task. Larger parameters mean that the model has more decision-making power and finer control, and can capture more complex patterns and details in language.
The higher the model parameters, the better the performance will be.
From the perspective of performance, for large language models such as ChatGPT, a large number of parameters usually means that the model has stronger learning, understanding, generation, and control capabilities.
However, as the number of parameters increases, problems such as high computing power costs, diminishing marginal returns, and overfitting will arise. This is especially difficult for small and medium-sized enterprises and individual developers who do not have development capabilities and computing power resources.
Higher computing power consumption: The larger the parameters, the more computing resources are consumed. This means that training larger models requires more time and more expensive hardware resources.The larger the parameters, the more computing resources are consumed. This means that training larger models requires more time and more expensive hardware resources.
Diminishing marginal returns:As the model size grows, the performance gain from each additional parameter decreases. Sometimes, increasing the number of parameters does not bring significant performance improvements and instead incurs more operational cost burdens.
Difficulty in optimization:When the number of parameters of a model is extremely large, it may encounter the "curse of dimensionality", that is, the model becomes so complex that it is difficult to find an optimized solution, or even performance degradation occurs in some areas. This is very obvious in OpenAI's GPT-4 model.
Inference Delay:Models with larger parameters usually respond slower when performing inference because they need more time to find a better generation path. Compared with GPT-3, GPT-4 also has this problem.
Therefore, if you are a small or medium-sized enterprise that deploys large models locally, you can choose models with small parameters and strong performance that are built with high-quality training data, such as the open source large language model Llama2 released by Meta.
If you don't have local resources and hope to use it in the cloud, you can use OpenAI's API.latestModel GPT-4Turbo, Baidu's Wenxin Big Model, or Microsoft's Azure OpenAI services.