


If you've tried it beforeAI VideoYou must have had a difficult and fatal problem..
It is difficult to maintain the absolute consistency of products during video generation。
IN ALL THE MAJOR SOCIAL MEDIA, MANY OF THE VIDEOS PRODUCED BY AI ARE AT FIRST SIGHT AMAZING, BUT AS LONG AS YOU ZOOM IN, OR FRAME-TO-SPECIFY, YOU FIND AN AWKWARD FACT: THE PRODUCT IN THE VIDEO, AND EACH FRAME IS IN A SUBTLE SHAPE. FLOWER STRIPES ARE SWIMMING, EDGES ARE MELTING, AND EVEN THE LIGHT OF THE MATERIAL IS JUMPING。
Today's in-depth course will take you from the bottom of the line to solve this problem. It's not complicated, but it's going to take you to change your traditional AI thinking. This workstream is based mainly on Nano Banana Pro and Clint AI/ Dreamseedance 2.0。
THE OLD RULES, THE CORE PRINCIPLES, AND THE PRACTICAL STEPS I'VE PUT TOGETHER, WHETHER YOU'RE A PERSONAL CREATOR OR A HARD-ON BUSINESS TEAM, WILL GET YOUR A.I. VIDEO UP TO VERY HIGH INDUSTRY STANDARDS。
CHAPTER I: WHY CAN'T AI BE CONSISTENT WITH THE ESSENCE
BEFORE WE CAN SOLVE THE PROBLEM, WE MUST CLEAR A KEY POINT: THE VISUAL LOGIC OF AI IS COMPLETELY DIFFERENT FROM THAT OF HUMANITY。
WHEN YOU LOOK AT A GLASS ON THE SCREEN, YOUR BRAIN IS ABLE TO CONSTRUCT THE THREE-DIMENSIONAL CONCEPT OF THE GLASS; BUT IT DOESN'T KNOW WHAT THE "SAME PRODUCT" IS FOR THE CURRENT AI VIDEO GENERATION BIG MODEL. IT'S BASED ON THE HINT YOU ENTEREDPromptOr a reference map to pixel-level “guess” what the next frame looks like。
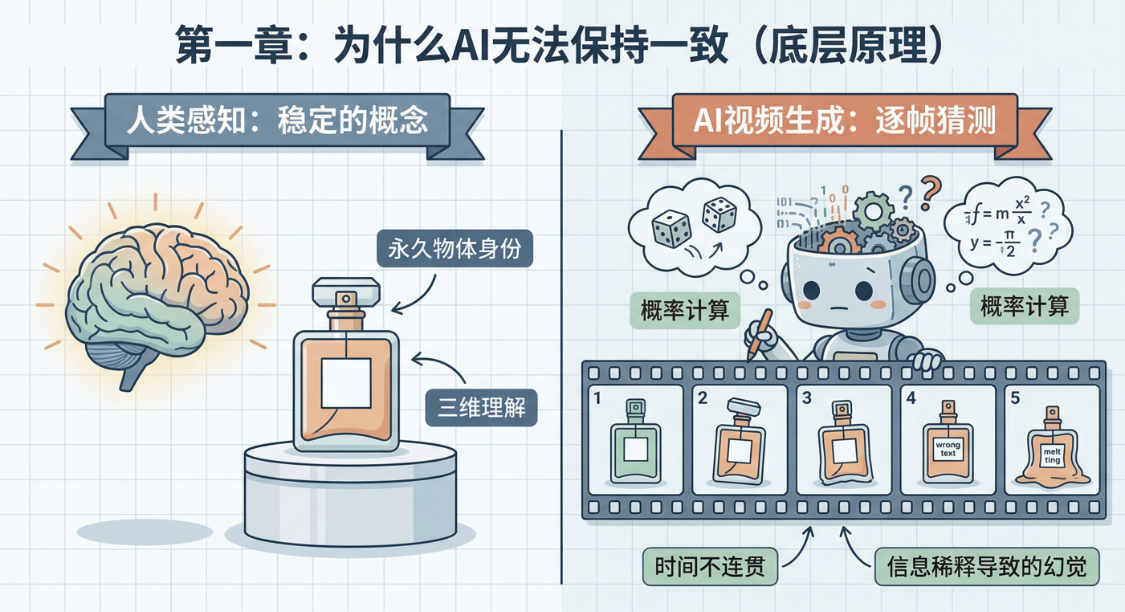
THE PROBLEM IS THE LACK OF INFORMATION DENSITY. IF YOU GIVE AI VERY VAGUE CONTROL INFORMATION
– For example, only a hint was written, or only a static product chart was provided as a frame reference
THIS INFORMATION IS RAPIDLY DILUTED DURING THE SHIFT OF THE TIME AXIS. EVEN IF YOU ARE USING THE TOP-OF-THE-ART AI MODEL IN THE CURRENT MARKET, EACH FRAME THAT YOU PRODUCE IN THE FACE OF COMPLEX MOTION TRAJECTORY AND PHOTO-CHANGES STILL PRODUCES AN ARITHMETICAL “RANDOM BIAS”, WHICH IS THE CULPRIT FOR FLASHING AND CHANGING IMAGES。
Chapter 2: Core tool readiness and characterization
To achieve pixel-level control, we need a combination of two core tools: an extremely precise image redrawing tool and a large video generation model with strong time-consistency。
Image-level redrawer: Nano Banana Pro
This is our core tool for controlling product details。
Google FLOW, with Gemini's pro-member, you'll be able to draw an infinite number of nano banana pros
Video generation and dynamic development: Clint AI / Dreamseedance 2.0
THESE TWO TOOLS ARE THE BEST IN THE CURRENT NATIONAL-GENERATED AI VIDEO MODEL. THEY HAVE EXCELLENT “TURSON VIDEO” AND “MULTI-GRAPH REFERENCE” CAPABILITIES. WE'LL USE THEM TO DIGEST THE KEY FRAMES THAT WE'VE BEEN WORKING ON, AND WE'LL LET STATIC IMAGES MOVE ACCORDING TO THE PHYSICAL PATTERNS THAT WE'VE SET。
Chapter III: High-level precision control
For high-value products (e.g. mobile phones in cases), a framework-by-frame remodelling strategy is required. At the heart of this logic is the pixel-level re-engineering of existing dynamic videos。
This is what I'm doing directly using the hints for a graphic video
Step 1: Access to raw video
This is the first video of a hand-held model. Even if the cell phone details in the video at this point are blurred, shaped or flashy in the movement, there is no need to worry. We need only modeling for the exact movement path and the location of the cell phone in space。
Step 2: Key frame and frame
Imports the original video into the cut-off software, and exports a static frame based on the lens of the image。
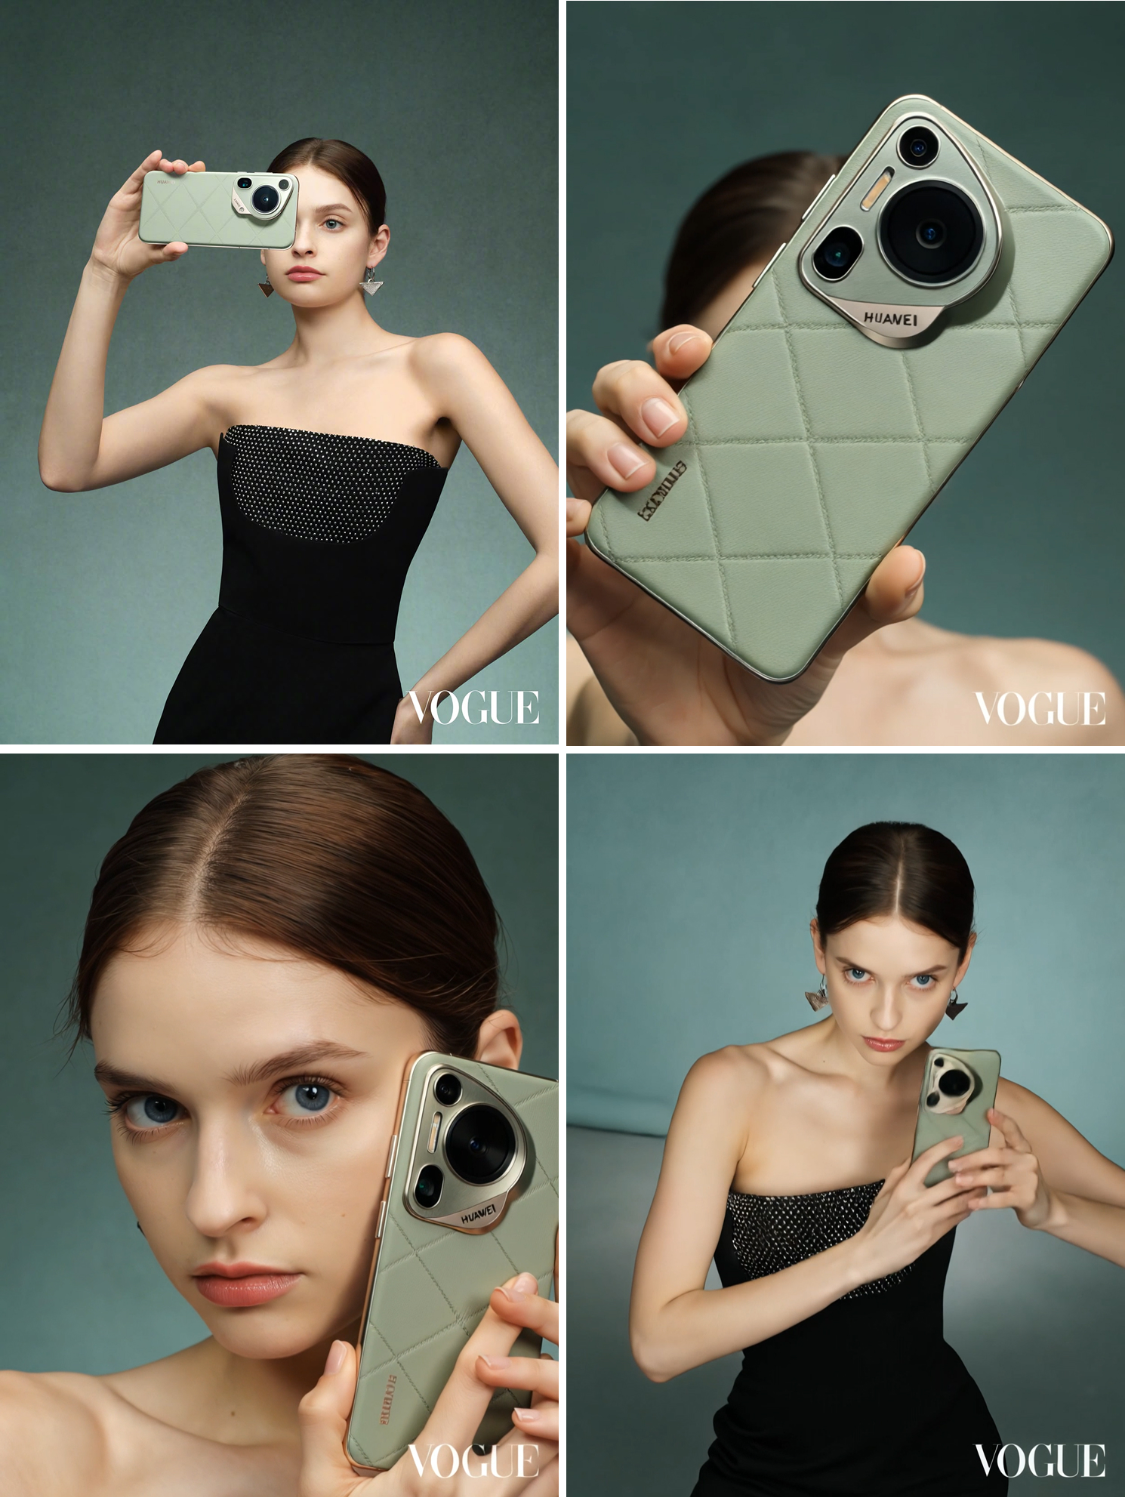
Step 3: Replace frame-by-frame product with Nano Banana Pro
This is a central step。
This post is part of our special coverage Syria Protests 2011。
Replace generation with original product maps。
The prompt words are as follows:
Replace the cell phone on the character's hand with the back of the phone in Figure 2
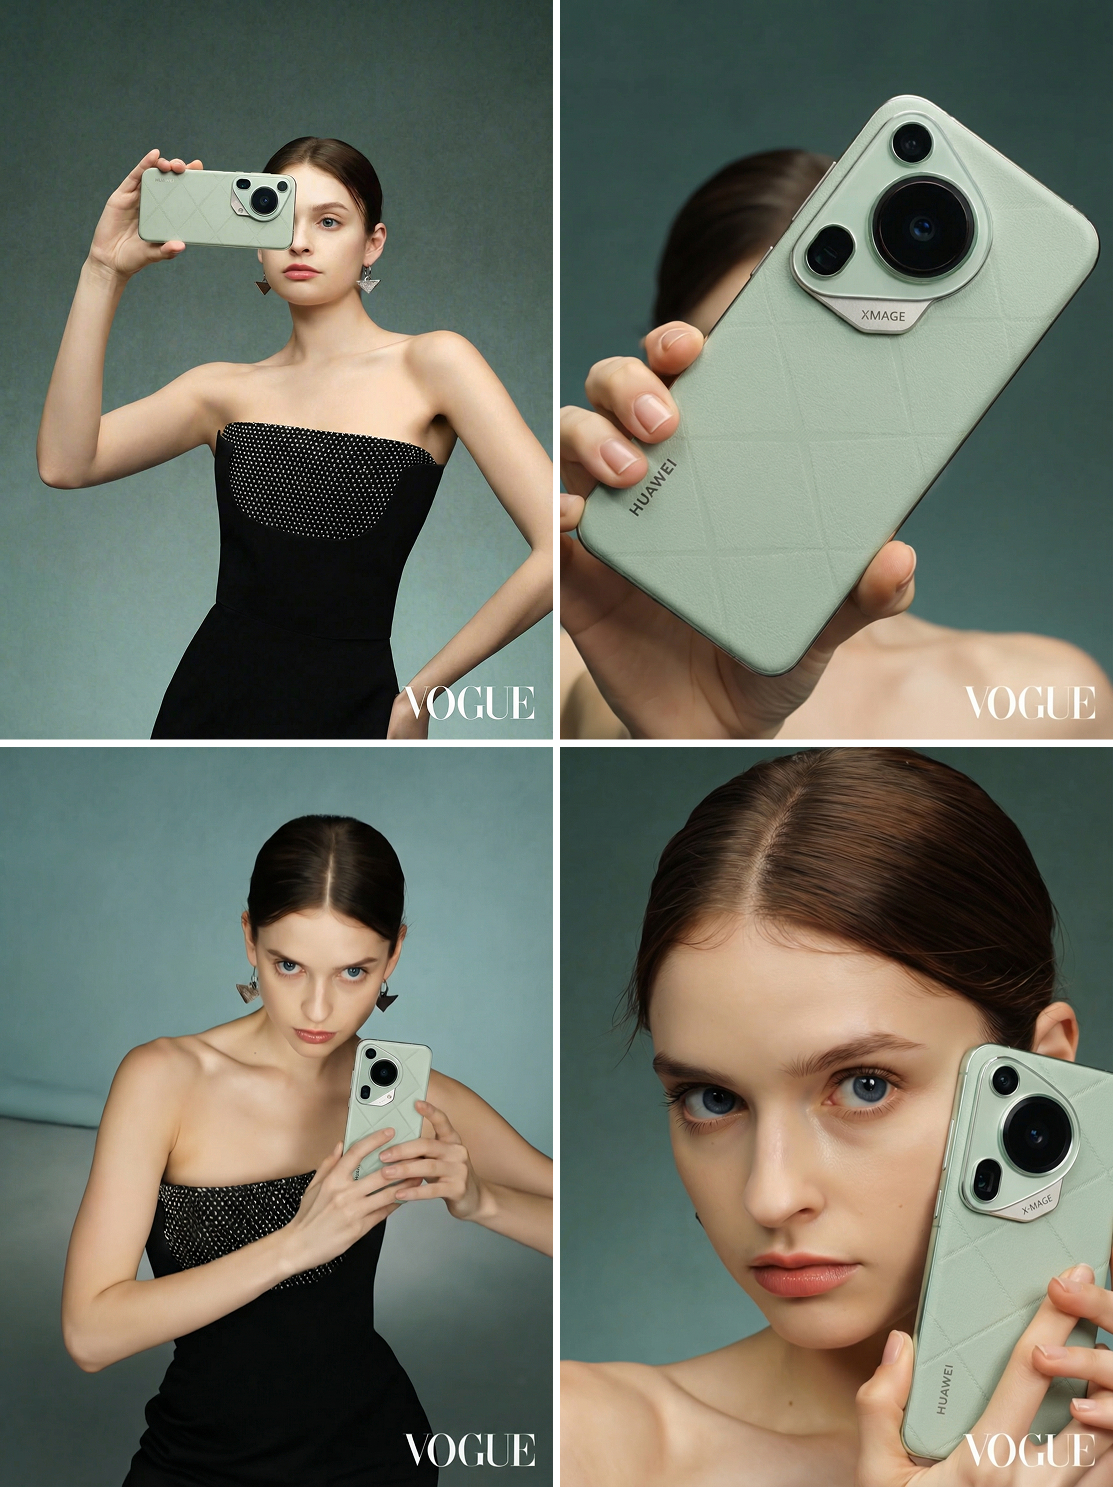
Step 4: Multigraph reference synthetic video
THE RE-ENGINEERED KEY FRAME SEQUENCES ARE RE-ENTERED INTO THE CLIN AI OR THE DREAM。
USING THEIR MULTI-CHART REFERENCE FUNCTION, ALLOW AI TO BRIDGE BETWEEN THESE VERY CERTAIN IMAGES。
BECAUSE AI HAS A “PERFECT STANDARD” AS A REFERENCE IN EACH SEGMENT, ITS FREE-PLAYING SPACE IS LOCKED TO DEATH AND THE RESULTING VIDEO WILL SHOW A VERY HIGH DEGREE OF CONSISTENCY。
Tips:
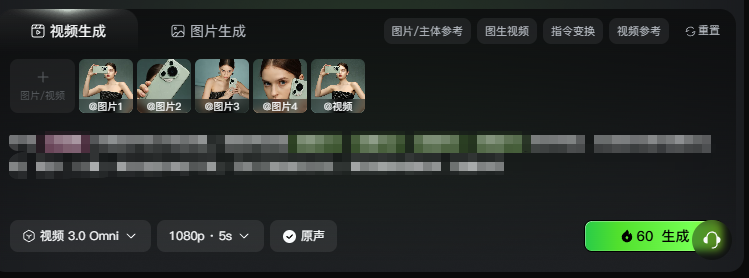
Reference Video 1 replaces the mobile phone in the video, following the sequence frame of image 1 and picture 2 and picture 3 and 4 in order, but maintains the original video mirrors, lenses, spectroscopys, and role movements remain the same. Cell phones don't melt
Chapter 4: Fast and light control
If your video is only for daily short video releases from the media, or is at the initial testing stage of an innovative programme, with high computational and time-cost requirements, and no significant space overturning of the mobile phone in the video, you can use this lighter workflow。
Compared to the tougher “frame-by-frame replacement and interpolation” in chapter III, the core of this approach lies in a very high-quality “gold single frame” to lead the whole picture。
Step one: We take the first frame
In the original video of the model going up the stairs, the first frame is intercepted。
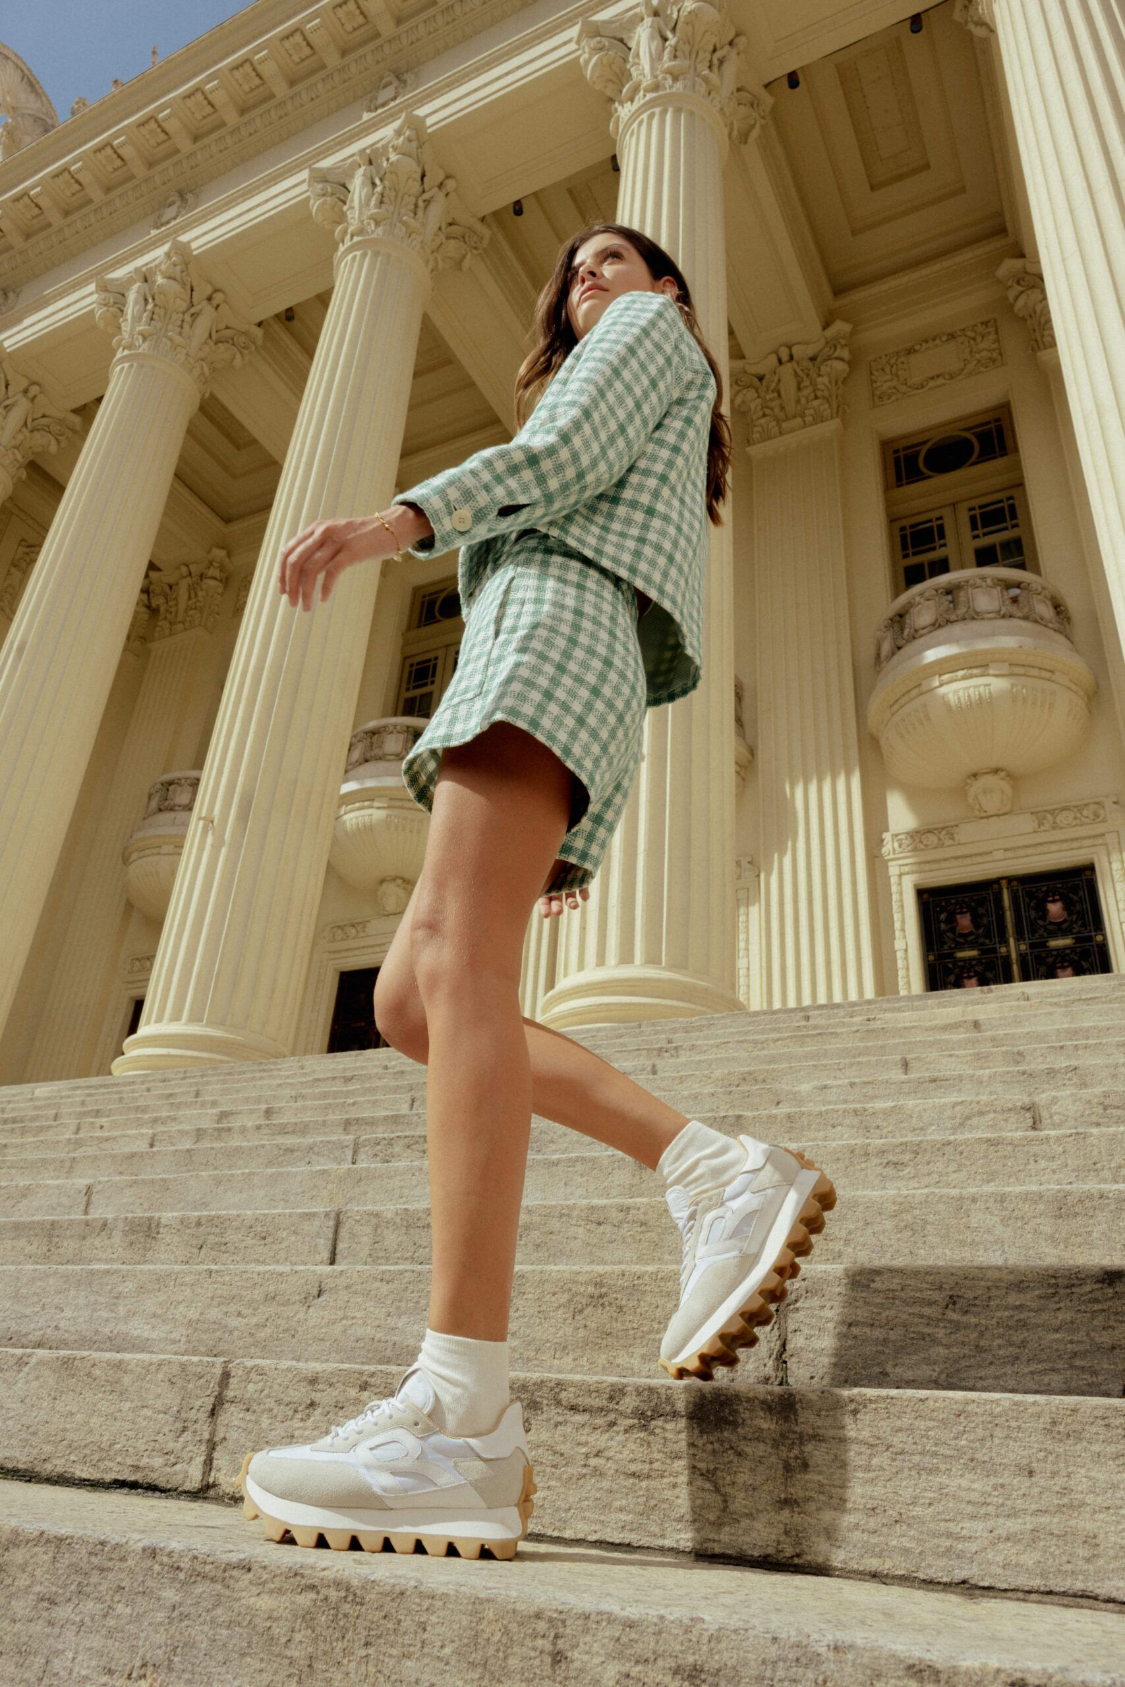
Step 2: Redraw the depth of the Nano Banana Pro single map
To upload this specs and the shoes you have to replace to Nano Banana。
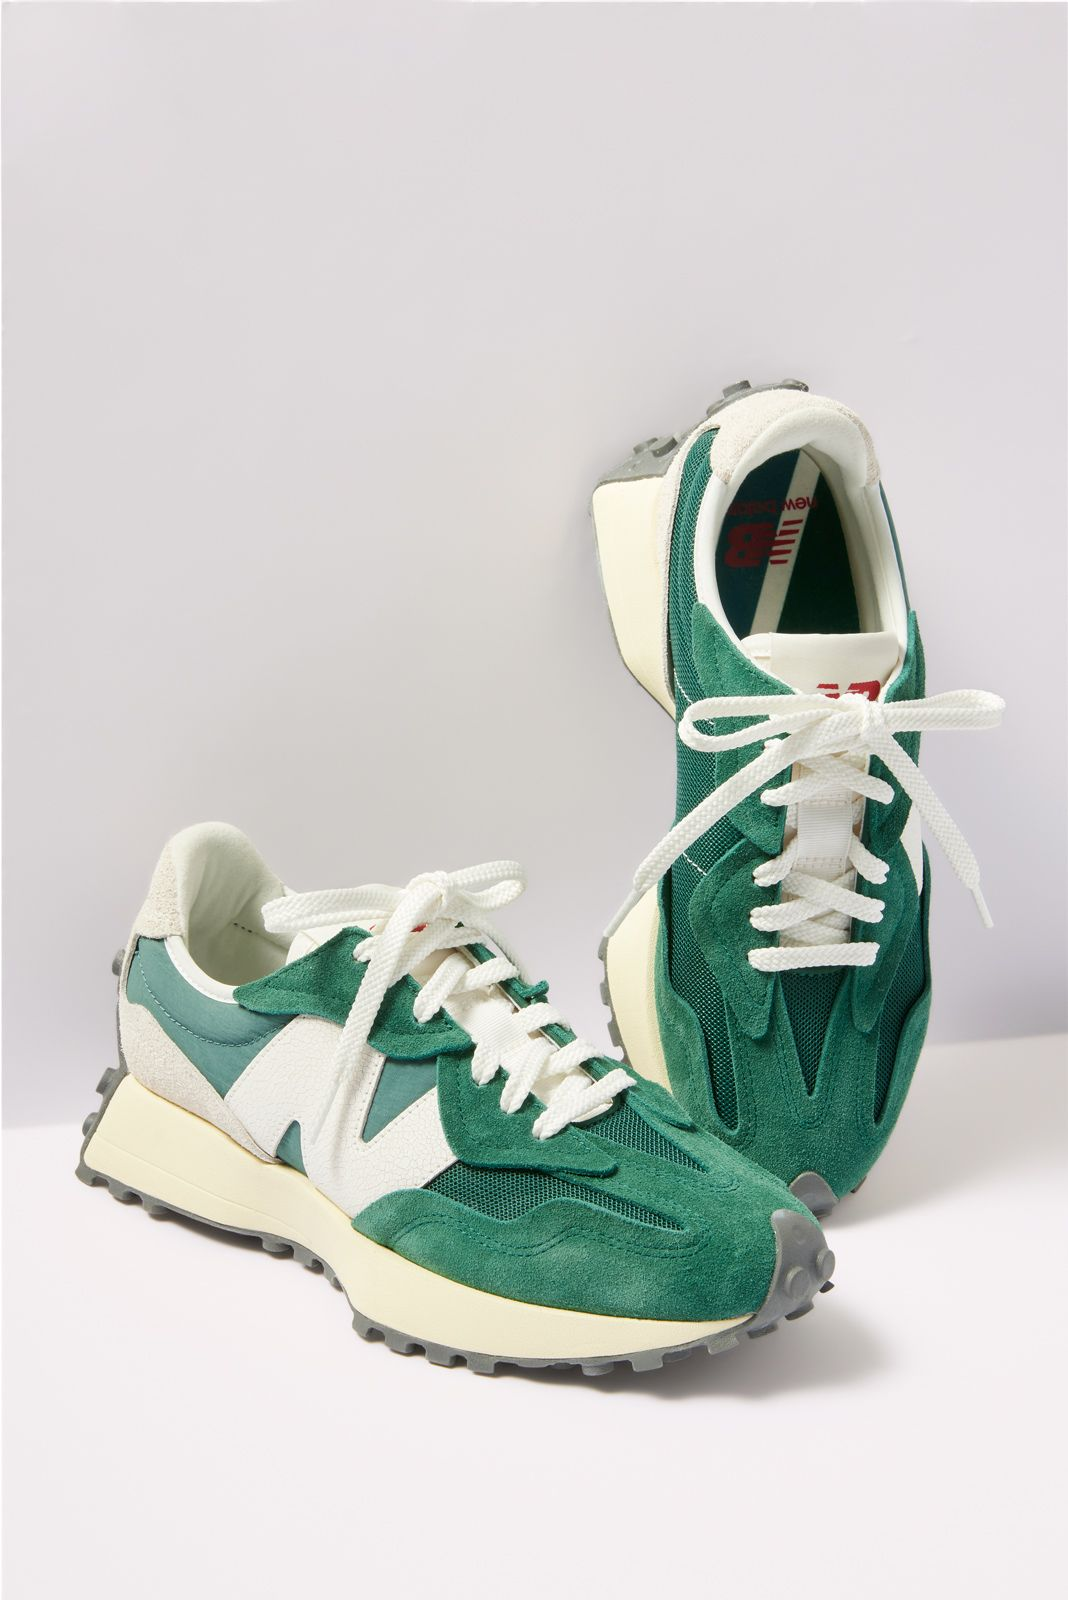
Enter hint to replace shoes:
Replace the part shoes with the Figure 2 shoes
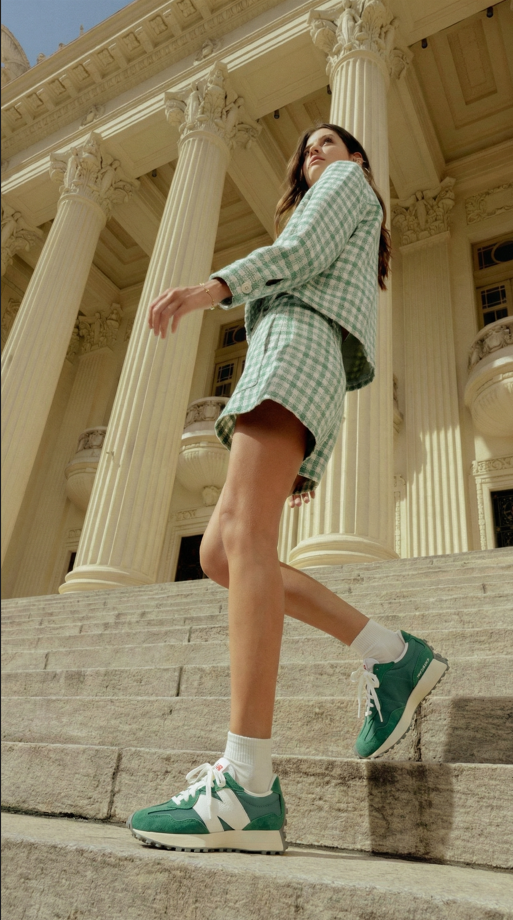
Step 3: Video synthesis
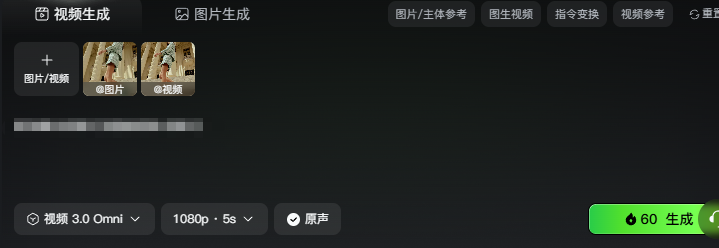
This redrawn "single frame" is presented with the original walking dynamic video, or dreamseedance 2.0。
Enter the prompt word:
Replace the shoes from the video with the shoes from Figure 1
Chapter 5: Progressive thinking and summary
The core of the solution to coherence is not the search for a “one-key generation” button, but the intensity of artificial intervention in key information。
The quest for absolute stability: using the frame-by-frame remodeling of chapter III, using the Pro version model to force the key details of every second。
(c) Efficiency: The single chart of chapter IV is used as a good reference, but attention is paid to the range of motion in camera design。