


produceAI skitsAT TIMES, MANY PEOPLE SPEND A LOT OF TIME ON ROLE PROFILES, COSTUMES, SCENES AND VISUAL CLARITY. LOOKING AT EACH PICTURE ALONE, THE PERSON IS FINE, THE IMAGE IS COMPLETE, AND THE LIGHT IS GOOD; BUT ONCE THE PICTURE IS GENERATED, THE CHARACTER IS PUSHED AROUND, THE FACE, THE CLOTHES AND THE BODY DON'T FIT, THE OPPOSITE IS MORE LIKE TWO PEOPLE STANDING ON THE LINE. THE PROBLEM IS NOT THAT THE MODEL IS NOT STRONG ENOUGH, BUT RATHER THAT THE HINT ONLY TELLS AI “WHAT TO DO” AND DOES NOT EXPLAIN HOW THE ACTION OCCURS。
THE LIFE OF THE AI SHORT PLAY COMES FROM CONTINUOUS, SPECIFIC AND INTERRELATED CHANGES. THE PERSON DOES NOT ONLY MOVE FORWARD WITH TWO LEGS, BUT ALSO LEADS TO A FORWARD TIP OF THE CENTRE OF GRAVITY, A SWING IN THE ARM, A LAG IN THE SKIRT, A SHAKING OF THE HAIR, A CHANGE IN THE BREATH AND AN EYE REACTION. IT IS NOT SIMPLY A FACE-TO-FACE STAND-UP, BUT RATHER A CHANGE OF DISTANCE, AN EXCHANGE OF VISION, A BLOCKING OF RELATIONSHIPS AND EMOTIONAL RHYTHM. THIS SECTION WILL MAKE CLEAR HOW TO MAKE THE AI ROLE TRULY “LIVE” FROM THE TOOLS SELECTION, ACTION TIPS, PERSON MOVEMENT, SOUND AND TUNING。
I. PRODUCTION OF AI SHORTS, TOOLS HAVE CHANGED
Now the video model doesn't just turn a picture into a few seconds of animation. A new generation of tools can understand text, images of people, action reference videos, sound and lens relationships at the same time, and some can generate multiple and continuous lenses at a time. Therefore, the hint cannot continue to rest on the simplistic phrase “girls come, film sense, quality”。
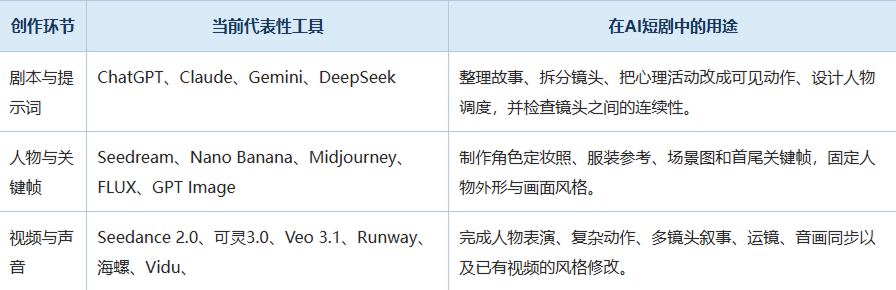
The value of Seedance 2.0 is the ability to combine text, pictures, videos and audio references. The short play can be produced by uploading a role map to a fixed person, using action video reference performances, and then texting the sequence of the lens, emotions and sound. This means that the creator does not have to insert all information into a long message, but rather allows different materials to take on their tasks。
For example, the profile of the person is determined by the role reference map, the running posture is determined by the action reference video, the emotional and lens sequence is determined by the text, and the environmental atmosphere can be supplemented by audio or style reference. This approach is more suitable for continuous character performances and multiple-scenario short dramas than it used to be based solely on words。
ii. Keeping people alive: a move has to write three layers of dynamics
THE MOST COMMON INVALID HINT IS: “GIRLS COME TO THE CAMERA, FILM SENSE, HIGH QUALITY”. THIS SENTENCE, ALTHOUGH WRITTEN, DOES NOT INDICATE THE COURSE OF ACTION. AI CAN ONLY MAKE UP FOR ITSELF, SO IT CAN BE PRONE TO SUCH PROBLEMS AS PHYSICAL SMOOTHING AND RIGIDITY。
Video alert for the negative case: Figure 1 female role in the alley of scene 2. In the ancient courtyard, a young girl in a light-coloured dress came to the camera, with a film sense, high quality, and a beautiful image. The camera is slightly back, the person is in the center of the picture。
But in this case, the same person runs from the shadows to the light, the hints are not very complicated, but the key actions are clear:
One second and four seconds to the side of the scenery and the scenery, the shallow. Shen Zhou-moon raised the issue of broken skirts and ran fast from cold blue alleys to the light market. The camera closes her horizontally, and the warm gold light gradually covers her face. The hair, the cape and the ears ran and ran. Sound: Footsteps, light market people coming in。
The first level is physical action。
The reference to the "battered skirts" “runs fast from the cold blue alley to the light market” is written here to clarify the movement, direction and speed of the person. She did not do it in place, nor did she simply do it in flat motion, but ran from the alley to the light market, with a clear starting and end。
The second level is following the move。
The phrase “Hair, cape and ear crashes” allows clothing, hair and accessories to react with the body. When people run, the accessories do not remain static, so that these changes can significantly reduce the sense of plastic。
The third level is environmental change。
The phrase “heating gold light gradually covers her face” is crucial. It allows the person to move not in a fixed light, but from the cold blue alley to the warm gold light market. As she approached the light market, so did the face light, the picture had a spatial dimension and emotional advance。
The fourth level is voice connection。
“The sound of footsteps, the sound of the light market is coming closer”, allowing the audience not only to see the person running, but also to feel that she is approaching a more popular space. The sound is coming from a distance, and it corresponds to the direction of movement in the picture。
So, for an action to be true, it does not have to have a lot of adjectives, but rather to have the action, the clothes, the light, the sound。
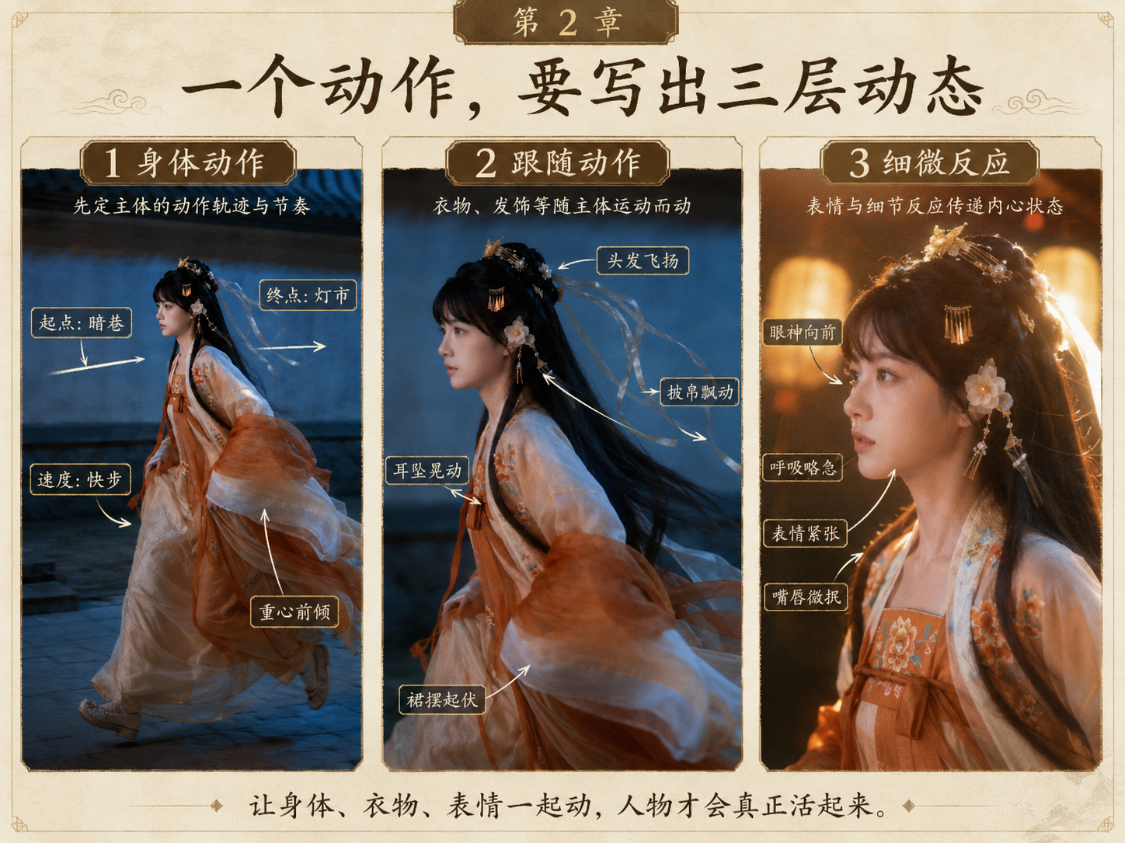
Three-layer dynamic formula:
The main + position moves with body action + the action of clothing, hair or props + light or environmental change + sound connection + lens approach + stability limit。
THIS CASE DEMONSTRATES THAT THE ACTION HINT DOES NOT HAVE TO BE LONG, BUT MUST BE STRUCTURED. "GIRLS RUN TO THE LIGHT MARKET" AND AI CAN ONLY UNDERSTAND THE RESULT OF ONE MOVE; IT CAN ONLY READ "SIDES AND CLICKS, LIFTS THE DOTS, RUNS FROM COLD BLUE AND DARK ALLEYS TO WARM AND GOLDEN LIGHTS, HAIRS CRUMBLING IN THEIR EARS, FOOTSTEPS AND HUMAN VOICES COMING CLOSER" AND "AI CAN UNDERSTAND THE MOVEMENT, SPATIAL CHANGES AND EMOTIONAL RHYTHM."。
The omnipotent hints are as follows (put your role/scenario and the following hints to a large language model, that is):
Please generate an action alert for the drawing video based on the role, scene or picture I'm providing。
It is requested not to re-engineer and not to change the face, five officials, clothing, hair, makeup, accessories, background and overall style of the person。
Please write around a major move. Do not pile too many. The action requires three layers:
On the first level, the physical actions of the person, including from where to where, the speed of the movement, the direction of the body, the shift of the centre of gravity, the rise and the ending, are clearly written。
On the second level, it is clear how the actions followed, including the hair, clothes, skirts, caps, accessories, props, environmental objects, as a result of their physical changes, are to be in real physical relationships。
On the third level, write a clear and nuanced reaction, including a small change in the person ' s eyes, breath, blinking, mouth, eyebrow, shoulder or hand, which gives the movement a clear emotion。
It also supplements the lens, the scenery, the mirrors, the light changes and the sound details. The final hint should be a three-to-five-second video, act naturally, and the image is stable. It avoids thawing, deformation of limbs, facial scintillation, rigid clothing, background vibrating, change of character and subtitles。
Only output the final video hint, do not explain。
III. RELEVANCE OF THE COMPETITION: TO REPLACE THE POINTS WITH THE TRANSPORT OF PEOPLE
Single-person lenses address action issues, while double-person lenses address position, vision, distance, blocking and interaction. If two people stand face to face from beginning to end, even if the picture is beautiful, it is difficult to create a dramatic feeling。
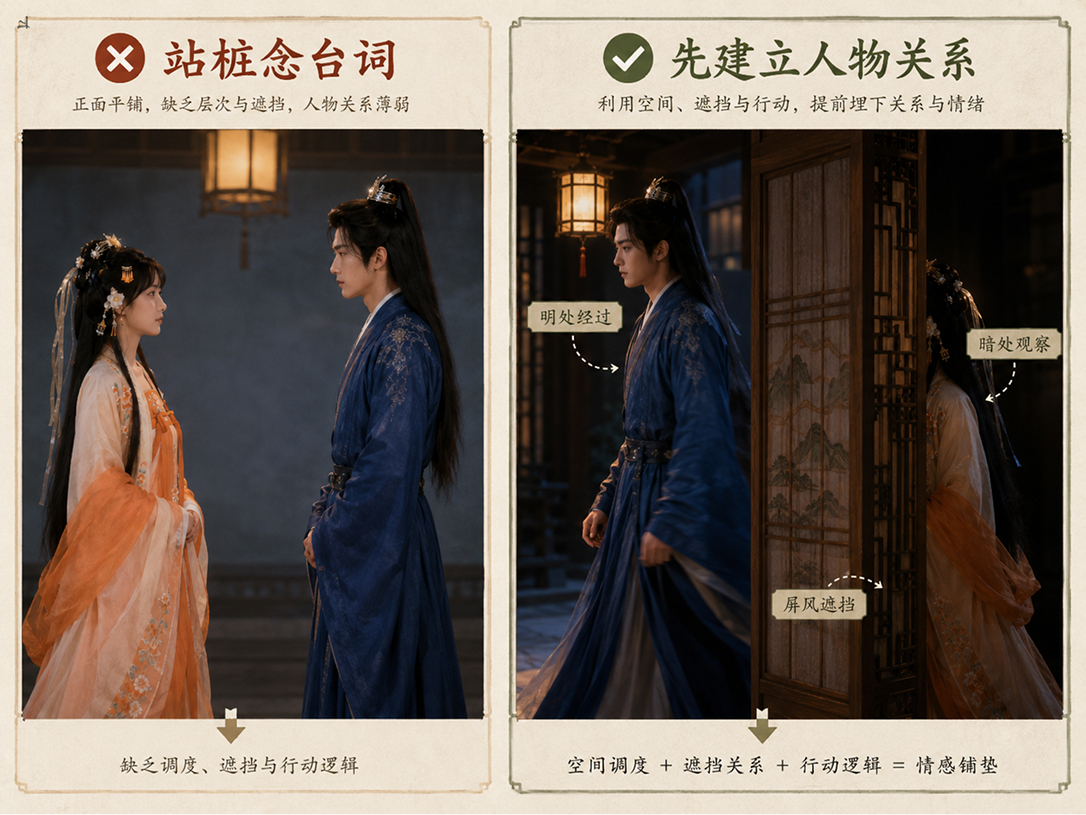
It's easy to write when a lot of rookies are playing the competition:
"Sing Zhou-moon went to Pei-Chou and said, "Son, stay."
While this is an expression of the story, it is easy for the picture to become two people standing together to read the lines. It is difficult for the audience to feel that this is happening without the person entering the process, without observation, without reaction and without distance。
A better way to do that would be to break down a simple phrase, “Call him down”, into a group of people's movements。
Correct case
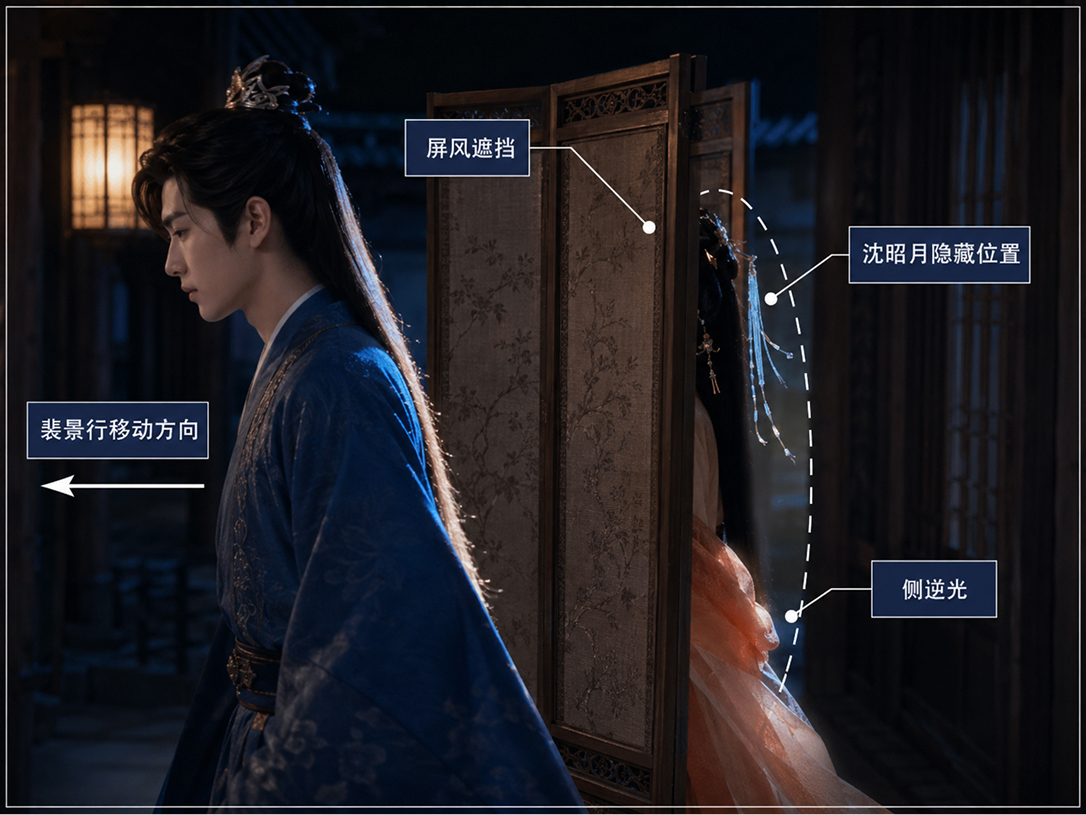
In the correct case, for example, Shen Suzuki did not appear directly in front of Pei, but hid behind the screen. Pei-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai. This shot first created a position relationship between two people: one passing through the street and one watching in the dark。
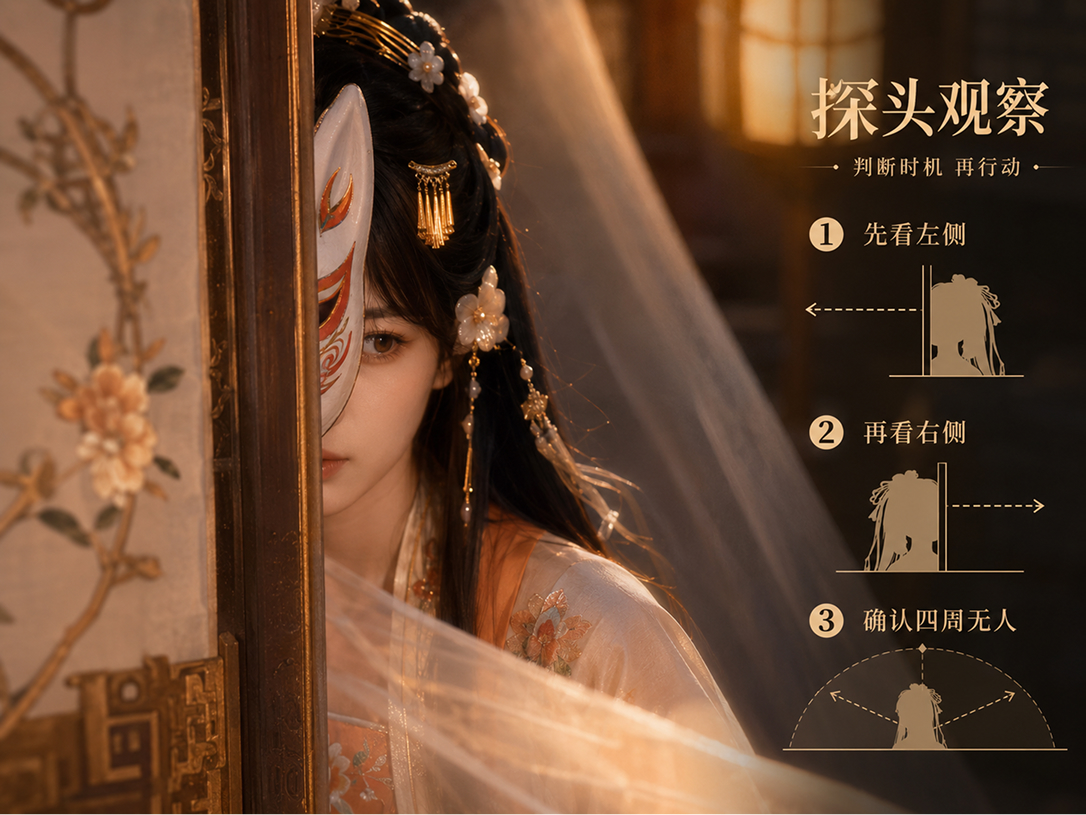
Shen Zhou Moon then looked out on the edge of the screen and showed only half a fox mask and one eye. She looked to the left and then quickly looked to the right, confirming that there was no one around. This move gives the character a clear purpose, and she is not just showing up, but judging the moment。
In the third shot, Shen Zhou Moon raised the two sides of the skirt, walked out of the screen and went towards Pei. The camera was close to her lateral movement, and the skirts were glittering and running in the reverse light. There are not only movements of people, but also changes in clothing, accessories and light. When she shouted “Dude, stay”, the line was no longer an isolated voice, but a movement。
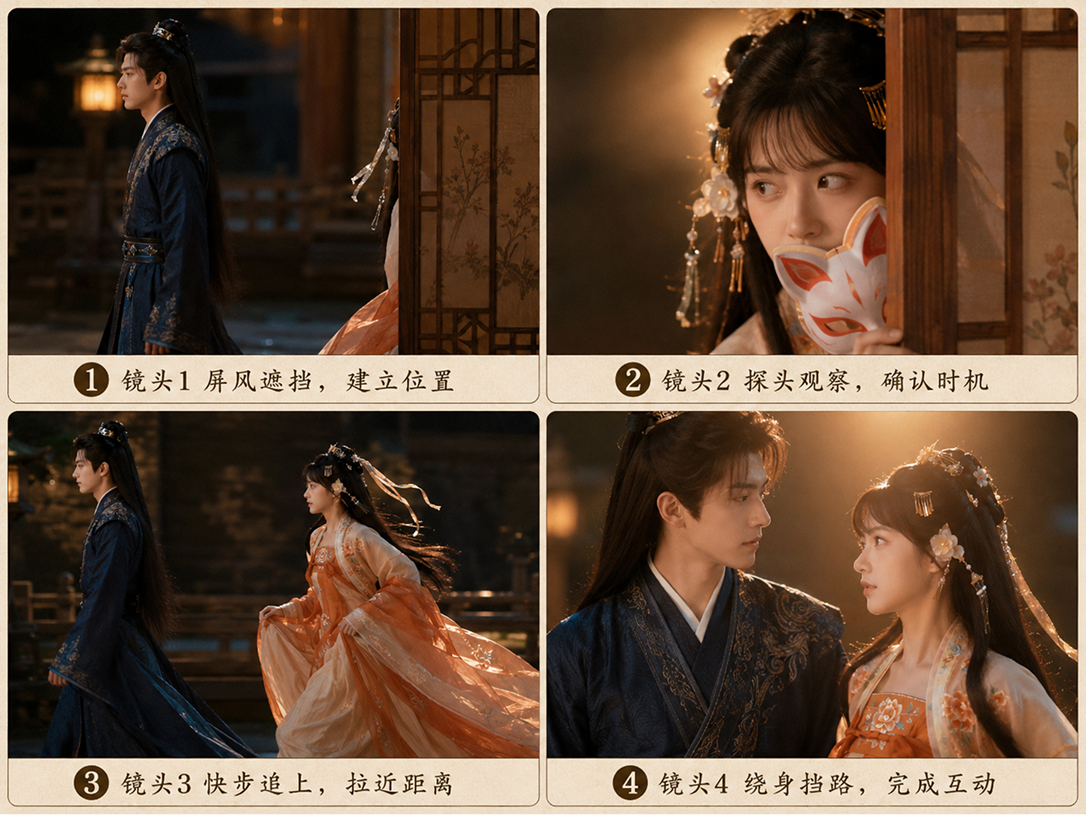
Last shot, Pei King stopped and just turned right. Shen Zhouzuki quickly went around the other side from behind him and first broke into the picture and blocked his way. This move made it possible to establish a relationship between the two people: it was not just the same thing, it was Shen Zhoumoon who took the initiative to change the course of action for Pei。
That's the role of "person movement" in the competition。
It does not allow two people to speak in the picture, but rather makes a relationship between the person through the actions of blocking, observing, approaching, chasing, bypassing and blocking。
The movement of this case is very clear:
Camera one, use a screen to make a cover relationship。
Camera two, use a spy and a left and right view to express the purpose of the person。
Camera three, catch up with speed。
Camera four, go around the front and block the interactive results。
Correct case spectroph:
Spectroscope
Camera 1 in 4 seconds in a close view. The Pei-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai-Cai. The screen can only be followed by a silver twitch and a small pink horn. Sound: The flat footsteps of Pei。
Camera two and four seconds close-up on Shen. She looked out on the edge of the screen and showed only half a fox mask and one eye. She looked to the left and then quickly looked to the right, confirming that there was no one around. Foreground curtains gently swept her face。
Camera three and four seconds in the body, horizontal and horizontal, without showing the big environment. Shen Zhoumoon took up the skirts and walked out of the screen and headed for Pei. The camera was close to her lateral movement, and the skirts were glittering and running in the reverse light. Shen Shozuki: "Son, stay."
Camera four and three seconds double view. Bae-Chou stopped and just turned right. Shen Zhou-moon quickly went around the other side from behind him, first breaking into the picture and blocking his way。
That's how two-man scheduling tips are understood
When you write your opponent's play, you don't think about what they want to say, but about four questions:
Who showed up first
Who found out who first
How does the distance change
Who changed his action
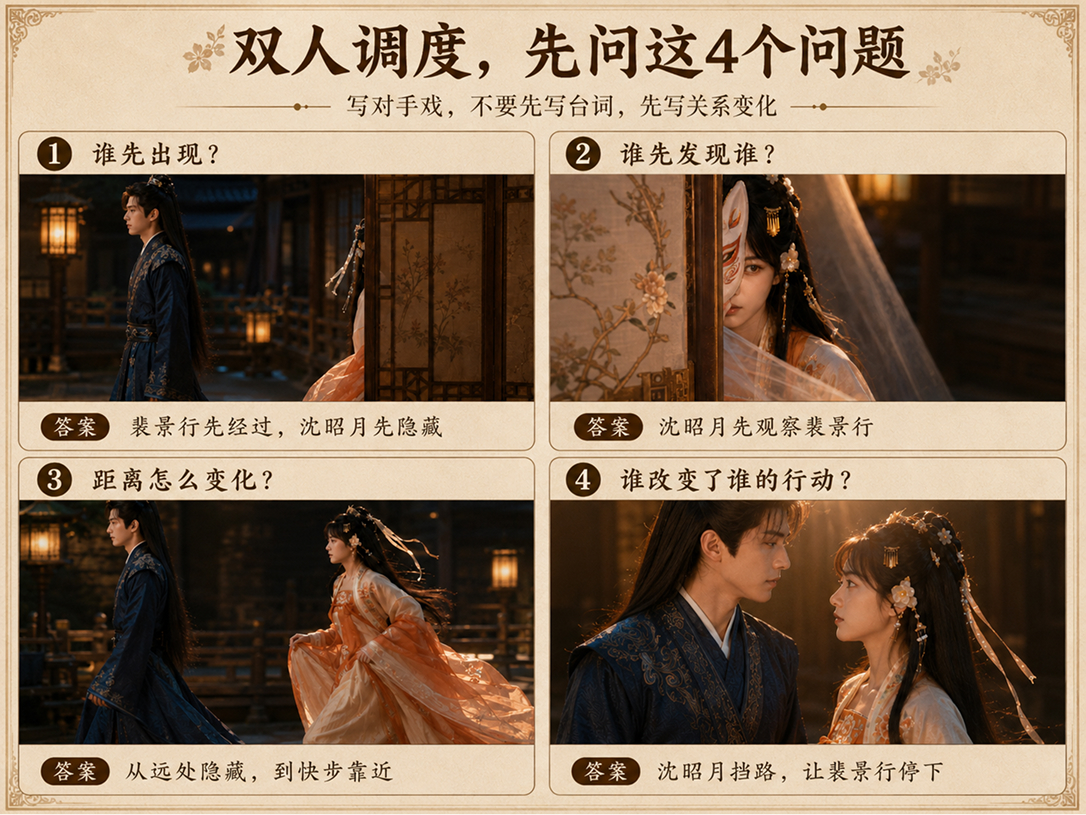
Multi-photo scheduling thinking:
Multi-censor rivalry does not necessarily have to have a fixed formula, but rather to figure out how this relationship happens。
We can start in these directions:
First, to determine the initial relationship between the two persons。
Are they in the dark, in the distance, on the back, across the screen, or are they already in the same picture
Second, design a trigger point。
It can be a footsteps, a look back, an eye, a line, a props, or one of them suddenly approaching。
Thirdly, let one act first and the other react。
For example, the hostess first looked at the head and the man continued to pass; the hostess followed up and stopped; the master had just turned around, and the mistress blocked the way first。
Fourth, connect the camera with action, sight, sound or mask。
So each shot is not an isolated image, but a continuous change in the same period of interaction。
Instead of just two characters, write about how they find each other, how they approach each other and how they affect each other。
IV. SOUND AND TRANSITION: REHABILITY OF THE IMAGE
soundscape
Now, Seedance 2.0 automatically produces basic sound effects in most cases, such as environmental sound, footsteps, human atmosphere, clothing frictions, etc., so each segment does not need to be re-engineered。
But there are some key voices that it would be better to fill in later。
For example, when a person stops, the sound of the foot stops; when the hostess approaches the back of the screen, she can add a slight graze of clothing; and when she moves, the cup falls on the table, the door is pushed open and the cuffs wipe the back of her hands, the details of which, if filled, will make the action more real。
Only a small amount of emotional sound can be added to the plot。
For example, when two people suddenly look at each other, they can make the environment a little softer or add a very light acoustic sound; when a person discovers an anomaly, they can add a little bit of a low-frequency sound; and the hostess can block the male master's path for an instant or add a slight emotional accent。
But the sound is not too full, but the focus is on key movements and emotional changes。
59G Audio Package Sharing (100 degrees Internet download) Ripping code: cjgt
https://pan.baidu.com/s/1vRzf4MB_VnwADuGD7eCLog
mix colors
The modulation of women ' s short operas is not too complex, and the focus is on making the picture softer, more fantastic and more arousal。
My approach is usually to add a "fantasy light" effect to the clip, and then to adjust the number to the image。
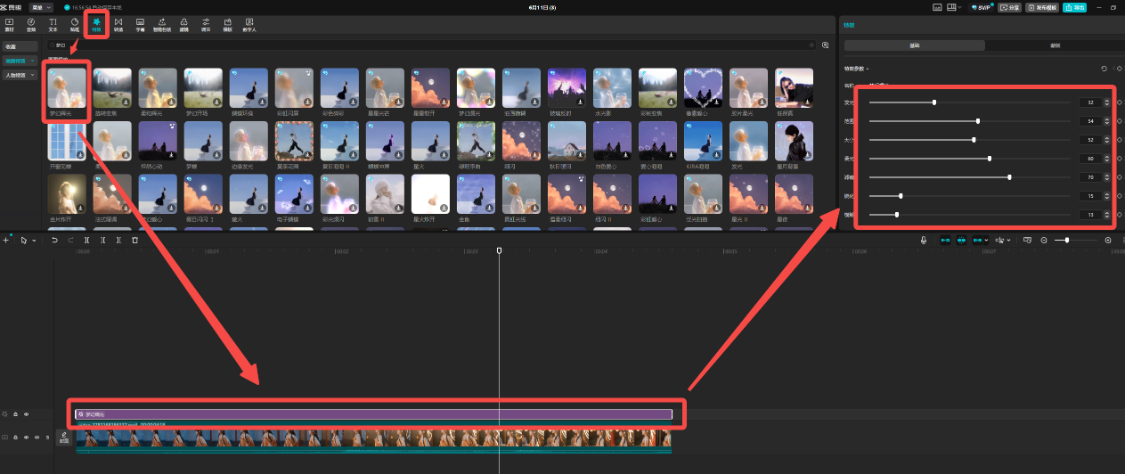
If the picture is too hard, add a little light; if the person's face is bright, don't add too heavy, or it's easy to pass out the details. In particular, images of ancient women, with appropriate light, can make light, hairdressing, curtains and the edges of clothing better。
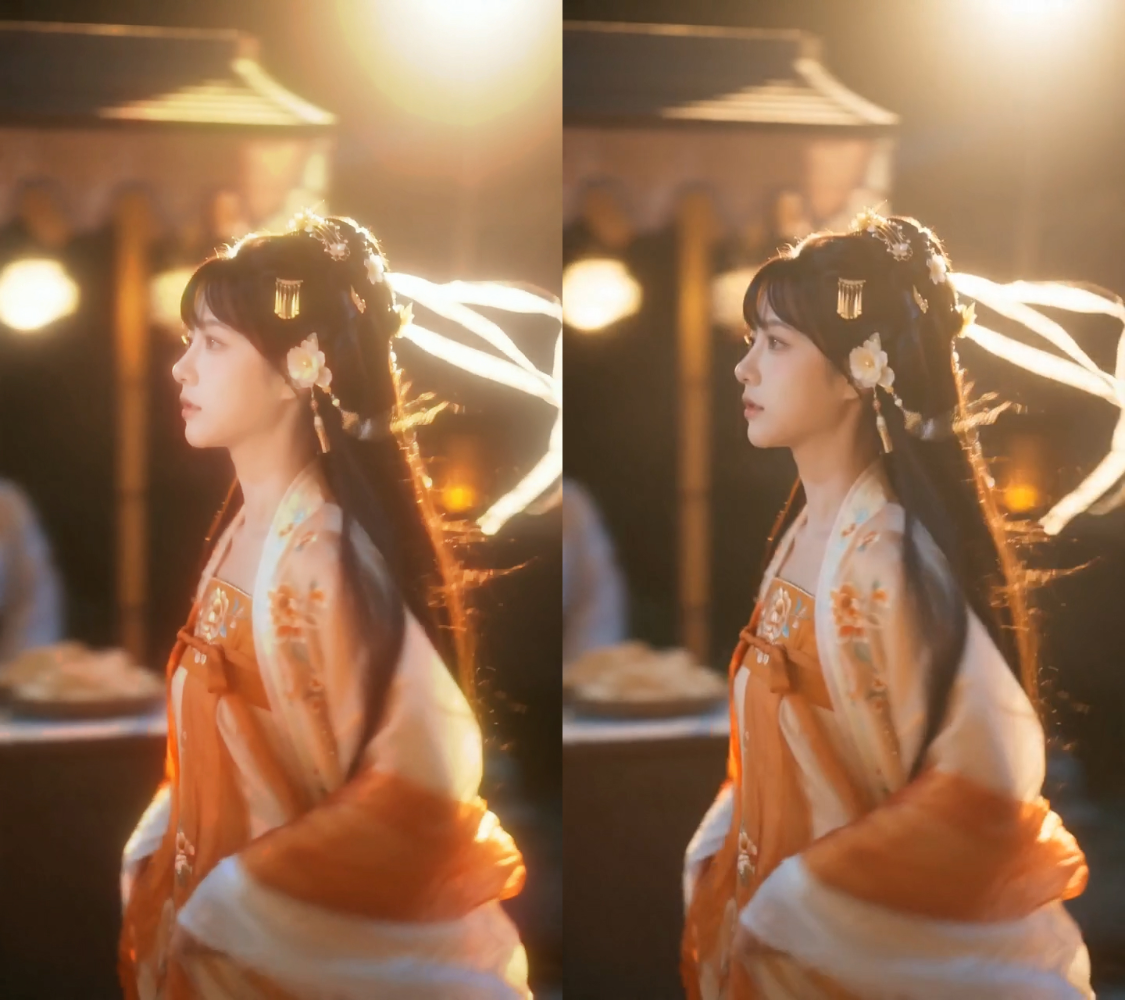
Add a glamorous contrast
In short:
Let's start with the dream light, make a soft atmosphere。
Regulate strength to avoid exposure to the person's face。
The final check is whether the person is clear and whether the tone of the lens is uniform。
Women ' s shorts don ' t have to be complex, they need to be soft, clean and emotional。
Cut the LUT package as follows (100-degree download)
https://pan.baidu.com/s/1nwvQaTO5auVlebw2BPvx-A
Conclusion
THE KEY TO THE AI SHORT PLAY IS NOT TO WRITE THE HINTS LONGER AND LONGER, BUT TO MAKE EACH ONE CLEAR。
When writing a single person's move, do not simply write " run, walk, turn back " , but rather tear it down to physical action, follow action and micro-response. The details of how people move, how clothes, hair, accessories are driven, how eyes and breath change, so the role does not move like a model。
Don't let just two people speak in the box when you're writing the competition. A really interesting picture often comes from the movement of people between people: who comes first, who is watching, who is triggered by the sound, who comes in and who changes the actions of the other. As in the case of Shen Shen Moon, who observed behind screens, followed Pei King and blocked the road in front of him, there were few lines, but personality relations had been manifested in action。
Sound and later is also important. Seedance 2.0 usually produces most of the basic sound effects, but the acoustic effect of the key actions, the acoustic acoustics that drive the mood, needs to be replaced later. The modulation of the women's short play is not complicated, and a “dream light” is cut in the image, and the number is adjusted to the image, so that a soft, clean, emotional atmosphere can be created quickly。
SO, THE MESSAGE OF THE SHORT PLAY IS NOT JUST A PICTURE, BUT A PERFORMANCE. PEOPLE'S MOVEMENTS, CLOTHING RESPONSES, EYE EMOTIONS, CAMERA MOVEMENTS, VOICE DROPS AND VIDEO ATMOSPHERES ARE ALL COMPATIBLE, SO THAT THE ROLE CAN COME OUT OF STATIC IMAGES, AND THE SHORT PLAY CAN BE TRULY RHYTHMIC, RELEVANT AND LIVE。